"OpenHands:AI 软件开发者通用智能体的开放平台"
"OpenHands: An Open Platform for AI Software Developers as Generalist Agents"
推荐全译对照查看原文(PDF) ↗
导读
本文是第 9 周「编程智能体」的平台级论文(ICLR 2025,Neubig 组 + All Hands AI)。如果说 SWE-agent 揭示了"智能体-计算机接口(ACI)"的重要性,OpenHands 回答的是下一层问题:一套让社区能一起开发、安全执行、统一评测智能体的开放基础设施。它的设计立场鲜明——人类改变世界最强大的方式是软件,所以让智能体"像人类开发者那样"用写代码、跑命令、浏览网页来行动。技术上四大件:(1)事件流架构(Action/Observation 追加式历史,UI/智能体/环境三方共享);(2)Docker 沙箱运行时(bash + IPython + Playwright 浏览器,任意镜像可装 action execution API);(3)CodeAct 动作空间(用执行代码代替 JSON 函数调用,足够通用且可自造工具)+ AgentSkills 可扩展技能库;(4)多智能体委派(AgentDelegateAction)。评测覆盖 15 个基准:同一个 CodeAct 智能体不改系统提示,在 SWE-bench Lite 26%、WebArena 15.3%、GPQA 52% 等三类任务上都具竞争力——专基线各有单项更强,但通用性无人能敌。MIT 协议、188+ 贡献者、32K star,是学术与工业都能直接用的底座。
全文对照翻译
译注:覆盖论文正文全部内容(标题与摘要、第 1-5 节,原文第 1-10 页)。References 与其后的附录 A-J(局限与未来工作、伦理声明、相关工作、用户界面、框架质量保障、运行时实现细节、GPQA 其他子集、AgentSkills 完整清单、浏览器动作全集、BrowsingAgent 完整提示词等)未收录,请查阅原文 PDF;要点已浓缩在文末"要点速览"。术语首现处给中英对照:事件流(event stream)、动作执行 API(action execution API)、AgentSkills(智能体技能库) 等;LLM、Agent、Docker、bash 等通用英文缩写保留原文。原文表 1 的 ✓/✗ 符号在文本提取中有乱码,已对照 arXiv v3 版本核校修正。
标题与作者
OpenHands: An Open Platform for AI Software Developers as Generalist Agents
Xingyao Wang, Boxuan Li, Yufan Song, Frank F. Xu, Xiangru Tang, Mingchen Zhuge, Jiayi Pan, Yueqi Song, Bowen Li, Jaskirat Singh, Hoang H. Tran, Fuqiang Li, Ren Ma, Mingzhang Zheng, Bill Qian, Yanjun Shao, Niklas Muennighoff, Yizhe Zhang, Binyuan Hui, Junyang Lin, Robert Brennan, Hao Peng, Heng Ji, Graham Neubig
1UIUC 2CMU 3Yale 4UC Berkeley 5Contextual AI 6KAUST 7ANU 8HCMUT 9Alibaba 10All Hands AI
xingyao6@illinois.edu, gneubig@cs.cmu.edu
OpenHands:AI 软件开发者作为通用智能体的开放平台
作者:Xingyao Wang、Boxuan Li、Yufan Song、Frank F. Xu、Xiangru Tang、Mingchen Zhuge、Jiayi Pan、Yueqi Song、Bowen Li、Jaskirat Singh、Hoang H. Tran、Fuqiang Li、Ren Ma、Mingzhang Zheng、Bill Qian、Yanjun Shao、Niklas Muennighoff、Yizhe Zhang、Binyuan Hui、Junyang Lin、Robert Brennan、Hao Peng、Heng Ji、Graham Neubig
机构:UIUC、CMU、Yale、UC Berkeley、Contextual AI、KAUST、ANU、HCMUT、Alibaba、All Hands AI
本文发表于 ICLR 2025(第十三届国际学习表征会议);代码见 github.com/All-Hands-AI/OpenHands,社区 Slack 见 bit.ly/OpenHands-Slack。
摘要
Software is one of the most powerful tools that we humans have at our disposal; it allows a skilled programmer to interact with the world in complex and profound ways. At the same time, thanks to improvements in large language models (LLMs), there has also been a rapid development in AI agents that interact with and affect change in their surrounding environments. In this paper, we introduce OpenHands (f.k.a. OpenDevin), a platform for the development of powerful and flexible AI agents that interact with the world in similar ways to those of a human developer: by writing code, interacting with a command line, and browsing the web. We describe how the platform allows for the implementation of new agents, safe interaction with sandboxed environments for code execution, coordination between multiple agents, and incorporation of evaluation benchmarks. Based on our currently incorporated benchmarks, we perform an evaluation of agents over 15 challenging tasks, including software engineering (e.g., SWE-Bench) and web browsing (e.g., WebArena), among others. Released under the permissive MIT license, OpenHands is a community project spanning academia and industry with more than 2.1K contributions from over 188 contributors.
软件是人类手中最强大的工具之一,它让熟练的程序员能以复杂而深刻的方式与世界交互。与此同时,得益于大语言模型(LLM)的进步,能与周围环境交互并施加改变的 AI 智能体也在快速发展。本文介绍 OpenHands(原 OpenDevin)——一个用于开发强大而灵活的 AI 智能体的平台,这些智能体以与人类开发者相似的方式与世界交互:编写代码、与命令行交互、浏览网页。我们描述该平台如何支持:实现新智能体、与沙箱化代码执行环境的安全交互、多智能体之间的协调,以及评测基准的整合。基于已整合的基准,我们在 15 个有挑战的任务上评测智能体,包括软件工程(如 SWE-Bench)与网页浏览(如 WebArena)等。OpenHands 以宽松的 MIT 协议开源,是横跨学界与工业界、拥有 188+ 贡献者、2.1K+ 贡献的社区项目。
1 引言
Powered by large language models (LLMs; OpenAI 2024b; Team et al. 2023; Jiang et al. 2024; Chang et al. 2024), user-facing AI systems (such as ChatGPT) have become increasingly capable of performing complex tasks such as accurately responding to user queries, solving math problems, and generating code. In particular, AI agents, systems that can perceive and act upon the external environment, have recently received ever-increasing research focus. They are moving towards performing complex tasks such as developing software (Jimenez et al., 2024), navigating real-world websites (Zhou et al., 2023a), doing household chores (Ahn et al., 2022), or even performing scientific research (Boiko et al., 2023; Tang et al., 2024a).
在大语言模型(LLM;OpenAI 2024b;Team et al. 2023;Jiang et al. 2024;Chang et al. 2024)的驱动下,面向用户的 AI 系统(如 ChatGPT)已越来越有能力执行复杂任务,如准确回应用户查询、求解数学问题、生成代码。尤其是 AI 智能体(agent)——能够感知外部环境并对其采取行动的系统——近来获得了前所未有的研究关注。它们正迈向更复杂的任务:开发软件(Jimenez et al., 2024)、在真实网站中导航(Zhou et al., 2023a)、做家务(Ahn et al., 2022),甚至开展科学研究(Boiko et al., 2023;Tang et al., 2024a)。
As AI agents become capable of tackling complex problems, their development and evaluation have also become challenging. There are numerous recent efforts in creating open-source frameworks that facilitate the development of agents (Hong et al., 2023; Chen et al., 2024; Wu et al., 2023). These agent frameworks generally include: 1) interfaces through which agents interact with the world (such as JSON-based function calls or code execution), 2) environments in which agents operate, and 3) interaction mechanisms for human-agent or agent-agent communication. These frameworks streamline and ease the development process in various ways (Tab. 1, §C).
随着 AI 智能体有能力处理复杂问题,它们的开发与评测也变得颇具挑战。近来已有大量创建开源框架以促进智能体开发的工作(Hong et al., 2023;Chen et al., 2024;Wu et al., 2023)。这些智能体框架通常包含:1) 智能体与世界交互的接口(如基于 JSON 的函数调用或代码执行);2) 智能体运行的环境;3) 人-智能体或智能体-智能体之间的通信机制。这些框架以各种方式简化并降低了开发流程的难度(表 1、§C)。
When designing AI agents, we can also consider how human interacts with the world. The most powerful way in which humans currently interact with the world is through software – software powers every aspect of our life, supporting everything from the logistics for basic needs to the advancement of science, technology, and AI itself. Given the power of software, as well as the existing tooling around its efficient development, use, and deployment, it provides the ideal interface for AI agents to interact with the world in complex ways. However, building agents that can effectively develop software comes with its own unique challenges. How can we enable agents to effectively create and modify code in complex software systems? How can we provide them with tools to gather information on-the-fly to debug problems or gather task-requisite information? How can we ensure that development is safe and avoids negative side effects on the users' systems?
设计 AI 智能体时,我们也可以参考人类如何与世界交互。当前人类与世界交互最强大的方式就是软件——软件支撑着我们生活的方方面面,从满足基本需求的物流,到科学、技术与 AI 自身的发展。鉴于软件的力量,以及围绕其高效开发、使用与部署的成熟工具链,软件为 AI 智能体以复杂方式与世界交互提供了理想的接口。然而,构建能真正有效开发软件的智能体有其独特的挑战:如何让智能体在复杂软件系统中有效地创建与修改代码?如何为它们提供即时(on-the-fly)收集信息的工具,以调试问题或获取任务所需的信息?如何确保开发过程是安全的、不会对用户的系统造成负面副作用?
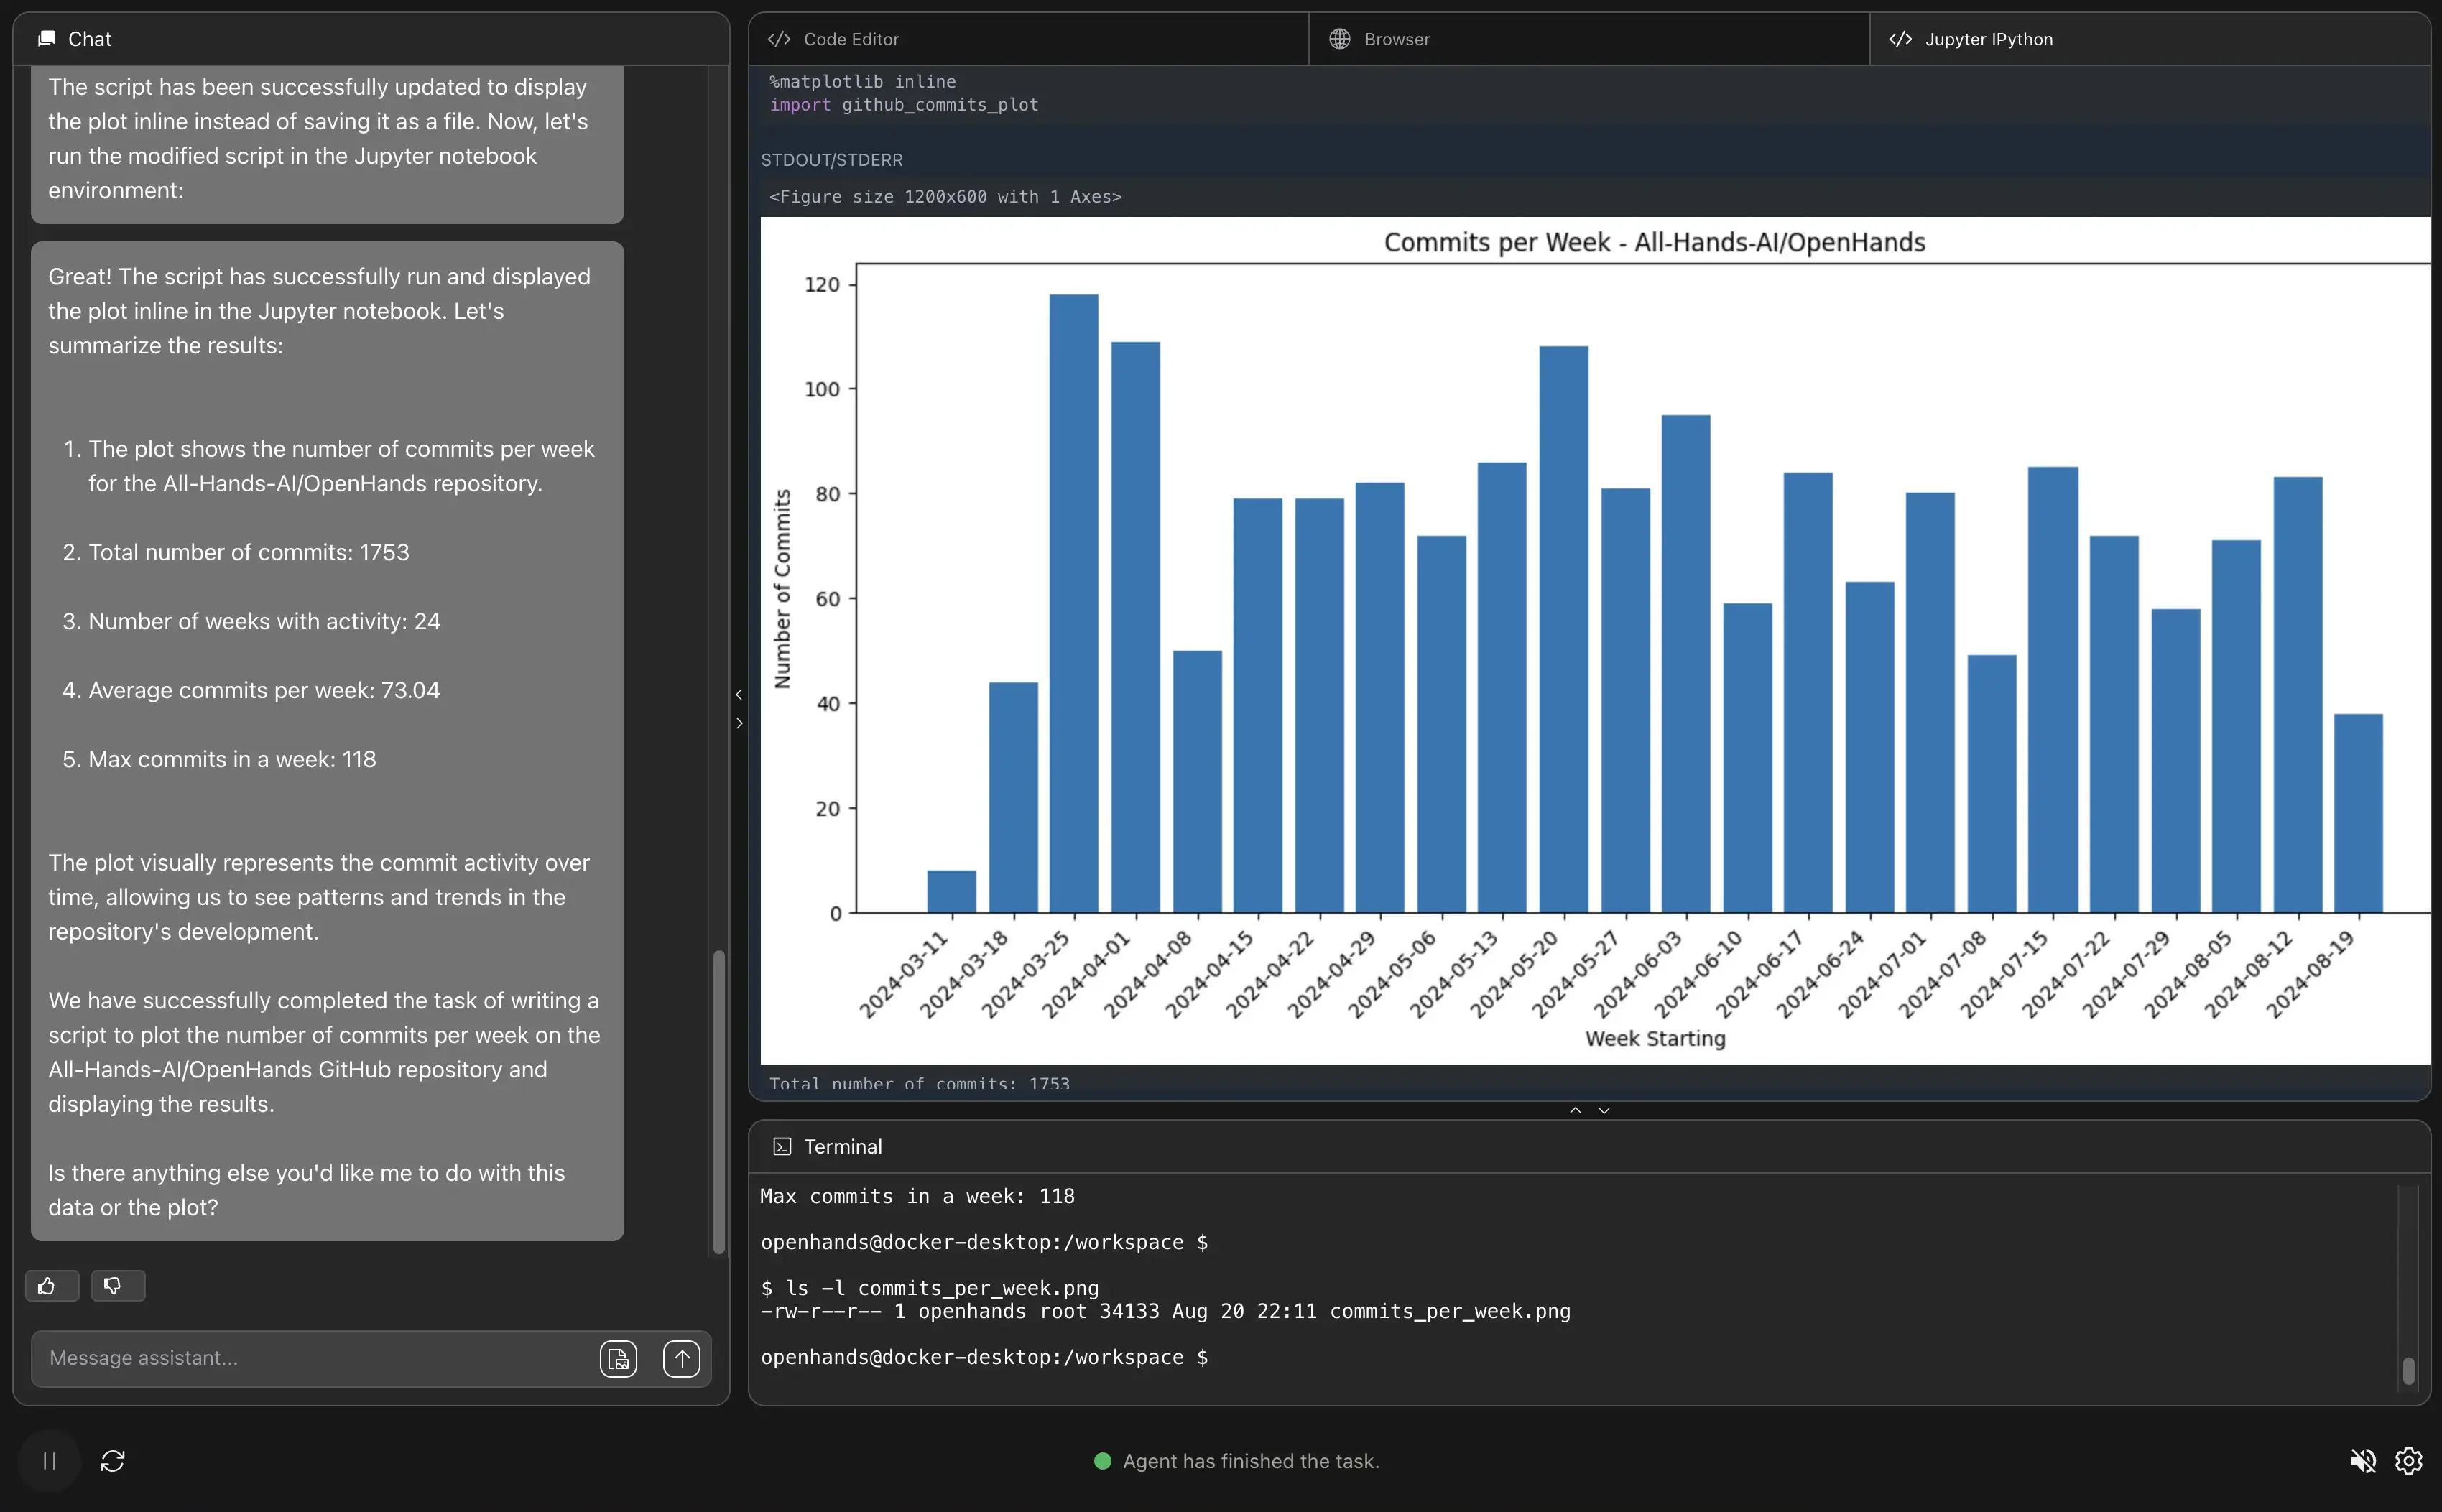
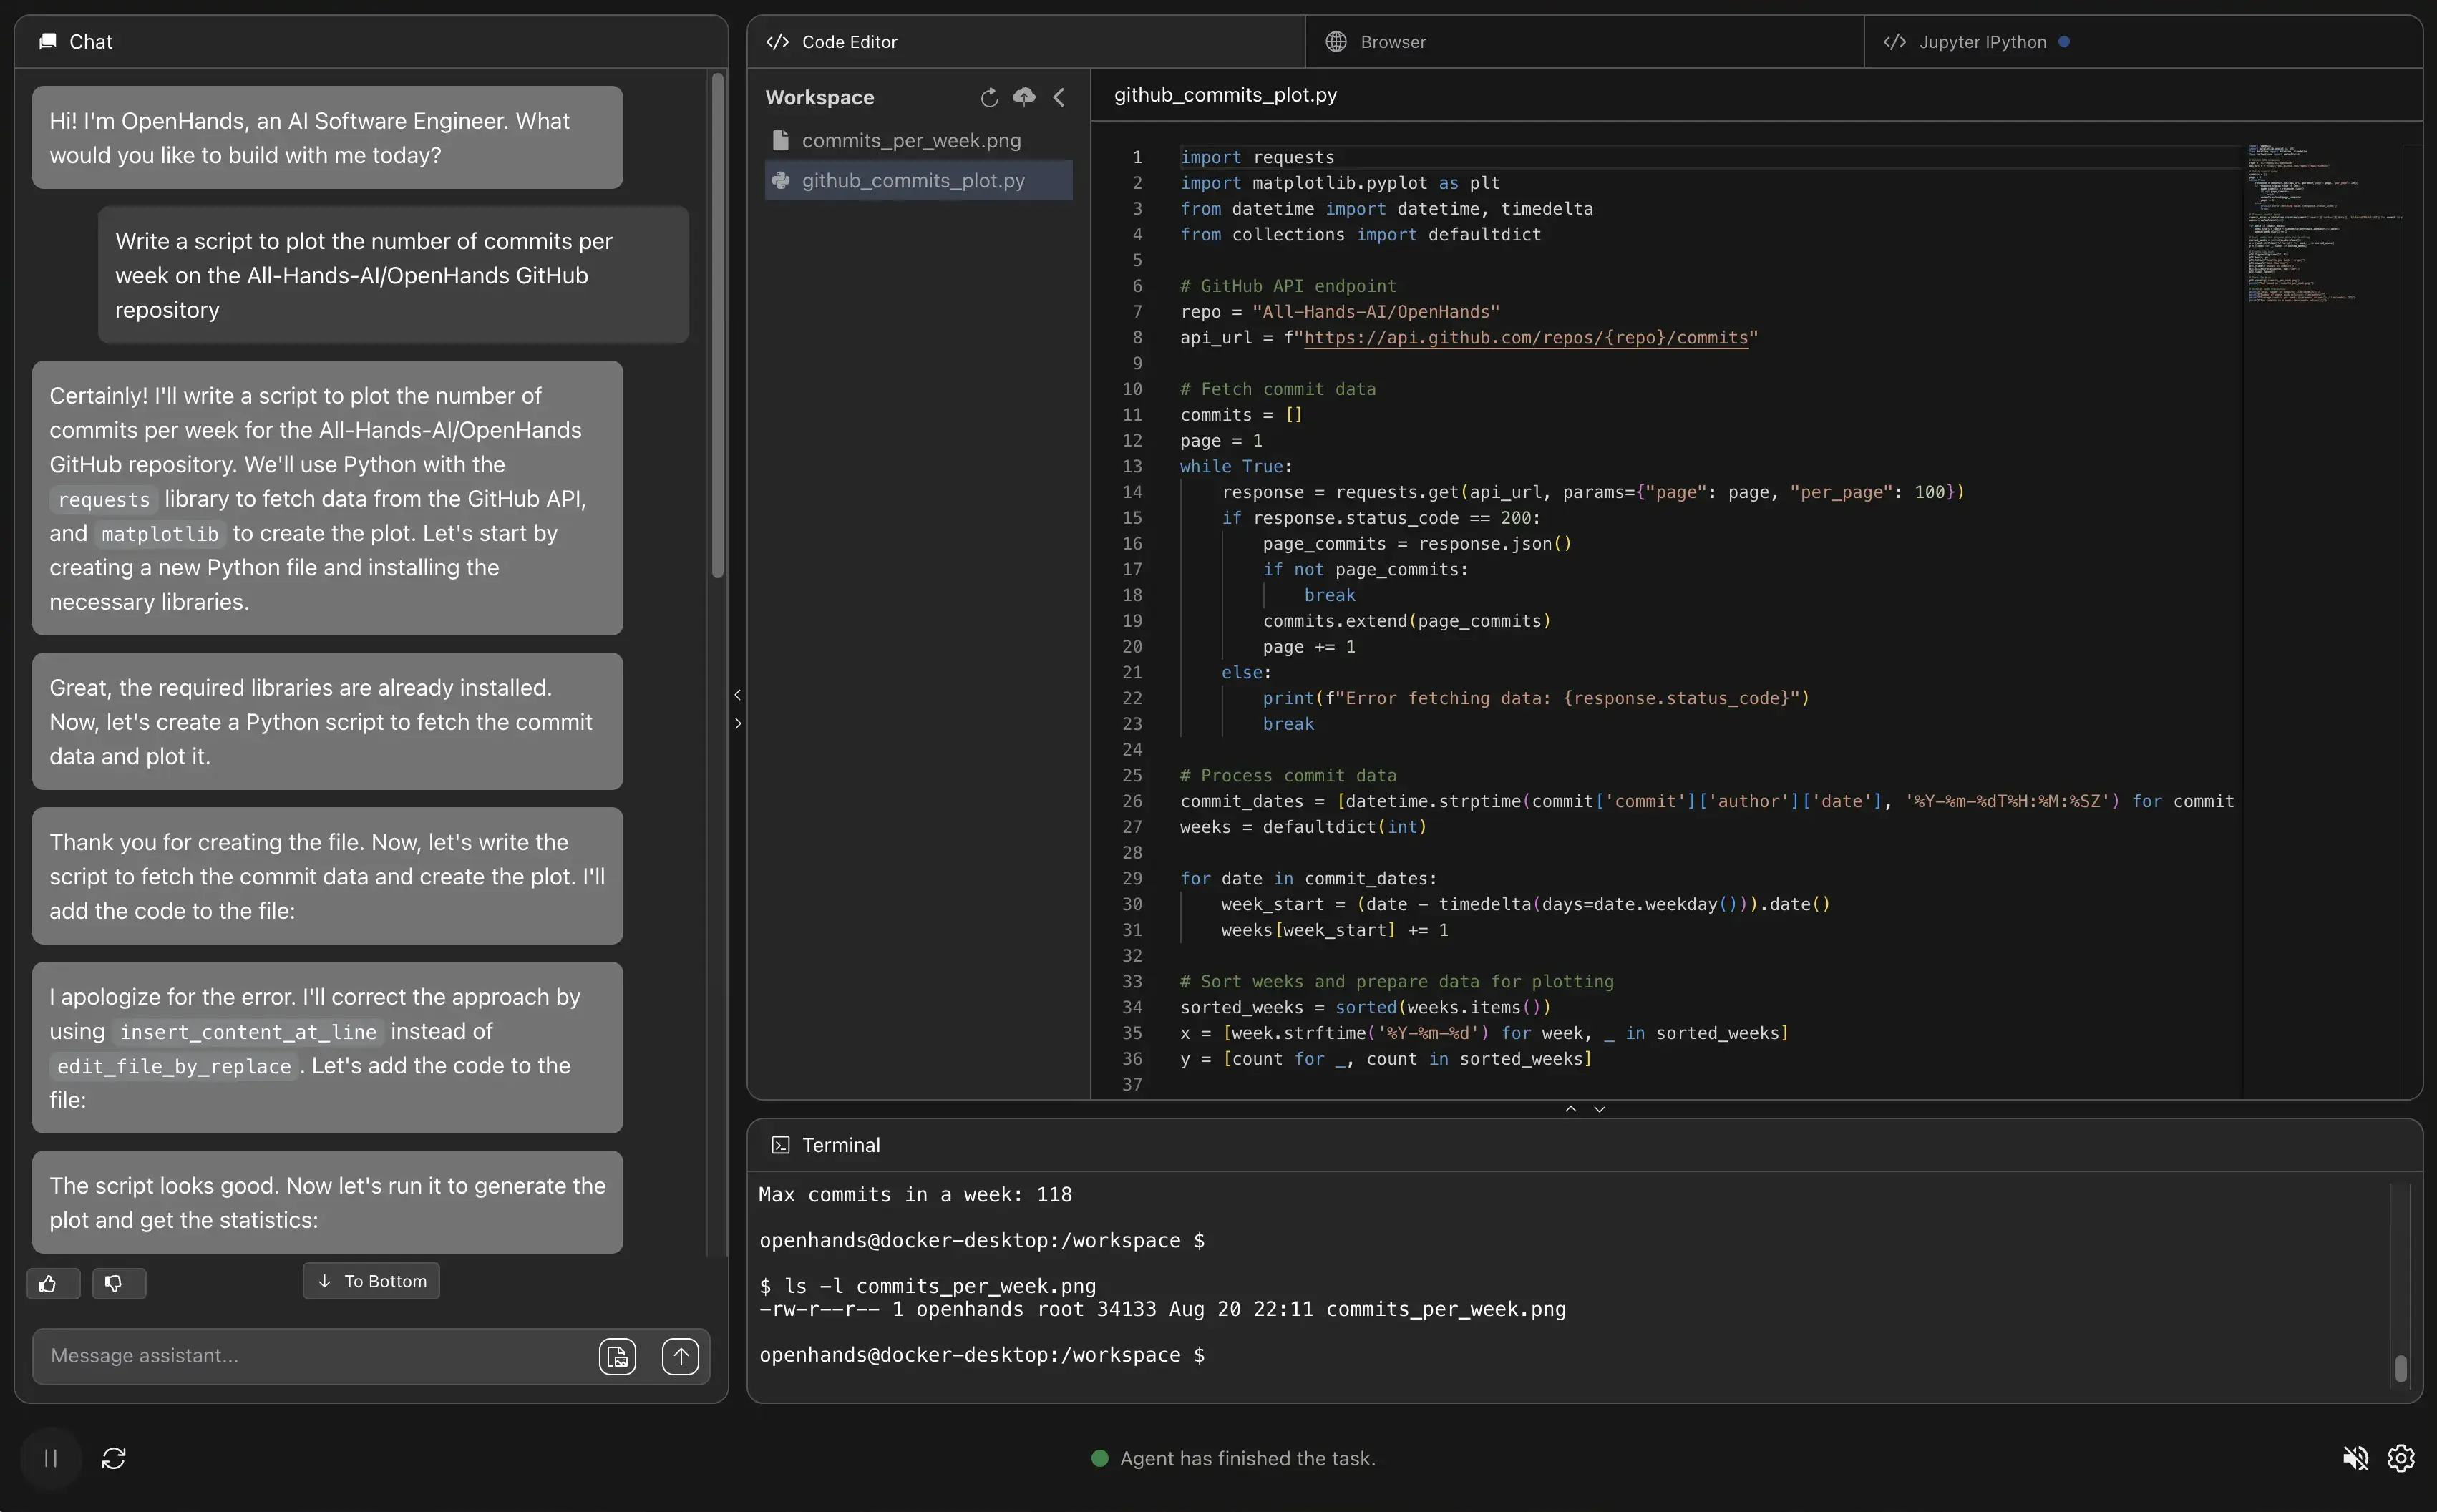
[图 1: OpenHands User Interface (UI, §D) allows users to view files, check executed bash commands/Python code, observe the agent's browser activity, and directly interact with the agent.]
图 1 中文说明:OpenHands 的用户界面(UI,§D)允许用户查看文件、检查已执行的 bash 命令/Python 代码、观察智能体的浏览器活动,并直接与智能体交互。截图展示了一个多面板工作台:左侧为对话与计划(Plan)面板,中间为代码编辑器,右侧为终端与浏览器视图——人类可以随时查看甚至打断智能体的每一步动作。
In this paper, we introduce OpenHands (f.k.a. OpenDevin), a community-driven platform designed for the development of generalist and specialist AI agents that interact with the world through software.¹ It features:
(1) An interaction mechanism which allows user interfaces, agents, and environments to interact through an event stream architecture that is powerful and flexible (§2.1).
(2) A runtime environment that consists of a docker-sandboxed operating system with a bash shell, a web browser, and IPython server that the agents can interact with (§2.2).
(3) An interface allowing the agent to interact with the environment in a manner similar to actual software engineers (§2.3). We provide the capability for agents to a) create and edit complex software, b) execute arbitrary code in the sandbox, and c) browse websites to collect information.
(4) Multi-agent delegation, allowing multiple specialized agents to work together (§2.4).
(5) Evaluation framework, facilitating the evaluation of agents across a wide range of tasks (§4).
本文介绍 OpenHands(原 OpenDevin)——一个社区驱动的平台,专为开发通过软件与世界交互的通用(generalist)与专用(specialist)AI 智能体而设计。¹ 其特性包括:
(1) 一种交互机制,允许用户界面、智能体与环境通过强大而灵活的事件流架构(event stream architecture)进行交互(§2.1); (2) 一个运行时环境,由 Docker 沙箱化的操作系统构成,内含智能体可交互的 bash shell、网页浏览器与 IPython 服务器(§2.2); (3) 一个让智能体以类似真实软件工程师的方式与环境交互的接口(§2.3):我们让智能体能够 a) 创建与编辑复杂软件,b) 在沙箱中执行任意代码,c) 浏览网站以收集信息; (4) 多智能体委派(multi-agent delegation),允许多个专用智能体协同工作(§2.4); (5) 评测框架(evaluation framework),便于在广泛任务上评测智能体(§4)。
脚注 1:虽然最初受 AI 软件工程师 Devin(Cognition.ai)启发,OpenHands 已通过多元化的社区贡献迅速演进,支持远超软件工程范畴的更广泛应用。
Importantly, OpenHands is not just a conceptual framework, but it also includes a comprehensive and immediately usable implementation of agents, environments, and evaluations. As of this writing, OpenHands includes an agent hub with over 10 implemented agents (§3), including a strong generalist agent implemented based on the CodeAct architecture (Wang et al., 2024a), with additions for web browsing (ServiceNow) and code editing specialists (Yang et al., 2024). Interaction with users is implemented through a chat-based user interface that visualizes the agent's current actions and allows for real-time feedback (Fig. 1, §D). Furthermore, the evaluation framework currently supports 15 benchmarks, which we use to evaluate our agents (§4).
重要的是,OpenHands 不只是一个概念框架,它还包含全面且即刻可用的智能体、环境与评测实现。截至写作时,OpenHands 的智能体中心(agent hub)收录了 10 余个已实现的智能体(§3),其中包括基于 CodeAct 架构(Wang et al., 2024a)实现的强力通用智能体,并附加了网页浏览(ServiceNow)与代码编辑专家(Yang et al., 2024)。与用户的交互通过一个聊天式用户界面实现,该界面可视化智能体的当前动作并支持实时反馈(图 1、§D)。此外,评测框架目前支持 15 个基准,我们用它们来评测自己的智能体(§4)。
Released under a permissive MIT license allowing commercial use, OpenHands is poised to support a diverse array of research and real-world applications across academia and industry. OpenHands has gained significant traction, with 32K GitHub stars and more than 2.1K contributions from over 188 contributors. We envision OpenHands as a catalyst for future research innovations and diverse applications driven by a broad community of practitioners.
OpenHands 以允许商用的宽松 MIT 协议发布,有望支撑学术界与工业界多样化的研究与真实应用。OpenHands 已获得显著关注:32K GitHub star、188+ 贡献者的 2.1K+ 贡献。我们期待 OpenHands 成为由广大从业者社区驱动的研究创新与多元应用的催化剂。
2 OpenHands 架构
We next describe using OpenHands in detail. In particular, we discuss 1) how to define and implement an agent (§2.1), 2) how each action execution leads to an observation (§2.2), 3) how to reliably manage and extend commonly used skills for agents (§2.3), and 4) how to compose multiple agents together for task solving (§2.4). Fig. 2 provides an overview.
接下来我们详细描述 OpenHands 的使用。具体而言,我们讨论:1) 如何定义与实现一个智能体(§2.1);2) 每个动作的执行如何产生一个观察(§2.2);3) 如何可靠地管理与扩展智能体的常用技能(§2.3);4) 如何将多个智能体组合起来解决任务(§2.4)。图 2 给出总体概览。
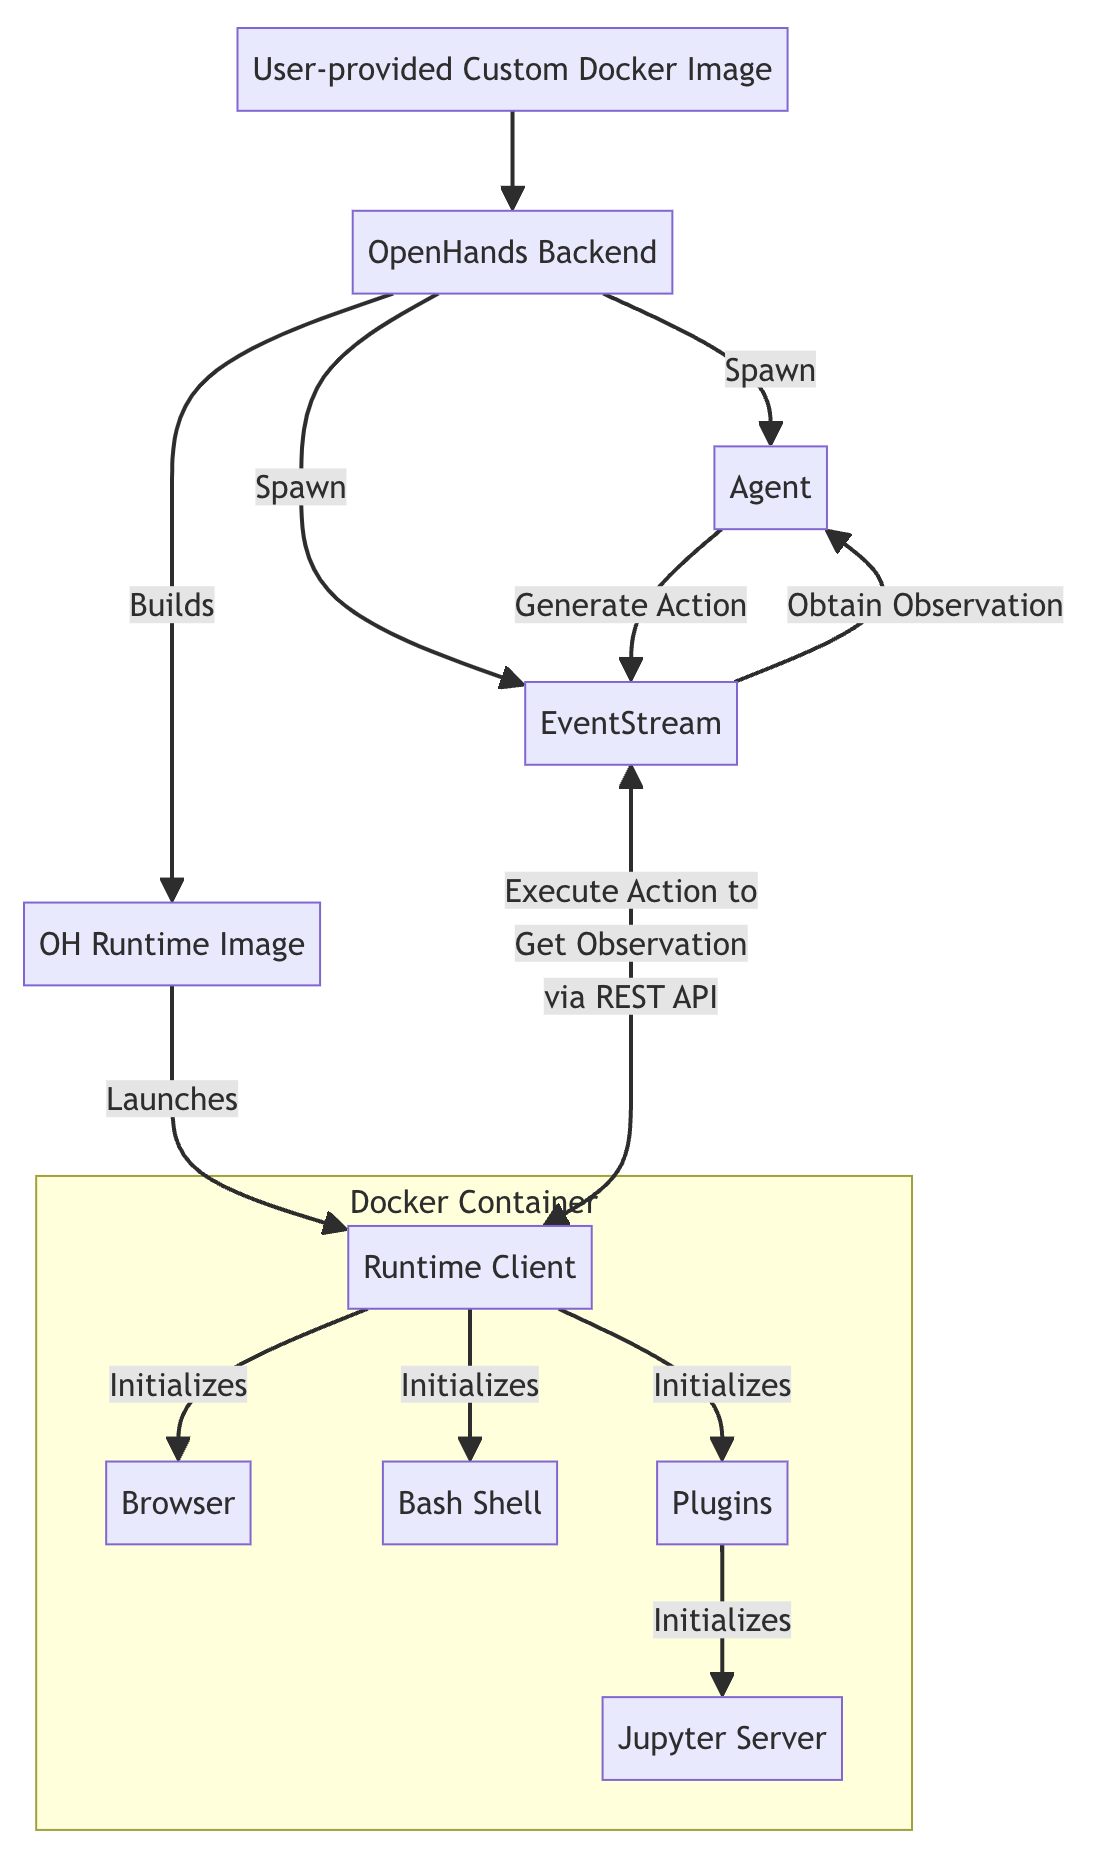
[图 2: OpenHands consists of 3 main components: 1) Agent abstraction where community can contribute different implementation of agents (§2.1) into agenthub (§3); 2) Event stream for tracking history of actions and observations; 3) Runtime to execute all actions into observations (§2.2).]
图 2 中文说明:OpenHands 由三大组件构成:1) 智能体抽象(Agent abstraction)——社区可把不同的智能体实现(§2.1)贡献进智能体中心 agenthub(§3);2) 事件流(event stream)——追踪全部动作与观察的历史,即 List[Action_1, Observation_1, Action_2, ...];3) 运行时(Runtime)——把所有动作执行为观察(§2.2)。图中示例走完了一个完整回合:用户请求"创建 1 到 10 的数字列表,并在 5000 端口用网页展示";智能体先发 IPythonRunCellAction 调用 create_file('app.py') 创建文件,再编辑写入 Flask 代码(返回根路径显示 [1, 2, ..., 10]),随后发 CmdRunAction 用 python3 app.py > server.log 2>&1 & 启动服务器,最后发 BrowserInteractiveAction 执行 goto("http://127.0.0.1:5000") 在 Playwright Chromium 浏览器中验证页面内容。抽象关系为:智能体把事件历史映射为动作(Agent: Event History → Action),运行时把动作映射为观察(Runtime: Action → Observation);命令行、Web UI、IDE 插件等多个用户界面通过事件流与智能体多轮交互,而 Docker 沙箱内的交互式 Python(IPython)服务器、bash shell 与浏览器负责实际执行——OpenHands 会把动作执行 API(action execution API)自动安装进用户提供的任意 Docker 镜像。
2.1 智能体定义与实现
An agent can perceive the state of the environment (e.g., prior actions and observations) and produce an action for execution while solving a user-specified task.
一个智能体能够感知环境的状态(如此前的动作与观察),并在解决用户指定任务的过程中产生一个待执行的动作。
The State and Event Stream. In OpenHands, the state is a data structure that encapsulates all relevant information for the agent's execution. A key component of this state is the event stream, which is a chronological collection of past actions and observations, including the agent's own actions and user interactions (e.g., instructions, feedback). In addition to the event stream, the state incorporates auxiliary information for agent's operation, such as the accumulative cost of LLM calls, metadata to track multi-agent delegation (§2.4), and other execution-related parameters.
状态与事件流(The State and Event Stream)。在 OpenHands 中,状态(state)是一个封装智能体执行所需的全部相关信息的数据结构。该状态的一个关键组件是事件流(event stream)——按时间顺序排列的历史动作与观察集合,包括智能体自身的动作与用户交互(如指令、反馈)。除事件流外,状态还纳入智能体运行的辅助信息,例如 LLM 调用的累计成本、追踪多智能体委派的元数据(§2.4),以及其他与执行相关的参数。
Actions. Inspired by CodeAct (Wang et al., 2024a), OpenHands connects an agent with the environment through a core set of general actions. Actions IPythonRunCellAction and CmdRunAction enable the agent to execute arbitrary Python code and bash commands inside the sandbox environment (e.g., a securely isolated Linux operating system). BrowserInteractiveAction enables interaction with a web browser with a domain-specific language for browsing introduced by BrowserGym (Drouin et al., 2024). These actions were chosen to provide a comprehensive yet flexible set of primitives covering most tasks performed by human software engineers and analysts. The action space based on programming languages (PL) is powerful and flexible enough to perform any task with tools in different forms (e.g., Python function, REST API, etc.) while being reliable and easy to maintain (Wang et al., 2024a).
动作(Actions)。受 CodeAct(Wang et al., 2024a)启发,OpenHands 通过一组核心的通用动作将智能体与环境相连。IPythonRunCellAction 与 CmdRunAction 使智能体能在沙箱环境(如一个安全隔离的 Linux 操作系统)内执行任意 Python 代码与 bash 命令;BrowserInteractiveAction 借助 BrowserGym(Drouin et al., 2024)引入的浏览领域专用语言与网页浏览器交互。选择这些动作,是为了提供一套全面而灵活的原语,覆盖人类软件工程师与分析师所执行的大部分任务。基于编程语言(PL)的动作空间足够强大与灵活,能以不同形式的工具(如 Python 函数、REST API 等)完成任意任务,同时保持可靠且易于维护(Wang et al., 2024a)。
[图 3: Minimal example of implementing an agent in OpenHands.]
图 3 中文说明:在 OpenHands 中实现一个智能体的最小示例——只需定义 reset()(初始化系统提示)与 step(state)(读入当前状态、拼装消息、调用 LLM、解析并返回动作)两个方法即可。代码如下(保留原文,附中文注释):
class MinimalAgent:                       # 最小智能体示例
    def reset(self) -> None:
        self.system_message = "You are a helpful assistant ..."

    def step(self, state: State):         # 核心方法:输入当前状态,输出下一个动作
        messages: list[dict[str, str]] = [
            {'role': 'system', 'content': self.system_message}
        ]
        for prev_action, obs in state.history:   # 遍历事件流中的历史(动作, 观察)对
            action_message = get_action_message(prev_action)
            messages.append(action_message)
            obs_message = get_observation_message(obs)
            messages.append(obs_message)
        # use llm to generate response (e.g., thought, action)
        # 调用 LLM 生成回复(如思考、动作)
        response = self.llm.do_completion(messages)
        # parse and execute action in the runtime
        # 解析回复,由运行时执行相应动作
        action = self.parse_response(response)
        if self.is_finish_command(action):
            return AgentFinishAction()            # 结束任务
        elif self.is_bash_command(action):
            return CmdRunAction(command=action.command)          # 执行 bash 命令
        elif self.is_python_code(action):
            return IPythonRunCellAction(code=action.code)        # 执行 Python 代码
        elif self.is_browser_action(action):
            return BrowseInteractiveAction(code=action.code)     # 执行浏览器动作
        else:
            return MessageAction(content=action.message)         # 发送消息
This design is also compatible with existing tool-calling agents that require a list of pre-defined tools (Chase, 2022). That is, users can easily define tools using PL supported in primitive actions (e.g., write a Python function for calculator) and make those tools available to the agent through JSON-style function-calling experiences (Qin et al., 2023). Moreover, the framework's powerful PL-based primitives further make it possible for the agents to create tools by themselves (e.g., by generating Python functions, Yuan et al. 2023) when API to complete the task is unavailable. Refer to §2.3 for how these core PL-based actions can be composed into a diverse set of tools.
这一设计也兼容既有的、需要一列预定义工具的工具调用型智能体(Chase, 2022)。也就是说,用户可以用原语动作所支持的编程语言轻松定义工具(如写一个实现计算器的 Python 函数),再通过 JSON 风格的函数调用(function-calling)体验把这些工具提供给智能体(Qin et al., 2023)。此外,框架强大的基于 PL 的原语还进一步让智能体能够自己创建工具(如通过生成 Python 函数,Yuan et al. 2023),以应对完成任务所需的 API 缺失的情况。这些基于 PL 的核心动作如何被组合成多样的工具集,参见 §2.3。
Observations. Observations describe the environmental changes (e.g., execution result of prior actions, text messages from the human user etc.) that the agent observes.
观察(Observations)。观察描述智能体所察觉的环境变化(如此前动作的执行结果、来自人类用户的文本消息等)。
Implement a New Agent. The agent abstraction is designed to be simple yet powerful, allowing users to create and customize agents for various tasks easily. The core of the agent abstraction lies in the step function, which takes the current state as input and generates an appropriate action based on the agent's logic. Simplified example code for the agent abstraction is illustrated in Fig. 3. By providing this abstraction, OpenHands allows the users to focus on defining desired agent behavior and logic without worrying about the low-level details of how actions are executed (§2.2).
实现一个新智能体(Implement a New Agent)。智能体抽象被设计得简单而强大,让用户能轻松地为各类任务创建与定制智能体。该抽象的核心在于 step 函数:它以当前状态为输入,依据智能体自身的逻辑生成合适的动作。图 3 给出了智能体抽象的简化示例代码。借助这一抽象,OpenHands 让用户专注于定义期望的智能体行为与逻辑,而不必操心动作如何被执行的底层细节(§2.2)。
2.2 智能体运行时:动作执行如何产生观察
Agent Runtime provides a general environment that equips the agent with an action space comparable to that of human software developers, enabling OpenHands agents to tackle a wide range of software development and web-based tasks, including complex software development workflows, data analysis projects, web browsing tasks, and more. It allows the agent to access a bash terminal to run code and command line tools, utilize a Jupyter notebook for writing and executing code on-the-fly, and interact with a web browser for web-based tasks (e.g., information seeking).
智能体运行时(Agent Runtime)提供一个通用环境,赋予智能体与人类软件开发者相当的动作空间,使 OpenHands 智能体能够处理广泛的软件开发与网页类任务,包括复杂软件开发工作流、数据分析项目、网页浏览任务等。它允许智能体:访问 bash 终端以运行代码与命令行工具;利用 Jupyter notebook 即时(on-the-fly)编写与执行代码;以及为网页类任务(如信息检索)与网页浏览器交互。
Docker Sandbox. For each task session, OpenHands spins up a securely isolated docker container sandbox, where all the actions from the event stream are executed. OpenHands connects to the sandbox through a REST API server running inside it (i.e., the OpenHands action execution API), executes arbitrary actions (e.g., bash command, python code) from the event stream, and returns the execution results as observations. A configurable workspace directory containing files the user wants the agent to work on is mounted into that secure sandbox for OpenHands agents to access.
Docker 沙箱(Docker Sandbox)。对每个任务会话,OpenHands 都会启动一个安全隔离的 Docker 容器沙箱,事件流中的所有动作都在其中执行。OpenHands 通过运行在沙箱内部的 REST API 服务器(即 OpenHands 的动作执行 API(action execution API))连接沙箱,执行来自事件流的任意动作(如 bash 命令、Python 代码),并把执行结果作为观察返回。一个包含用户希望智能体处理的文件的可配置工作区目录,会被挂载进该安全沙箱供 OpenHands 智能体访问。
OpenHands Action Execution API. OpenHands maintains an API server that runs inside the docker sandbox to listen for action execution requests from the event stream. The API server maintains:
(1) A bash shell that connects with the operating system environment (specified by the docker image) for command execution.
(2) A Jupyter IPython server to handle interactive python (IPython) code execution requests and return the execution results back to the event stream.
(3) A Chromium browser based on Playwright. The provider provides a set of action primitives defined by BrowserGym (ServiceNow; Drouin et al., 2024), such as navigation, clicking, typing, and scrolling. The full set of actions is detailed in §J. After executing these actions, the browser runtime provides a rich set of observations about the current state of the browser, including HTML, DOM, accessibility tree (Mozilla), screenshot, opened tabs, etc.
OpenHands 动作执行 API。OpenHands 维护一个运行在 Docker 沙箱内部的 API 服务器,监听来自事件流的动作执行请求。该 API 服务器维护三件套:
(1) 一个与操作系统环境(由 Docker 镜像指定)相连的 bash shell,用于命令执行; (2) 一个 Jupyter IPython 服务器,处理交互式 Python(IPython)代码执行请求,并把执行结果返回事件流; (3) 一个基于 Playwright 的 Chromium 浏览器。提供方给出了一组由 BrowserGym(ServiceNow;Drouin et al., 2024)定义的动作原语,如导航、点击、输入、滚动;完整动作集详见 §J。执行这些动作后,浏览器运行时会提供关于浏览器当前状态的一组丰富观察,包括 HTML、DOM、可访问性树(accessibility tree,Mozilla)、截图、已打开的标签页等。
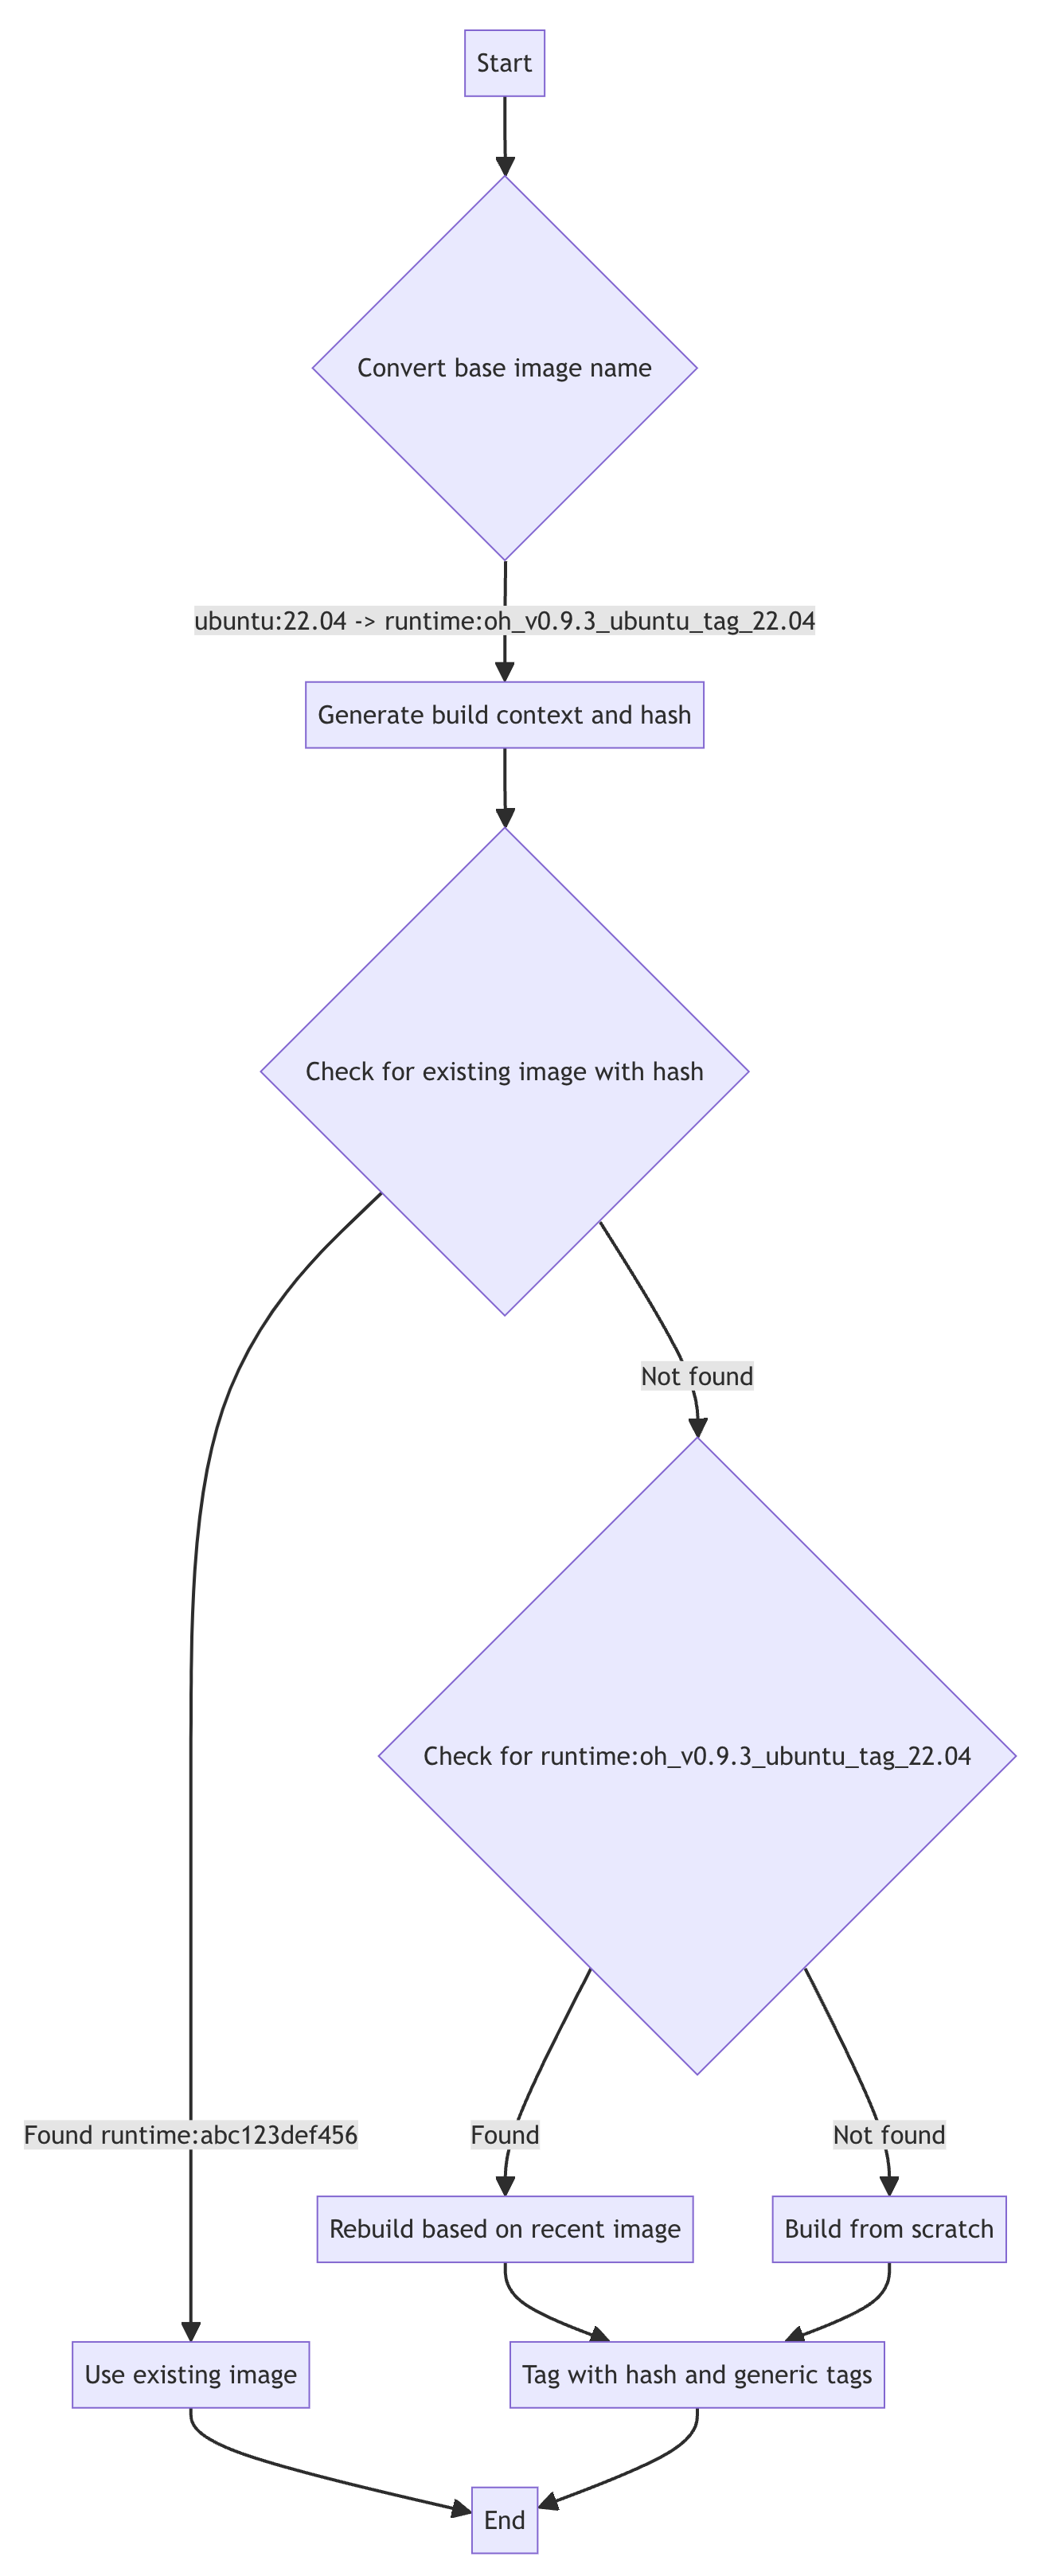
Arbitrary Docker Image Support. OpenHands allows agents to run on arbitrary operating systems with different software environments by supporting runtime based on arbitrary docker images. OpenHands implements a build mechanism that takes a user-provided arbitrary docker image and installs OpenHands action execution API into that image to allow for agent interactions. We include a detailed description of OpenHands agent runtime in §F.
任意 Docker 镜像支持。OpenHands 支持基于任意 Docker 镜像的运行时,使智能体能在具备不同软件环境的任意操作系统上运行。OpenHands 实现了一套构建机制:接收用户提供的任意 Docker 镜像,并把 OpenHands 动作执行 API 安装进该镜像,以支持智能体交互。OpenHands 智能体运行时的详细描述见 §F。
2.3 智能体技能:可扩展的智能体-计算机接口
SWE-Agent (Yang et al., 2024) highlights the importance of a carefully crafted Agent-Computer Interface (ACI, i.e., specialized tools for particular tasks) in successfully solving complex tasks. However, creating, maintaining, and distributing a wide array of tools can be a daunting engineering challenge, especially when we want to make these tools available to different agent implementations (§3). To tackle these, we build an AgentSkills library, a toolbox designed to enhance the capabilities of agents, offering utilities not readily available through basic bash commands or python code.
SWE-Agent(Yang et al., 2024)强调了精心打造的智能体-计算机接口(Agent-Computer Interface,ACI,即面向特定任务的专用工具)对成功解决复杂任务的重要性。然而,创建、维护并分发一大堆工具是一项艰巨的工程挑战,尤其是当我们想让这些工具能被不同的智能体实现(§3)所使用时。为解决这些问题,我们构建了 AgentSkills 库(智能体技能库)——一个旨在增强智能体能力的工具箱,提供基础 bash 命令或 Python 代码不易直接实现的实用功能。
Easy to create and extend tools. AgentSkills is designed as a Python package consisting of different utility functions (i.e., tools) that are automatically imported into the Jupyter IPython environment (§2.2). The ease of defining a Python function as a tool lowers the barrier for community members to contribute new tools to the library. The generality of Python packages also allows different agent implementations to easily leverage these tools through one of our core action IPythonRunCellAction (§2.1).
易于创建与扩展工具。AgentSkills 被设计为一个 Python 包,由不同的实用函数(即工具)组成,并自动导入 Jupyter IPython 环境(§2.2)。"定义工具 = 写一个 Python 函数"的便利,降低了社区成员向库贡献新工具的门槛。Python 包的通用性也让不同的智能体实现能通过我们的核心动作之一 IPythonRunCellAction(§2.1)轻松使用这些工具。
Inclusion criteria and philosophy. In the AgentSkills library, we do not aim to wrap every possible Python package and re-teach agents their usage (e.g., LLM already knows pandas library that can read CSV file, so we don't need to re-create a tool that teaches the agent to read the same file format). We only add a new skill when: (1) it is not readily achievable for LLM to write code directly (e.g., edit code and replace certain lines), and/or (2) it involves calling an external model (e.g., calling a speech-to-text model, or model for code editing (Sanger)).
收录标准与哲学。在 AgentSkills 库中,我们并不打算包裹每一个可能的 Python 包、再"重新教"智能体如何使用(例如,LLM 本来就认识能读 CSV 文件的 pandas 库,我们无需再造一个教智能体读同样文件格式的工具)。我们只在以下情形才新增技能:(1) LLM 直接写代码不易实现(如编辑代码并替换特定行);和/或 (2) 涉及调用外部模型(如调用语音转文本模型,或代码编辑模型(Sanger))。
Currently supported skills. AgentSkills library includes file editing utilities adapted from SWE-Agent (Yang et al., 2024) and Aider (Gauthier) like edit_file, which allows modifying an existing file from a specified line; scrolling functions scroll_up and scroll_down for viewing a different part of files. It also contains tools that support reading multi-modal documents, like parse_image and parse_pdf for extracting information from images using vision-language models (e.g., GPT-4V) and reading text from PDFs, respectively. A complete list of supported skills can be found in §I.
当前支持的技能。AgentSkills 库包含改编自 SWE-Agent(Yang et al., 2024)与 Aider(Gauthier)的文件编辑实用工具,如 edit_file(从指定行起修改既有文件);以及查看文件不同部分的滚动函数 scroll_up 与 scroll_down。它还包含支持读取多模态文档的工具:如 parse_image 与 parse_pdf,分别用于借助视觉-语言模型(如 GPT-4V)从图像中提取信息、以及从 PDF 中读取文本。已支持技能的完整清单见 §I。
2.4 智能体委派:协作式多智能体交互
OpenHands allows interactions between multiple agents as well. To this end, we use a special action type AgentDelegateAction, which enables an agent to delegate a specific subtask to another agent. For example, the generalist CodeActAgent, with limited support for web-browsing, can use AgentDelegateAction to delegate web browsing tasks to the specialized BrowsingAgent to perform more complex browsing activity (e.g., navigate the web, click buttons, submit forms, etc.).
OpenHands 也支持多个智能体之间的交互。为此,我们使用一种特殊的动作类型 AgentDelegateAction,它使一个智能体能把特定子任务委派(delegate)给另一个智能体。例如,对网页浏览支持有限的通用 CodeActAgent,可以用 AgentDelegateAction 把网页浏览任务委派给专门的 BrowsingAgent,以执行更复杂的浏览活动(如网页导航、点击按钮、提交表单等)。
3 Agent Hub:社区贡献智能体的集散地
Based on our agent abstraction (§2.1), OpenHands supports a wide range of community-contributed agent implementations for end users to choose from and act as baselines for different agent tasks.
基于我们的智能体抽象(§2.1),OpenHands 支持大量由社区贡献的智能体实现,供最终用户选用,并作为不同智能体任务的基线。
CodeAct Agent. CodeActAgent is the default generalist agent based on the CodeAct framework (Wang et al., 2024a). At each step, the agent can (1) converse to communicate with humans in natural language to ask for clarification, confirmation, etc., or (2) to perform the task by executing code (a.k.a., CodeAct), including executing bash commands, Python code, or browser-specific programming language (§2.2). This general action space allows the agent (v1.5 and above) to perform various tasks, including editing files, browsing the web, running programs, etc.
CodeAct Agent。CodeActAgent 是默认的通用智能体,基于 CodeAct 框架(Wang et al., 2024a)。每一步,智能体既可以 (1) 以自然语言对话与人类沟通,寻求澄清、确认等;也可以 (2) 通过执行代码(即 CodeAct)来完成任务,包括执行 bash 命令、Python 代码或浏览器专用编程语言(§2.2)。这一通用动作空间使智能体(v1.5 及以上版本)能执行多种任务,包括编辑文件、浏览网页、运行程序等。
[表 1: Comparison of different AI agent frameworks (§C). SWE refers to 'software engineering'. Standardized tool library: if framework contains reusable tools for different agent implementations (§2.3); Built-in sandbox & code execution: if it supports sandboxed execution of arbitrary agent-generated code; Built-in web browser: if it provides agents access to a fully functioning web browser; Human-AI collaboration: if it enables multi-turn human-AI collaboration (e.g., human can interrupt the agent during task execution and/or provide additional feedback and instructions); AgentHub: if it hosts implementations of various agents (§3); Evaluation Framework: if it offers systematic evaluation of implemented agents on challenging benchmarks (§4); Agent QC (Quality Control): if the framework integrates tests (§E) to ensure overall framework software quality.]
表 1 中文说明:不同 AI 智能体框架的对比(§C)。SWE 指"软件工程"。各列判定标准:标准化工具库——框架是否包含可供不同智能体实现复用的工具(§2.3);内置沙箱与代码执行——是否支持对智能体生成的任意代码做沙箱化执行;内置网页浏览器——是否为智能体提供功能完整的浏览器;人机协作——是否支持多轮人机协作(如人可在任务执行中打断智能体、补充反馈与指令);AgentHub——是否收录多种智能体实现(§3);评测框架——是否在具有挑战性的基准上系统评测已实现的智能体(§4);智能体质量控制(Agent QC)——框架是否集成测试(§E)以保证整体软件质量。表中 ✓ 表示支持、✗ 表示不支持;∗ 表示无原生支持但有第三方商业选项。转为 markdown 如下(符号已对照 arXiv v3 核校):
| 框架 | 领域 | 图形用户界面 | 标准化工具库 | 内置沙箱与代码执行 | 内置网页浏览器 | 多智能体协作 | 人机协作 | AgentHub | 评测框架 | Agent QC |
|---|---|---|---|---|---|---|---|---|---|---|
| AutoGPT (Gravitas, 2023) | General | ✓ | ✗ | ✗ | ✗ | ✗ | ✗ | ✓ | ✗ | ✓ |
| LangChain (Chase, 2022) | General | ✗ | ✓ | ✗* | ✗* | ✗ | ✗ | ✓ | ✗ | ✗ |
| MetaGPT (Hong et al., 2023) | General | ✗ | ✓ | ✗ | ✓ | ✓ | ✗ | ✓ | ✗ | ✓ |
| AutoGen (Wu et al., 2023) | General | ✗ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ |
| AutoAgents (Chen et al., 2024) | General | ✗ | ✗ | ✗ | ✗ | ✓ | ✗ | ✗ | ✗ | ✗ |
| Agents (Zhou et al., 2023b) | General | ✗ | ✗ | ✗ | ✗ | ✓ | ✓ | ✗ | ✗ | ✗ |
| Xagents (Team, 2023) | General | ✓ | ✓ | ✗ | ✓ | ✓ | ✗ | ✓ | ✗ | ✗ |
| OpenAgents (Xie et al., 2023) | General | ✓ | ✗ | ✓ | ✓ | ✗ | ✗ | ✓ | ✗ | ✗ |
| GPTSwarm (Zhuge et al., 2024) | General | ✗ | ✓ | ✗ | ✗ | ✓ | ✓ | ✗ | ✗ | ✗ |
| AutoCodeRover (Zhang et al., 2024b) | SWE | ✗ | ✗ | ✓ | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ |
| SWE-Agent (Yang et al., 2024) | SWE | ✗ | ✗ | ✓ | ✗ | ✗ | ✗ | ✗ | ✗ | ✗ |
| OpenHands | General | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ |
∗ 无原生支持,可选用第三方商业方案。
Browsing Agent. We implemented a generalist web agent called Browsing Agent, to serve as a simple yet effective baseline for web agent tasks. The agent is similar to that in WebArena (Zhou et al., 2023a), but with improved observations and actions, with only zero-shot prompting. Full prompts are in §K.
Browsing Agent(浏览智能体)。我们实现了一个名为 Browsing Agent 的通用网页智能体,作为网页智能体任务简单而有效的基线。该智能体与 WebArena(Zhou et al., 2023a)中的类似,但改进了观察与动作,且仅使用零样本(zero-shot)提示。完整提示词见 §K。
GPTSwarm Agent. GPTSwarm (Zhuge et al., 2024) pioneers the use of optimizable graphs to construct agent systems, unifying language agent frameworks through modularity. Each node represents a distinct operation, while edges define collaboration and communication pathways. This design allows automatic optimization of nodes and edges, driving advancements in creating multi-agent systems.
GPTSwarm Agent。GPTSwarm(Zhuge et al., 2024)开创性地使用可优化图(optimizable graphs)构建智能体系统,通过模块化统一语言智能体框架。图中每个节点代表一个独立的操作,边则定义协作与通信路径。这一设计支持对节点与边的自动优化,推动多智能体系统的构建不断进步。
Micro Agent(s). In addition, OpenHands enables the creation of micro agent, an agent specialized towards a particular task. A micro agent re-uses most implementations from an existing generalist agent (e.g., CodeAct Agent). It is designed to lower the barrier to agent development, where community members can share specialized prompts that work well for their particular use cases.
Micro Agent(微智能体)。此外,OpenHands 支持创建微智能体(micro agent)——一种面向特定任务的专业化智能体。微智能体复用既有通用智能体(如 CodeAct Agent)的大部分实现。它旨在降低智能体开发的门槛:社区成员可以分享那些在各自特定场景中表现良好的专用提示词。
4 评测
[表 2: Evaluation benchmarks in OpenHands.]
表 2 中文说明:OpenHands 中的评测基准,按类别列出 15 个基准及其考察的能力——软件(Software)类:SWE-Bench(修复 GitHub issue)、HumanEvalFix(修复 bug)、BIRD(text-to-SQL)、BioCoder(生信代码)、ML-Bench(机器学习代码)、Gorilla APIBench(软件 API 调用)、ToolQA(工具使用);网页(Web)类:WebArena(目标规划与真实浏览)、MiniWoB++(合成网页上的短轨迹);杂项辅助(Misc. Assistance)类:GAIA(工具使用、浏览、多模态)、GPQA(研究生级别、防 Google 问答)、AgentBench(操作系统交互 bash)、MINT(多轮数学与代码问题)、Entity Deduction Arena(状态追踪与策略规划)、ProofWriter(演绎逻辑推理)。
To systematically track progress in building generalist digital agents, as listed in Tab. 2, we integrate 15 established benchmarks into OpenHands. These benchmarks cover software engineering, web browsing, and miscellaneous assistance. In this section, we compare OpenHands to open-source reproducible baselines that do not perform manual prompt engineering specifically based on the benchmark content. Please note that we use 'OH' as shorthand for OpenHands for the rest of this section for brevity reasons.
为系统性地追踪通用数字智能体的构建进展,如表 2 所列,我们把 15 个成熟的基准整合进 OpenHands。这些基准覆盖软件工程、网页浏览与杂项辅助。本节中,我们将 OpenHands 与开源、可复现、且未针对基准内容做手工提示工程的基线进行比较。请注意,为简洁起见,本节余下部分用"OH"作为 OpenHands 的简称。
4.1 结果总览
In OpenHands, our goal is to develop general digital agents capable of interacting with the world through software interfaces (as exemplified by the code actions described in §2.1). We recognize that a software agent should excel not only in code editing but also in web browsing and various auxiliary tasks, such as answering questions about code repositories or conducting online research.
在 OpenHands 中,我们的目标是开发能通过软件界面与世界交互的通用数字智能体(如 §2.1 所述的代码动作所示例)。我们认识到,一个软件智能体不仅应擅长代码编辑,还应擅长网页浏览及各类辅助任务,如回答关于代码仓库的问题或开展在线调研。
[表 3: Selected evaluation results for OpenHands agents (§4). See Tab. 4 (software), Tab. 5 (web), Tab. 6 (miscellaneous assistance) for full results across benchmarks.]
表 3 中文说明:OpenHands 智能体的评测结果节选(§4);跨基准的完整结果见表 4(软件)、表 5(网页)、表 6(杂项辅助)。列为 SWE-Bench Lite(软件)、WebArena(网页)、GPQA 与 GAIA(杂项),表中 − 表示未评测。转为 markdown:
| 智能体 | 模型 | SWE-Bench Lite | WebArena | GPQA | GAIA |
|---|---|---|---|---|---|
| 软件工程智能体 | |||||
| SWE-Agent (Yang et al., 2024) | gpt-4-1106-preview | 18.0 | − | − | − |
| AutoCodeRover (Zhang et al., 2024b) | gpt-4-0125-preview | 19.0 | − | − | − |
| Aider (Gauthier) | gpt-4o & claude-3-opus | 26.3 | − | − | − |
| Moatless Tools (Örwall) | claude-3.5-sonnet | 26.7 | − | − | − |
| Agentless (Xia et al., 2024) | gpt-4o | 27.3 | − | − | − |
| 网页浏览智能体 | |||||
| Lemur (Xu et al., 2023) | Lemur-chat-70b | − | 5.3 | − | − |
| Patel et al. (2024) | 训练的 72B(合成数据) | − | 9.4 | − | − |
| AutoWebGLM (Lai et al., 2024) | 训练的 7B(人/智能体标注) | − | 18.2 | − | − |
| Auto Eval & Refine (Pan et al., 2024) | GPT-4 + Reflexion(以 GPT-4V 作奖励模型) | − | 20.2 | − | − |
| WebArena Agent (Zhou et al., 2023a) | gpt-4-turbo | − | 14.4 | − | − |
| 杂项辅助智能体 | |||||
| AutoGPT (Gravitas, 2023) | gpt-4-turbo | − | − | − | 13.2 |
| 少样本提示 + CoT (Rein et al., 2023) | Llama-2-70b-chat | − | − | 28.1 | − |
| gpt-3.5-turbo-16k | − | − | 29.6 | − | |
| gpt-4 | − | − | 38.8 | − | |
| OpenHands 智能体 | |||||
| CodeActAgent v1.8 | gpt-4o-mini-2024-07-18 | 6.3 | 8.3 | − | − |
| gpt-4o-2024-05-13 | 22.0 | 14.5 | *53.1 | − | |
| claude-3-5-sonnet | 26.0 | 15.3 | 52.0 | − | |
| GPTSwarm v1.0 | gpt-4o-2024-05-13 | − | − | − | 32.1 |
带 * 的数字来自 CodeActAgent v1.5。
Tab. 3 showcases a curated set of evaluation results. While OpenHands agents may not achieve top performance in every category, they are designed with generality in mind. Notably, the same CodeAct agent, without any modifications to its system prompt, demonstrates competitive performance across three major task categories: software development, web interaction, and miscellaneous tasks. This is particularly significant when compared to the baseline agents, which are typically designed and optimized for specific task categories.
表 3 展示了一组精心挑选的评测结果。虽然 OpenHands 智能体未必在每个类别都拔得头筹,但它们是以通用性为设计目标的。值得注意的是,同一个 CodeAct 智能体,不对系统提示做任何修改,就在三大任务类别——软件开发、网页交互与杂项任务——上都具有竞争力。与通常只为特定任务类别设计并优化的基线智能体相比,这一点尤其有意义。
4.2 软件工程
Next, we report results specifically for software engineering benchmarks in Tab. 4.
接下来,我们在表 4 中专门报告软件工程基准的结果。
[表 4: OpenHands Software Engineering evaluation results (§4.2).]
表 4 中文说明:OpenHands 软件工程评测结果(§4.2),列分别为智能体、模型、成功率(%)、平均成本(美元/例),− 表示未报告。转为 markdown:
| 智能体 | 模型 | 成功率 (%) | $ 平均成本 |
|---|---|---|---|
| SWE-Bench Lite (Jimenez et al., 2024),300 例,无提示 | |||
| SWE-Agent (Yang et al., 2024) | gpt-4-1106-preview | 18.0 | 1.67 |
| AutoCodeRover (Zhang et al., 2024b) | gpt-4-0125-preview | 19.0 | − |
| Aider (Gauthier) | gpt-4o & claude-3-opus | 26.3 | − |
| OH CodeActAgent v1.8 | gpt-4o-mini-2024-07-18 | 7.0 | 0.01 |
| gpt-4o-2024-05-13 | 22.0 | 1.72 | |
| claude-3-5-sonnet@20240620 | 26.0 | 1.10 | |
| HumanEvalFix (Muennighoff et al., 2024),164 例 | |||
| 提示,0-shot | BLOOMZ-176B | 16.6 | − |
| OctoCoder-15B | 30.4 | − | |
| DeepSeekCoder-33B-Instruct | 47.5 | − | |
| StarCoder2-15B | 48.6 | − | |
| SWE-agent,1-shot (Yang et al., 2024) | gpt-4-turbo | 87.7 | − |
| OH CodeActAgent v1.5(通用,0-shot) | gpt-3.5-turbo-16k-0613 | 20.1 | 0.11 |
| gpt-4o-2024-05-13 | 79.3 | 0.14 | |
| BIRD (Li et al., 2023b),300 例 | |||
| 提示,0-shot | CodeLlama-7B-Instruct | 18.3 | − |
| CodeQwen-7B-Chat | 31.3 | − | |
| OH CodeActAgent v1.5 | gpt-4-1106-preview | 42.7 | 0.19 |
| gpt-4o-2024-05-13 | 47.3 | 0.11 | |
| ML-Bench (Tang et al., 2024b),68 例 | |||
| 提示 + BM25,0-shot | gpt-3.5-turbo | 11.0 | − |
| gpt-4-1106-preview | 22.1 | − | |
| gpt-4o-2024-05-13 | 26.2 | − | |
| SWE-Agent (Yang et al., 2024) | gpt-4-1106-preview | 42.6 | 1.91 |
| Aider (Gauthier) | gpt-4o | 64.4 | − |
| OH CodeActAgent v1.5 | gpt-4o-2024-05-13 | 76.5 | 0.25 |
| gpt-4-1106-preview | 58.8 | 1.22 | |
| gpt-3.5-turbo-16k-0613 | 13.2 | 0.12 | |
| BioCoder (Python) (Tang et al., 2024b),157 例 | |||
| 提示,0-shot | gpt-3.5-turbo | 11.0 | − |
| gpt-4-1106-preview | 12.7 | − | |
| OH CodeActAgent v1.5 | gpt-4o-2024-05-13 | 27.5 | 0.13 |
| Gorilla APIBench (Patil et al., 2023),1775 例 | |||
| 提示,0-shot | claude-v1 | 8.7 | − |
| gpt-4-0314 | 21.2 | − | |
| gpt-3.5-turbo-0301 | 29.7 | − | |
| Gorilla(API 调用微调,0-shot) | llama-7b | 75.0 | − |
| OH CodeActAgent v1.5 | gpt-3.5-turbo-0125 | 21.6 | 0.002 |
| gpt-4o-2024-05-13 | 36.4 | 0.04 | |
| ToolQA (Zhuang et al., 2024),800 例 | |||
| 提示,0-shot | ChatGPT + CoT | 5.1 | − |
| ChatGPT | 5.6 | − | |
| Chameleon | 10.6 | − | |
| ReAct,0-shot | gpt-3.5-turbo | 36.8 | − |
| gpt-3 | 43.1 | − | |
| OH CodeActAgent v1.5 | gpt-3.5-turbo-0125 | 2.3 | 0.03 |
| gpt-4o-2024-05-13 | 47.2 | 0.91 |
SWE-Bench (Jimenez et al., 2024) is designed to assess agents' abilities in solving real-world GitHub issues, such as bug reports or feature requests. The agent interacts with the repository and attempts to fix the issue provided through file editing and code execution. The agent-modified code repository is tested against a test suite incorporating new tests added from human developers' fixes for the same issue. Each test instance accompanies a piece of "hint text" that consists of natural language suggestions for how to solve the problem. Throughout this paper, we report all results without using hint text. A canonical subset, SWE-bench Lite, is created to facilitate accessible and efficient testing. We default to use this subset for testing for cost-saving consideration.² Result. As shown in Tab. 4, our most recent version of CodeActAgent v1.8, using claude-3.5-sonnet, achieves a competitive resolve rate of 26% compared to other open-source SWE specialists.
SWE-Bench(Jimenez et al., 2024)旨在评估智能体解决真实世界 GitHub issue(如 bug 报告或功能请求)的能力。智能体与仓库交互,尝试通过文件编辑与代码执行来修复给定 issue。智能体修改后的代码仓库会对照一个测试套件进行检验,该套件纳入了人类开发者针对同一 issue 的修复所新增的测试。每个测试实例都附带一段"提示文本(hint text)",由关于如何求解问题的自然语言建议构成。本文全篇报告的所有结果均不使用提示文本。为便于低门槛、高效率的测试,官方构建了一个规范子集 SWE-bench Lite;出于成本考虑,我们默认使用该子集进行测试。² 结果:如表 4 所示,我们最新的 CodeActAgent v1.8 搭配 claude-3.5-sonnet,取得 26% 的解决率,与其他开源 SWE 专家方案相比具有竞争力。
脚注 2:以每例 3 美元的保守估计,跑完 2294 个完整实例约需 6.9K 美元。
4.2.1 HumanEvalFix
HumanEvalFix (Muennighoff et al., 2024) tasks agents to fix a bug in a provided function with the help of provided test cases. The bugs are created to ensure one or more test cases fail. We focus on the Python subset of the benchmark and allow models to solve the bugs by self-debug over multiple turns, incorporating feedback from test execution. We follow the setup from Muennighoff et al. (2024) using pass@k (Chen et al., 2021). Results. In Tab. 4, OpenHands CodeActAgent successfully fixes 79.3% of bugs in the Python split. This is significantly better than all non-agentic approaches, almost doubling the performance of StarCoder2-15B (Lozhkov et al., 2024; Li et al., 2023c). While SWE-Agent achieves 87.7%, Yang et al. (2024) provides the model a full demonstration of a successful sample trajectory fixing one of the bugs in the test dataset ("1-shot"), whereas our evaluation of OpenHands is 0-shot. As HumanEvalFix has been created by humans and all bugs carefully validated, achieving 100% on this benchmark is entirely feasible, which we seek to do in future iterations of OpenHands.
HumanEvalFix(Muennighoff et al., 2024)要求智能体借助提供的测试用例修复给定函数中的 bug;这些 bug 的构造保证至少一个测试用例失败。我们聚焦该基准的 Python 子集,允许模型通过多轮自我调试(self-debug)解题,并纳入测试执行的反馈。我们沿用 Muennighoff et al. (2024) 的设定,采用 pass@k(Chen et al., 2021)。结果:表 4 中,OpenHands CodeActAgent 在 Python 子集上成功修复 79.3% 的 bug,显著优于所有非智能体方法,几乎是 StarCoder2-15B(Lozhkov et al., 2024;Li et al., 2023c)的两倍。虽然 SWE-Agent 达到 87.7%,但 Yang et al. (2024) 给模型提供了修复测试集中一个 bug 的完整成功轨迹演示("1-shot"),而我们对 OpenHands 的评测是 0-shot。鉴于 HumanEvalFix 由人工创建、所有 bug 都经过仔细验证,在该基准上达到 100% 完全可行——我们将在 OpenHands 的后续版本中朝此努力。
ML-Bench (Tang et al., 2024b) evaluates agents' ability to solve machine learning tasks across 18 GitHub repositories. The benchmark comprises 9,641 tasks spanning 169 diverse ML problems, requiring agents to generate bash scripts or Python code in response to user instructions. In the sandbox environment, agents can iteratively execute commands and receive feedback, allowing them to understand the repository context and fulfill user requirements progressively. Following the setup from the original paper, we perform agent evaluation on the quarter subset of ML-Bench.
ML-Bench(Tang et al., 2024b)评估智能体跨 18 个 GitHub 仓库解决机器学习任务的能力。该基准包含 9,641 个任务,覆盖 169 个多样的 ML 问题,要求智能体根据用户指令生成 bash 脚本或 Python 代码。在沙箱环境中,智能体可以迭代地执行命令并接收反馈,从而逐步理解仓库上下文、渐进地满足用户需求。我们沿用原论文的设定,在 ML-Bench 的四分之一子集上进行智能体评测。
Gorilla APIBench (Patil et al., 2023) evaluates agents' abilities to use APIs. it incorporates tasks on TorchHub, TensorHub, and HuggingFace. During the evaluation, models are given a question related to API usage, such as "identify an API capable of converting spoken language in a recording to text." Correctness is evaluated based on whether the model's API call is in the correct domain.
Gorilla APIBench(Patil et al., 2023)评估智能体使用 API 的能力,其任务涵盖 TorchHub、TensorHub 与 HuggingFace。评测时,模型会收到一个与 API 用法相关的问题,例如"找出一个能把录音中的语音转换为文本的 API"。正确性依据模型的 API 调用是否属于正确的域(domain)来评判。
ToolQA (Zhuang et al., 2024) evaluates agents' abilities to use external tools. This benchmark includes tasks on various topics like flight status, coffee price, Yelp data, and Airbnb data, requiring the use of various tools such as text tools, database tools, math tools, graph tools, code tools, and system tools. It features two levels: easy and hard. Easy questions focus more on single-tool usage, while hard questions emphasize reasoning. We adopt the easy subset for evaluation.
ToolQA(Zhuang et al., 2024)评估智能体使用外部工具的能力。该基准包含多种主题的任务,如航班状态、咖啡价格、Yelp 数据与 Airbnb 数据,需要使用文本、数据库、数学、图、代码、系统等多种工具。它分为简单(easy)与困难(hard)两个级别:简单问题更侧重单工具使用,困难问题更强调推理。我们采用简单子集进行评测。
BioCoder (Tang et al., 2024c) is a repository-level code generation benchmark that evaluates agents' performance on bioinformatics-related tasks, specifically the ability to retrieve and accurately utilize context. The original prompts contain the relevant context of the code; however, in this study, we have removed them to demonstrate the capability of OpenHands to perform context retrieval, self-debugging, and reasoning in multi-turn interactions. BioCoder consists of 157 Python and 50 Java functions, each targeting a specific area in bioinformatics, such as proteomics, genomics, and other specialized domains. The benchmark targets real-world code by generating code in existing repositories where the relevant code has been masked out.
BioCoder(Tang et al., 2024c)是一个仓库级代码生成基准,评估智能体在生物信息学相关任务上的表现,尤其是检索并准确利用上下文的能力。原始提示包含代码的相关上下文;但本研究中我们将其移除,以展示 OpenHands 在多轮交互中进行上下文检索、自我调试与推理的能力。BioCoder 由 157 个 Python 函数与 50 个 Java 函数组成,每个函数面向生信的一个具体领域,如蛋白质组学、基因组学及其他专业领域。该基准面向真实世界代码:在既有仓库中生成代码,而相关代码已被遮蔽(masked out)。
BIRD (Li et al., 2023b) is a benchmark for text-to-SQL tasks (i.e., translate natural language into executable SQL) aimed at realistic and large-scale database environments. We select 300 samples from the dev set to integrate into OpenHands and evaluate on execution accuracy. Additionally, we extend the setting by allowing the agent to engage in multi-turn interactions to arrive at the final SQL query, enabling it to correct historical results by observing the results of SQL execution.
BIRD(Li et al., 2023b)是一个面向真实、大规模数据库环境的 text-to-SQL(把自然语言翻译成可执行 SQL)基准。我们从其开发集选取 300 个样本整合进 OpenHands,并以执行准确率评测。此外,我们扩展了设定:允许智能体通过多轮交互得到最终 SQL 查询,使其能观察 SQL 执行结果并纠正此前的结果。
4.3 网页浏览
We report evaluation results for web browsing benchmarks in Tab. 5.
我们在表 5 中报告网页浏览基准的评测结果。
[表 5: OpenHands Web Browsing Evaluation Results (§4.3).]
表 5 中文说明:OpenHands 网页浏览评测结果(§4.3),列为智能体、模型、成功率(%)、平均成本(美元/例)。转为 markdown:
| 智能体 | 模型 | 成功率 (%) | $ 平均成本 |
|---|---|---|---|
| WebArena (Zhou et al., 2023a),812 例 | |||
| Lemur (Xu et al., 2023) | Lemur-chat-70b | 5.3 | − |
| Patel et al. (2024) | 训练的 72B(自我改进合成数据) | 9.4 | − |
| AutoWebGLM (Lai et al., 2024) | 训练的 7B(人/智能体混合标注) | 18.2 | − |
| Auto Eval & Refine (Pan et al., 2024) | GPT-4 + Reflexion(GPT-4V 奖励模型) | 20.2 | − |
| WebArena Agent (Zhou et al., 2023a) | gpt-3.5-turbo | 6.2 | − |
| gpt-4-turbo | 14.4 | − | |
| OH BrowsingAgent v1.0 | gpt-4o-mini-2024-07-18 | 8.5 | 0.01 |
| gpt-4o-2024-05-13 | 14.8 | 0.15 | |
| claude-3-5-sonnet-20240620 | 15.5 | 0.10 | |
| OH CodeActAgent v1.8(经委派给 BrowsingAgent v1.0) | gpt-4o-mini-2024-07-18 | 8.3 | − |
| gpt-4o-2024-05-13 | 14.5 | − | |
| claude-3-5-sonnet-20240620 | 15.3 | − | |
| MiniWoB++ (Liu et al., 2018),125 个环境 | |||
| Workflow Guided Exploration (Liu et al., 2018) | 训练的专家模型(环境探索) | 34.6 | − |
| CC-NET (Humphreys et al., 2022) | 训练的专家模型(RL + 人工标注 BC) | 91.1 | − |
| OH BrowsingAgent v1.0 | gpt-3.5-turbo-0125 | 27.2 | 0.01 |
| gpt-4o-2024-05-13 | 40.8 | 0.05 | |
| OH CodeActAgent v1.8(经委派给 BrowsingAgent v1.0) | gpt-4o-2024-05-13 | 39.8 | − |
WebArena (Zhou et al., 2023a) is a self-hostable, execution-based web agent benchmark that allows agents to freely choose which path to take in completing their given tasks. WebArena comprises 812 human-curated task instructions across various domains, including shopping, forums, developer platforms, and content management systems. Results. From Tab. 5, we can see that our BrowsingAgent achieves competitive performance among agents that use LLMs with domain-general prompting techniques.
WebArena(Zhou et al., 2023a)是一个可自托管、基于执行的网页智能体基准,允许智能体自由选择完成给定任务的路径。WebArena 由 812 条人工挑选的任务指令组成,覆盖多个领域,包括购物、论坛、开发者平台与内容管理系统。结果:由表 5 可见,在使用通用领域提示技术的 LLM 智能体当中,我们的 BrowsingAgent 取得了具有竞争力的表现。
MiniWoB++ (Liu et al., 2018) is an interactive web benchmark, with built-in reward functions. The tasks are synthetically initialized on 125 different minimalist web interfaces. Unlike WebArena, tasks are easier without page changes, require fewer steps, and provide low-level step-by-step task directions. Note that it contains a portion of environments that require vision capability to tackle successfully, and many existing work choose to focus only on a subset of the tasks (Kim et al., 2024; Li et al., 2023d; Shaw et al., 2023). Still, we report the performance on the full set and only include baselines that are evaluated on the full set.
MiniWoB++(Liu et al., 2018)是一个交互式网页基准,内置奖励函数。其任务在 125 个不同的极简网页界面上以合成方式初始化。与 WebArena 不同,这些任务更容易:没有页面跳转、步骤更少,并提供低层的逐步任务指引。注意,其中一部分环境需要视觉能力才能成功完成,许多既有工作选择只关注其任务子集(Kim et al., 2024;Li et al., 2023d;Shaw et al., 2023)。尽管如此,我们报告全量任务上的表现,且只纳入在全量集上评测的基线。
4.4 杂项辅助
Results for miscellaneous assistance benchmarks are reported in Tab. 6.
杂项辅助基准的结果报告于表 6。
[表 6: OpenHands miscellaneous assistance evaluation results (§4.4).]
表 6 中文说明:OpenHands 杂项辅助评测结果(§4.4)。要点数据:GAIA(L1 验证集 53 例)上 OH GPTSwarm v1.0 + gpt-4o 达 32.1%(gpt-4-0125-preview 30.2%),远超 AutoGPT 的 13.2%;GPQA(diamond 集 198 例)上 CodeActAgent v1.8 + claude-3-5-sonnet 达 52.0%(人类专家 81.3%、非专家 21.9%;少样本 + CoT 的 gpt-4 为 38.8%);AgentBench OS(bash)子集 144 例上 CodeActAgent v1.5 + gpt-4o 达 57.6%(基线 gpt-4 为 42.4%);MINT 数学子集 225 例上 CodeActAgent v1.5 + gpt-4o 达 77.3%(基线 65.8%),代码子集 136 例为 50.0%(基线 59.6%);ProofWriter(600 例 5-hop)上 CodeActAgent v1.5 + gpt-4o 达 78.8%,与 Logic-LM(gpt-4 + 符号求解器,79.6%)相当;Entity Deduction Arena(200 例)上 CodeActAgent v1.5 + gpt-4o 为 38.0%(零样本 gpt-4-0314 为 40.0%)。各任务每例成本多在 $0.006-$0.11 之间。
GAIA (Mialon et al., 2023) evaluates agents' general task-solving skills, covering different real-world scenarios. It requires various agent capabilities, including reasoning, multi-modal understanding, web browsing, and coding. GAIA consists of 466 curated tasks across three levels. Setting up GAIA is traditionally challenging due to the complexity of integrating various tools with the agent, but OpenHands's infrastructure (e.g., runtime §2.2, tools §2.3) simplifies the integration significantly.
GAIA(Mialon et al., 2023)评估智能体的通用任务解决能力,覆盖不同的真实世界场景。它需要多种智能体能力,包括推理、多模态理解、网页浏览与编程。GAIA 由跨三个难度的 466 个精选任务组成。传统上,由于要把多种工具与智能体集成、复杂度高,GAIA 的搭建颇具挑战,而 OpenHands 的基础设施(如运行时 §2.2、工具 §2.3)显著简化了这一集成。
GPQA (Rein et al., 2023) evaluates agents' ability for coordinated tool use when solving challenging graduate-level problems. Tool use (e.g., python) and web search are often useful to assist agents in answering these questions since they provide accurate calculations that LLMs are often incapable of and access to information outside the LLM's parametric knowledge base.
GPQA(Rein et al., 2023)评估智能体在求解有挑战性的研究生级别问题时协同使用工具的能力。工具使用(如 Python)与网页搜索通常有助于智能体回答这些问题:它们既能提供 LLM 往往无力完成的精确计算,也能提供 LLM 参数化知识库之外的信息。
AgentBench (Liu et al., 2023) evaluates agents' reasoning and decision-making abilities in a multi-turn, open-ended generation setting. We selected the code-grounded operating system (OS) subset with 144 tasks. Agents from OpenHands interact directly with the task-specific OS using bash commands in a multi-turn manner, combining interaction and reasoning to automate task completion.
AgentBench(Liu et al., 2023)在多轮、开放式生成设定下评估智能体的推理与决策能力。我们选取了以代码为根基的操作系统(OS)子集,共 144 个任务。OpenHands 的智能体以多轮方式用 bash 命令直接与任务专属的 OS 交互,把交互与推理结合起来,自动化地完成任务。
MINT (Wang et al., 2024b) is a benchmark designed to evaluate agents' ability to solve challenging tasks through multi-turn interactions using tools and natural language feedback simulated by GPT-4. We use coding and math subsets used in Yuan et al. (2024). We follow the original paper and allow the agent to interact with up to five iterations with two chances to propose solutions.
MINT(Wang et al., 2024b)旨在评估智能体通过多轮交互解决挑战性任务的能力,交互中使用工具以及由 GPT-4 模拟的自然语言反馈。我们使用 Yuan et al. (2024) 所用的编程与数学子集,并沿用原论文设定:允许智能体最多交互五轮,并有两次提出解答的机会。
ProofWriter (Tafjord et al., 2021) is a synthetic dataset created to assess deductive reasoning abilities of LLMs. Same as Logic-LM (Pan et al., 2023), we focus on the most challenging subset, which contains 600 instances requiring 5-hop reasoning. To minimize the impact of potential errors in semantic parsing, we use the logical forms provided by Logic-LM.
ProofWriter(Tafjord et al., 2021)是为评估 LLM 演绎推理能力而创建的合成数据集。与 Logic-LM(Pan et al., 2023)一样,我们聚焦最具挑战性的子集——包含 600 个需要 5 跳(5-hop)推理的实例。为最小化语义解析潜在错误的影响,我们使用 Logic-LM 提供的逻辑形式。
Entity Deduction Arena (EDA) (Zhang et al., 2024a) evaluates agents' ability to deduce unknown entities through strategic questioning, akin to the 20 Questions game. This benchmark tests the agent's state tracking, strategic planning, and inductive reasoning capabilities over multi-turn conversations. We evaluate two datasets "Things" and "Celebrities", each comprising 100 instances, and report the average success rate over these two datasets.
实体演绎竞技场(Entity Deduction Arena,EDA)(Zhang et al., 2024a)评估智能体通过策略性提问推理未知实体的能力,类似"20 个问题"游戏。该基准检验智能体在多轮对话中的状态追踪、策略规划与归纳推理能力。我们评测"Things"与"Celebrities"两个数据集(各 100 个实例),并报告两个数据集的平均成功率。
5 结论
We introduce OpenHands, a community-driven platform that enables the development of agents that interact with the world through software interfaces. By providing a powerful interaction mechanism, a safe sandboxed environment, essential agent skills, multi-agent collaboration capabilities, and a comprehensive evaluation framework, OpenHands accelerates research innovations and real-world applications of agentic AI systems. Despite challenges in developing safe and reliable agents (§A), we are excited about our vibrant community and look forward to OpenHands's continued evolution.
我们提出了 OpenHands——一个社区驱动的平台,支持开发通过软件界面与世界交互的智能体。通过提供强大的交互机制、安全的沙箱环境、必备的智能体技能、多智能体协作能力以及全面的评测框架,OpenHands 加速了智能体 AI 系统的研究创新与真实世界应用。尽管开发安全、可靠的智能体仍存在挑战(§A),我们为充满活力的社区感到振奋,并期待 OpenHands 的持续演进。
译注(收尾):原文第 10 页结论之后为 References 与附录 A-J(含局限与未来工作、伦理声明、相关工作与框架细节、用户界面说明、框架测试与质量控制、运行时实现细节、GPQA 其他子集结果、AgentSkills 完整技能清单、浏览器动作全集、BrowsingAgent 完整提示词等),本对照页按约定不收录,如有需要请查阅原文(arXiv:2407.16741v3 / OpenReview ICLR 2025)。
要点速览
- 一句话:OpenHands = 事件流架构 + Docker 沙箱(bash/IPython/浏览器)+ CodeAct 动作空间 + AgentSkills 工具库 + 多智能体委派 + 15 基准评测框架的开源智能体平台。
- 事件流是中枢:Action/Observation 追加式历史,UI、智能体、运行时三方读写同一流——人可以随时打断/反馈,多智能体天然共享上下文。
- 代码即动作(CodeAct):用执行代码代替枚举 JSON 工具;覆盖面最广、可靠易维护,智能体还能自己写函数造工具;需要 JSON function calling 体验时也能包装提供。
- AgentSkills 收录哲学:LLM 已会的(如 pandas)不重复造轮子;只加"直接写代码做不到"或"需外部模型"的技能——这是工具设计的反直觉但正确原则。
- 安全模型:所有执行隔离在每会话的 Docker 沙箱;action execution API 可装进任意镜像 → 任意软件环境。
- 评测要点:同一 CodeActAgent 零改动横跨 SWE-bench Lite 26% / WebArena 15.3% / GPQA 52%;附每例成本,评测可复现。
- 与课程关联:与 SWE-bench(基准)、SWE-agent(ACI 思想来源,其 edit_file 等被 AgentSkills 吸收)构成编程智能体三角;其"通用 vs 专用"的张力呼应第 5 周 Neubig 的"别小看单智能体系统"之辩(Neubig 正是本文共同作者)。
🖼 原文图表(7 张)—— 提取自原始文献,点击展开
以上图片提取自原始 PDF/网页或 arXiv 官方 HTML 版(含矢量图与原始图注),已镜像至本站;与正文的对应关系请以原文为准。