"Mem0:构建具备可扩展长期记忆的生产级 AI Agent"
"Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory"
推荐全译对照查看原文(PDF) ↗
导读
本文属于第 4 周「Agent 记忆」专题(importance: recommended),是 MemGPT 之后 Agent 记忆方向的重要后续:MemGPT 用"操作系统"隐喻解决"上下文装不下"的问题,而 Mem0(读作 mem-zero)则从生产部署视角出发,把记忆问题重新定义为"如何从持续到来的对话中增量式地抽取、去重、更新与检索显著信息"。
论文来自 Mem0 团队(Chhikara 等,arXiv 2504.19413,2025 年 4 月),提出两个互补架构:基础版 Mem0 用两阶段流水线(抽取 + 更新)把对话蒸馏为自然语言记忆事实,并通过 LLM 工具调用在 ADD / UPDATE / DELETE / NOOP 四种操作间自主决策;图增强版 Mem0g 把记忆表示为有向标签图以捕捉实体关系。在 LOCOMO 长对话基准上,Mem0 相对 OpenAI 的记忆功能在 LLM-as-a-Judge 指标上有 26% 的相对提升,同时相比全上下文方法把 p95 延迟降低 91%、节省 90% 以上的 token 成本——兼顾了记忆质量与生产可行性,是"记忆不仅要准,还要快和省"这一工程立场的代表工作。
全文对照翻译
译注:以下为论文全文中英对照,覆盖摘要至第 5 节结论、第 6 节致谢及附录 A(提示词)、附录 B(算法伪码)、附录 C(基线介绍)的全部实质内容。References(参考文献)按本站惯例不收录。英文原段仅合并了 PDF 提取产生的断行与连字符、并修复了提取导致的字母间距与缺空格(如 "A l ic e"→"Alice"、"introduceMem0"→"introduce Mem0"),内容一字未改;图以「[图 N: 英文图题] + 中文说明」呈现;表 1、表 2 已转为 Markdown 表并保留全部数据(粗体为原文标注的各指标最优值);附录 A 的提示词与附录 B 的算法伪码以代码块原样保留,并以 # 中文注释/译注说明。术语首现处给出中英对照(抽取阶段 extraction phase、更新阶段 update phase、工具调用 tool call、实体抽取器 entity extractor、关系生成器 relationship generator、冲突检测 conflict detection、更新解析器 update resolver 等),LLM/Agent/RAG/token 等通用缩写保留英文。
题目与作者
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
Prateek Chhikara, Dev Khant, Saket Aryan, Taranjeet Singh, and Deshraj Yadav
research@mem0.ai
arXiv:2504.19413v1 [cs.CL] 28 Apr 2025
《Mem0:构建具备可扩展长期记忆的生产级 AI Agent》
作者:Prateek Chhikara、Dev Khant、Saket Aryan、Taranjeet Singh、Deshraj Yadav(联系邮箱 research@mem0.ai);arXiv:2504.19413v1 [cs.CL],2025 年 4 月 28 日。
摘要
Large Language Models (LLMs) have demonstrated remarkable prowess in generating contextually coherent responses, yet their fixed context windows pose fundamental challenges for maintaining consistency over prolonged multi-session dialogues. We introduce Mem0, a scalable memory-centric architecture that addresses this issue by dynamically extracting, consolidating, and retrieving salient information from ongoing conversations. Building on this foundation, we further propose an enhanced variant that leverages graph-based memory representations to capture complex relational structures among conversational elements. Through comprehensive evaluations on the LOCOMO benchmark, we systematically compare our approaches against six baseline categories: (i) established memory-augmented systems, (ii) retrieval-augmented generation (RAG) with varying chunk sizes and k-values, (iii) a full-context approach that processes the entire conversation history, (iv) an open-source memory solution, (v) a proprietary model system, and (vi) a dedicated memory management platform. Empirical results demonstrate that our methods consistently outperform all existing memory systems across four question categories: single-hop, temporal, multi-hop, and open-domain. Notably, Mem0 achieves 26% relative improvements in the LLM-as-a-Judge metric over OpenAI, while Mem0 with graph memory achieves around 2% higher overall score than the base Mem0 configuration. Beyond accuracy gains, we also markedly reduce computational overhead compared to the full-context approach. In particular, Mem0 attains a 91% lower p95 latency and saves more than 90% token cost, thereby offering a compelling balance between advanced reasoning capabilities and practical deployment constraints. Our findings highlight the critical role of structured, persistent memory mechanisms for long-term conversational coherence, paving the way for more reliable and efficient LLM-driven AI agents. Code can be found at: https://mem0.ai/research
大语言模型(LLM)在生成上下文连贯的回复方面表现出色,但其固定的上下文窗口对在跨越多次会话的长期对话中保持一致性构成了根本性挑战。我们提出 Mem0,一个可扩展的、以记忆为中心(memory-centric)的架构,通过从持续进行的对话中动态抽取(extract)、整合(consolidate)与检索(retrieve)显著信息来解决这一问题。在此基础之上,我们进一步提出一个增强变体,利用基于图的记忆表示(graph-based memory)来捕捉对话元素之间复杂的关系结构。通过在 LOCOMO 基准上的全面评估,我们将所提方法与六类基线进行系统对比:(i) 已有记忆增强系统;(ii) 采用不同分块大小(chunk size)与 k 值的检索增强生成(RAG);(iii) 处理全部对话历史的全上下文(full-context)方法;(iv) 开源记忆方案;(v) 专有模型系统;以及 (vi) 专门的记忆管理平台。实验结果表明,所提方法在四类问题——单跳(single-hop)、时序(temporal)、多跳(multi-hop)与开放域(open-domain)——上一致地超越所有现有记忆系统。值得注意的是,Mem0 在 LLM-as-a-Judge 指标上相对 OpenAI 取得 26% 的相对提升,而带图记忆的 Mem0 的总分比基础 Mem0 配置高约 2%。除准确率收益外,我们还相比全上下文方法显著降低了计算开销:具体而言,Mem0 的 p95 延迟降低 91%、token 成本节省超过 90%,从而在高级推理能力与实际部署约束之间提供了引人注目的平衡。我们的发现凸显了结构化、持久记忆机制对长期对话连贯性的关键作用,为更可靠、更高效的 LLM 驱动 AI Agent 铺平了道路。代码见:https://mem0.ai/research
1 引言
Human memory is a foundation of intelligence—it shapes our identity, guides decision-making, and enables us to learn, adapt, and form meaningful relationships (Craik and Jennings, 1992). Among its many roles, memory is essential for communication: we recall past interactions, infer preferences, and construct evolving mental models of those we engage with (Assmann, 2011). This ability to retain and retrieve information over extended periods enables coherent, contextually rich exchanges that span days, weeks, or even months. AI agents, powered by large language models (LLMs), have made remarkable progress in generating fluent, contextually appropriate responses (Yu et al., 2024, Zhang et al., 2024). However, these systems are fundamentally limited by their reliance on fixed context windows, which severely restrict their ability to maintain coherence over extended interactions (Bulatov et al., 2022, Liu et al., 2023). This limitation stems from LLMs' lack of persistent memory mechanisms that can extend beyond their finite context windows. While humans naturally accumulate and organize experiences over time, forming a continuous narrative of interactions, AI systems cannot inherently persist information across separate sessions or after context overflow. The absence of persistent memory creates a fundamental disconnect in human-AI interaction. Without memory, AI agents forget user preferences, repeat questions, and contradict previously established facts. Consider a simple example illustrated in Figure 1, where a user mentions being vegetarian and avoiding dairy products in an initial conversation. In a subsequent session, when the user asks about dinner recommendations, a system without persistent memory might suggest chicken, completely contradicting the established dietary preferences. In contrast, a system with persistent memory would maintain this critical user information across sessions and suggest appropriate vegetarian, dairy-free options. This common scenario highlights how memory failures can fundamentally undermine user experience and trust.
人类记忆是智能的基石——它塑造我们的身份、指导决策,并使我们能够学习、适应并建立有意义的关系(Craik and Jennings, 1992)。在记忆的诸多作用中,它对沟通至关重要:我们回忆过去的交互、推断偏好,并对交流对象构建不断演化的心智模型(Assmann, 2011)。这种在较长时期内保留和检索信息的能力,支撑起跨越数天、数周甚至数月的连贯且语境丰富的交流。由大语言模型(LLM)驱动的 AI Agent 在生成流畅、贴合语境的回复方面已取得显著进展(Yu et al., 2024, Zhang et al., 2024)。然而,这些系统从根本上受限于对固定上下文窗口的依赖,这严重制约了它们在长期交互中保持连贯的能力(Bulatov et al., 2022, Liu et al., 2023)。这一局限源于 LLM 缺乏能超越其有限上下文窗口的持久记忆机制。人类会随时间自然地积累并组织经验,形成连续的交互叙事;而 AI 系统无法天然地跨独立会话或在上下文溢出之后持久保存信息。持久记忆的缺失在人机交互中造成根本性的断裂:没有记忆,AI Agent 会忘记用户偏好、重复提问、与既定事实自相矛盾。考虑图 1 所示的一个简单例子:用户在初次对话中提到自己吃素且不吃乳制品。在随后的会话中,当用户询问晚餐建议时,没有持久记忆的系统可能推荐鸡肉,彻底违背已确立的饮食偏好;相比之下,拥有持久记忆的系统会跨会话保留这一关键用户信息,并推荐合适的素食、无乳制品选项。这一常见场景凸显了记忆失败会如何从根本上损害用户体验与信任。
[图 1: Illustration of memory importance in AI agents. Left: Without persistent memory, the system forgets critical user information (vegetarian, dairy-free preferences) between sessions, resulting in inappropriate recommendations. Right: With effective memory, the system maintains these dietary preferences across interactions, enabling contextually appropriate suggestions that align with previously established constraints.]
图 1 说明:展示记忆对 AI Agent 的重要性。左:没有持久记忆时,系统在会话之间忘记关键用户信息(素食、无乳制品偏好),导致不当推荐;右:拥有有效记忆时,系统在多次交互中保持这些饮食偏好,从而给出与既往既定约束相符的、贴合语境的建议。
Beyond conversational settings, memory mechanisms have been shown to dramatically enhance agent performance in interactive environments (Majumder et al., Shinn et al., 2023). Agents equipped with memory of past experiences can better anticipate user needs, learn from previous mistakes, and generalize knowledge across tasks (Chhikara et al., 2023). Research demonstrates that memory-augmented agents improve decision-making by leveraging causal relationships between actions and outcomes, leading to more effective adaptation in dynamic scenarios (Rasmussen et al., 2025). Hierarchical memory architectures (Packer et al., 2023, Sarthi et al., 2024) and agentic memory systems capable of autonomous evolution (Xu et al., 2025) have further shown that memory enables more coherent, long-term reasoning across multiple dialogue sessions.
在对话场景之外,记忆机制已被证明能显著提升 Agent 在交互式环境中的表现(Majumder et al., Shinn et al., 2023)。配备过往经验记忆的 Agent 能更好地预判用户需求、从过去的错误中学习,并跨任务泛化知识(Chhikara et al., 2023)。研究表明,记忆增强的 Agent 通过利用动作与结果之间的因果关系来改进决策,从而在动态场景中实现更有效的适应(Rasmussen et al., 2025)。分层记忆架构(Packer et al., 2023, Sarthi et al., 2024)以及能够自主演化的 Agent 式记忆系统(Xu et al., 2025)进一步表明,记忆能够支持跨多个对话会话的更连贯、更长期的推理。
Unlike humans, who dynamically integrate new information and revise outdated beliefs, LLMs effectively "reset" once information falls outside their context window (Zhang, 2024, Timoneda and Vera, 2025). Even as models like OpenAI's GPT-4 (128K tokens) (Hurst et al., 2024), o1 (200K context) (Jaech et al., 2024), Anthropic's Claude 3.7 Sonnet (200K tokens) (Anthropic, 2025), and Google's Gemini (at least 10M tokens) (Team et al., 2024) push the boundaries of context length, these improvements merely delay rather than solve the fundamental limitation. In practical applications, even these extended context windows prove insufficient for two critical reasons. First, as meaningful human-AI relationships develop over weeks or months, conversation history inevitably exceeds even the most generous context limits. Second, and perhaps more importantly, real-world conversations rarely maintain thematic continuity. A user might mention dietary preferences (being vegetarian), then engage in hours of unrelated discussion about programming tasks, before returning to food-related queries about dinner options. In such scenarios, a full-context approach would need to reason through mountains of irrelevant information, with the critical dietary preferences potentially buried among thousands of tokens of coding discussions. Moreover, simply presenting longer contexts does not ensure effective retrieval or utilization of past information, as attention mechanisms degrade over distant tokens (Guo et al., 2024, Nelson et al., 2024). This limitation is particularly problematic in high-stakes domains such as healthcare, education, and enterprise support, where maintaining continuity and trust is crucial (Hatalis et al., 2023). To address these challenges, AI agents must adopt memory systems that go beyond static context extension. A robust AI memory should selectively store important information, consolidate related concepts, and retrieve relevant details when needed—mirroring human cognitive processes (He et al., 2024). By integrating such mechanisms, we can develop AI agents that maintain consistent personas, track evolving user preferences, and build upon prior exchanges. This shift will transform AI from transient, forgetful responders into reliable, long-term collaborators, fundamentally redefining the future of conversational intelligence.
与人类不同——人类会动态整合新信息并修正过时信念——LLM 一旦信息滑出其上下文窗口,实际上就会"重置"(Zhang, 2024, Timoneda and Vera, 2025)。即便 OpenAI 的 GPT-4(128K token)(Hurst et al., 2024)、o1(200K 上下文)(Jaech et al., 2024)、Anthropic 的 Claude 3.7 Sonnet(200K token)(Anthropic, 2025)以及 Google 的 Gemini(至少 10M token)(Team et al., 2024)等模型不断刷新上下文长度,这些改进也只是推迟而非解决根本局限。在实际应用中,即使这些扩展的上下文窗口也不够用,原因有二。其一,随着有意义的人机关系在数周或数月中发展,对话历史不可避免地超出即使是最宽裕的上下文上限。其二,或许更重要的是,真实世界的对话很少保持主题连续性。用户可能先提到饮食偏好(吃素),然后花几个小时讨论无关的编程任务,之后再回到关于晚餐选择的食品相关提问。在这种场景下,全上下文方法需要在海量无关信息中进行推理,关键的饮食偏好可能被埋没在数千 token 的编程讨论之中。此外,仅仅呈现更长的上下文并不能保证对过往信息的有效检索或利用,因为注意力机制在远距离 token 上会退化(Guo et al., 2024, Nelson et al., 2024)。这一局限在医疗、教育与企业支持等高风险领域尤为棘手,因为在这些领域维持连续性与信任至关重要(Hatalis et al., 2023)。为应对这些挑战,AI Agent 必须采用超越静态上下文扩展的记忆系统。健壮的 AI 记忆应当有选择地存储重要信息、整合相关概念、并在需要时检索相关细节——镜像人类认知过程(He et al., 2024)。通过集成此类机制,我们可以开发出保持一致人格、追踪演化中的用户偏好、并在既往交流基础上不断积累的 AI Agent。这一转变将把 AI 从短暂的、健忘的应答者转变为可靠的长期协作者,从根本上重新定义对话智能的未来。
In this paper, we address a fundamental limitation in AI systems: their inability to maintain coherent reasoning across extended conversations across different sessions, which severely restricts meaningful long-term interactions with users. We introduce Mem0 (pronounced as mem-zero), a novel memory architecture that dynamically captures, organizes, and retrieves salient information from ongoing conversations. Building on this foundation, we develop Mem0g, which enhances the base architecture with graph-based memory representations to better model complex relationships between conversational elements. Our experimental results on the LOCOMO benchmark demonstrate that our approaches consistently outperform existing memory systems—including memory-augmented architectures, retrieval-augmented generation (RAG) methods, and both open-source and proprietary solutions—across diverse question types, while simultaneously requiring significantly lower computational resources. Latency measurements further reveal that Mem0 operates with 91% lower response times than full-context approaches, striking an optimal balance between sophisticated reasoning capabilities and practical deployment constraints. These contributions represent a meaningful step toward AI systems that can maintain coherent, context-aware conversations over extended durations—mirroring human communication patterns and opening new possibilities for applications in personal tutoring, healthcare, and personalized assistance.
在本文中,我们解决 AI 系统的一个根本局限:无法在不同会话的扩展对话中保持连贯推理,这严重限制了与用户进行有意义的长期交互。我们提出 Mem0(读作 mem-zero),一种新颖的记忆架构,能从持续进行的对话中动态捕捉、组织并检索显著信息。在此基础之上,我们开发了 Mem0g,它以基于图的记忆表示增强基础架构,以更好地建模对话元素之间的复杂关系。我们在 LOCOMO 基准上的实验结果表明,所提方法在多样的问题类型上一致地超越现有记忆系统——包括记忆增强架构、检索增强生成(RAG)方法以及开源与闭源方案——同时所需计算资源显著更低。延迟测量进一步揭示,Mem0 的响应时间比全上下文方法低 91%,在精细的推理能力与实际部署约束之间取得了最优平衡。这些贡献代表了向"能够在较长时间内保持连贯、上下文感知对话的 AI 系统"迈出的重要一步——镜像人类沟通模式,并为个人辅导、医疗健康与个性化助理等应用开辟新的可能。
2 所提方法
We introduce two memory architectures for AI agents. (1) Mem0 implements a novel paradigm that extracts, evaluates, and manages salient information from conversations through dedicated modules for memory extraction and updation. The system processes a pair of messages between either two user participants or a user and an assistant. (2) Mem0g extends this foundation by incorporating graph-based memory representations, where memories are stored as directed labeled graphs with entities as nodes and relationships as edges. This structure enables a deeper understanding of the connections between entities. By explicitly modeling both entities and their relationships, Mem0g supports more advanced reasoning across interconnected facts, especially for queries that require navigating complex relational paths across multiple memories.
我们为 AI Agent 提出两种记忆架构。(1) Mem0 实现了一种新颖范式,通过专门的记忆抽取与更新模块,从对话中抽取、评估并管理显著信息。该系统处理两个用户参与者之间、或用户与助手之间的一对消息。(2) Mem0g 在此基础上引入基于图的记忆表示:记忆被存储为有向标签图,实体为节点、关系为边。这一结构使系统能够更深入地理解实体之间的联系。通过显式地同时建模实体及其关系,Mem0g 支持对相互关联事实的更高级推理,尤其是需要在多条记忆之间穿越复杂关系路径的查询。
2.1 Mem0
Our architecture follows an incremental processing paradigm, enabling it to operate seamlessly within ongoing conversations. As illustrated in Figure 2, the complete pipeline architecture consists of two phases: extraction and update.
我们的架构遵循增量式(incremental)处理范式,使其能在进行中的对话内无缝运行。如图 2 所示,完整的流水线架构由两个阶段组成:抽取(extraction)与更新(update)。
The extraction phase initiates upon ingestion of a new message pair (mₜ₋₁, mₜ), where mₜ represents the current message and mₜ₋₁ the preceding one. This pair typically consists of a user message and an assistant response, capturing a complete interaction unit. To establish appropriate context for memory extraction, the system employs two complementary sources: (1) a conversation summary S retrieved from the database that encapsulates the semantic content of the entire conversation history, and (2) a sequence of recent messages {mₜ₋ₘ, mₜ₋ₘ₊₁, ..., mₜ₋₂} from the conversation history, where m is a hyperparameter controlling the recency window. To support context-aware memory extraction, we implement an asynchronous summary generation module that periodically refreshes the conversation summary. This component operates independently of the main processing pipeline, ensuring that memory extraction consistently benefits from up-to-date contextual information without introducing processing delays. While S provides global thematic understanding across the entire conversation, the recent message sequence offers granular temporal context that may contain relevant details not consolidated in the summary. This dual contextual information, combined with the new message pair, forms a comprehensive prompt P = (S, {mₜ₋ₘ, ..., mₜ₋₂}, mₜ₋₁, mₜ) for an extraction function ϕ implemented via an LLM. The function ϕ(P) then extracts a set of salient memories Ω = {ω₁, ω₂, ..., ωₙ} specifically from the new exchange while maintaining awareness of the conversation's broader context, resulting in candidate facts for potential inclusion in the knowledge base.
抽取阶段在新消息对 (mₜ₋₁, mₜ) 到达时启动,其中 mₜ 表示当前消息,mₜ₋₁ 表示前一条消息。这一对通常由一条用户消息和一条助手回复组成,构成一个完整的交互单元。为给记忆抽取建立合适的语境,系统采用两个互补的来源:(1) 从数据库取回的对话摘要 S,它概括了整个对话历史的语义内容;(2) 对话历史中的近期消息序列 {mₜ₋ₘ, mₜ₋ₘ₊₁, ..., mₜ₋₂},其中 m 是控制近期窗口大小的超参数。为支持上下文感知的记忆抽取,我们实现了一个异步摘要生成模块,周期性地刷新对话摘要。该组件独立于主流水线运行,确保记忆抽取始终受益于最新的语境信息而不引入处理延迟。S 提供跨整个对话的全局主题理解,而近期消息序列提供细粒度的时序上下文,其中可能包含尚未整合进摘要的相关细节。这一双重上下文信息与新消息对一起,构成完整的提示 P = (S, {mₜ₋ₘ, ..., mₜ₋₂}, mₜ₋₁, mₜ),交给由 LLM 实现的抽取函数 ϕ。函数 ϕ(P) 随后专门从新交互中抽取一组显著记忆 Ω = {ω₁, ω₂, ..., ωₙ},同时保持对对话更宏观语境的感知,得到可能纳入知识库的候选事实。
[图 2: Architectural overview of the Mem0 system showing extraction and update phase. The extraction phase processes messages and historical context to create new memories. The update phase evaluates these extracted memories against similar existing ones, applying appropriate operations through a Tool Call mechanism. The database serves as the central repository, providing context for processing and storing updated memories.]
图 2 说明:Mem0 系统架构总览,展示抽取阶段与更新阶段。抽取阶段处理消息与历史上下文以创建新记忆;更新阶段将这些抽取出的记忆与相似的既有记忆对照评估,通过工具调用(Tool Call)机制应用相应操作;数据库作为中心仓库,既为处理提供上下文,也存储更新后的记忆。
Following extraction, the update phase evaluates each candidate fact against existing memories to maintain consistency and avoid redundancy. This phase determines the appropriate memory management operation for each extracted fact ωᵢ ∈ Ω. Algorithm 1, mentioned in Appendix B, illustrates this process. For each fact, the system first retrieves the top s semantically similar memories using vector embeddings from the database. These retrieved memories, along with the candidate fact, are then presented to the LLM through a function-calling interface we refer to as a 'tool call.' The LLM itself determines which of four distinct operations to execute: ADD for creation of new memories when no semantically equivalent memory exists; UPDATE for augmentation of existing memories with complementary information; DELETE for removal of memories contradicted by new information; and NOOP when the candidate fact requires no modification to the knowledge base. Rather than using a separate classifier, we leverage the LLM's reasoning capabilities to directly select the appropriate operation based on the semantic relationship between the candidate fact and existing memories. Following this determination, the system executes the provided operations, thereby maintaining knowledge base coherence and temporal consistency.
抽取之后,更新阶段将每条候选事实与既有记忆对照评估,以维护一致性并避免冗余。该阶段为每条抽取出的事实 ωᵢ ∈ Ω 确定合适的记忆管理操作。附录 B 中的算法 1 展示了这一过程。对每条事实,系统首先用向量嵌入从数据库检索语义最相似的 top-s 条记忆。这些检索到的记忆连同候选事实一起,通过我们称为"工具调用(tool call)"的函数调用接口呈现给 LLM。由 LLM 自身决定执行四种操作中的哪一种:ADD——当不存在语义等价记忆时创建新记忆;UPDATE——用互补信息增强既有记忆;DELETE——移除被新信息矛盾的记忆;NOOP——候选事实无需对知识库做任何修改。我们不使用单独的分类器,而是利用 LLM 的推理能力,基于候选事实与既有记忆之间的语义关系直接选择合适的操作。这一判定之后,系统执行相应操作,从而维护知识库的连贯性与时序一致性。
In our experimental evaluation, we configured the system with 'm' = 10 previous messages for contextual reference and 's' = 10 similar memories for comparative analysis. All language model operations utilized GPT-4o-mini as the inference engine. The vector database employs dense embeddings to facilitate efficient similarity search during the update phase.
在我们的实验评估中,系统配置为 m = 10 条既往消息作为上下文参考、s = 10 条相似记忆用于对比分析。所有语言模型操作均使用 GPT-4o-mini 作为推理引擎。向量数据库采用稠密嵌入,以在更新阶段支持高效的相似度搜索。
2.2 Mem0g
The Mem0g pipeline, illustrated in Figure 3, implements a graph-based memory approach that effectively captures, stores, and retrieves contextual information from natural language interactions (Zhang et al., 2022). In this framework, memories are represented as a directed labeled graph G = (V, E, L), where:
- Nodes V represent entities (e.g., Alice, San_Francisco)
- Edges E represent relationships between entities (e.g., lives_in)
- Labels L assign semantic types to nodes (e.g., Alice-Person, San_Francisco-City)
如图 3 所示的 Mem0g 流程实现了一种基于图的记忆方法,能有效地从自然语言交互中捕捉、存储并检索上下文信息(Zhang et al., 2022)。在该框架中,记忆被表示为有向标签图 G = (V, E, L),其中:
- 节点 V 表示实体(如 Alice、San_Francisco);
- 边 E 表示实体间的关系(如 lives_in);
- 标签 L 为节点赋予语义类型(如 Alice–Person、San_Francisco–City)。
[图 3: Graph-based memory architecture of Mem0g illustrating entity extraction and update phase. The extraction phase uses LLMs to convert conversation messages into entities and relation triplets. The update phase employs conflict detection and resolution mechanisms when integrating new information into the existing knowledge graph.]
图 3 说明:Mem0g 的基于图的记忆架构,展示实体抽取与更新阶段。抽取阶段用 LLM 将对话消息转换为实体与关系三元组;更新阶段在把新信息整合进既有知识图时,采用冲突检测与消解机制。
Each entity node v ∈ V contains three components: (1) an entity type classification that categorizes the entity (e.g., Person, Location, Event), (2) an embedding vector eᵥ that captures the entity's semantic meaning, and (3) metadata including a creation timestamp tᵥ. Relationships in our system are structured as triplets in the form (vₛ, r, v_d), where vₛ and v_d are source and destination entity nodes, respectively, and r is the labeled edge connecting them.
每个实体节点 v ∈ V 包含三个组成部分:(1) 实体类型分类,对实体进行归类(如 Person、Location、Event);(2) 嵌入向量 eᵥ,捕捉该实体的语义;(3) 元数据,包括创建时间戳 tᵥ。在我们的系统中,关系被组织为形如 (vₛ, r, v_d) 的三元组,其中 vₛ 与 v_d 分别是源实体节点与目标实体节点,r 是连接它们的带标签边。
The extraction process employs a two-stage pipeline leveraging LLMs to transform unstructured text into structured graph representations. First, an entity extractor module processes the input text to identify a set of entities along with their corresponding types. In our framework, entities represent the key information elements in conversations—including people, locations, objects, concepts, events, and attributes that merit representation in the memory graph. The entity extractor identifies these diverse information units by analyzing the semantic importance, uniqueness, and persistence of elements in the conversation. For instance, in a conversation about travel plans, entities might include destinations (cities, countries), transportation modes, dates, activities, and participant preferences—essentially any discrete information that could be relevant for future reference or reasoning.
抽取过程采用两阶段流水线,利用 LLM 将非结构化文本转换为结构化的图表示。首先,实体抽取器(entity extractor)模块处理输入文本,识别一组实体及其对应类型。在我们的框架中,实体代表对话中的关键信息元素——包括人、地点、物品、概念、事件与属性,凡值得在记忆图中表示者皆属之。实体抽取器通过分析对话中各元素的语义重要性、唯一性与持久性来识别这些多样的信息单元。例如,在一段关于旅行计划的对话中,实体可能包括目的地(城市、国家)、交通方式、日期、活动与参与者偏好——本质上是任何可能对将来参考或推理有意义的离散信息。
Next, a relationship generator component derives meaningful connections between these entities, establishing a set of relationship triplets that capture the semantic structure of the information. This LLM-based module analyzes the extracted entities and their context within the conversation to identify semantically significant connections. It works by examining linguistic patterns, contextual cues, and domain knowledge to determine how entities relate to one another. For each potential entity pair, the generator evaluates whether a meaningful relationship exists and, if so, classifies this relationship with an appropriate label (e.g., 'lives_in', 'prefers', 'owns', 'happened_on'). The module employs prompt engineering techniques that guide the LLM to reason about both explicit statements and implicit information in the dialogue, resulting in relationship triplets that form the edges in our memory graph and enable complex reasoning across interconnected information. When integrating new information, Mem0g employs a sophisticated storage and update strategy. For each new relationship triple, we compute embeddings for both source and destination entities, then search for existing nodes with semantic similarity above a defined threshold 't'. Based on node existence, the system may create both nodes, create only one node, or use existing nodes before establishing the relationship with appropriate metadata. To maintain a consistent knowledge graph, we implement a conflict detection mechanism that identifies potentially conflicting existing relationships when new information arrives. An LLM-based update resolver determines if certain relationships should be obsolete, marking them as invalid rather than physically removing them to enable temporal reasoning.
接着,关系生成器(relationship generator)组件在这些实体之间推导有意义的连接,建立一组关系三元组以捕捉信息的语义结构。这一基于 LLM 的模块分析抽取出的实体及其在对话中的上下文,以识别语义上显著的连接。它通过考察语言模式、上下文线索与领域知识来判断实体之间如何关联。对每个潜在的实体对,生成器评估是否存在有意义的关系;若存在,则用合适的标签对这一关系分类(如 'lives_in'、'prefers'、'owns'、'happened_on')。该模块采用提示工程技术,引导 LLM 同时对对话中的显式陈述与隐式信息进行推理,所得到的关系三元组构成记忆图中的边,并支持对相互关联信息的复杂推理。在整合新信息时,Mem0g 采用一套精细的存储与更新策略。对每个新的关系三元组,我们为源实体与目标实体分别计算嵌入,然后检索语义相似度超过设定阈值 t 的既有节点。依据节点存在与否,系统可以创建两个节点、只创建一个节点,或复用既有节点,再附带合适的元数据建立关系。为维护一致的知识图,我们实现了冲突检测机制(conflict detection),在新信息到来时识别可能存在冲突的既有关系。基于 LLM 的更新解析器(update resolver)判定某些关系是否应被视为过时,将其标记为无效而非物理删除,以支持时序推理(temporal reasoning)。
The memory retrieval functionality in Mem0g implements a dual-approach strategy for optimal information access. The entity-centric method first identifies key entities within a query, then leverages semantic similarity to locate corresponding nodes in the knowledge graph. It systematically explores both incoming and outgoing relationships from these anchor nodes, constructing a comprehensive subgraph that captures relevant contextual information. Complementing this, the semantic triplet approach takes a more holistic view by encoding the entire query as a dense embedding vector. This query representation is then matched against textual encodings of each relationship triplet in the knowledge graph. The system calculates fine-grained similarity scores between the query and all available triplets, returning only those that exceed a configurable relevance threshold, ranked in order of decreasing similarity. This dual retrieval mechanism enables Mem0g to handle both targeted entity-focused questions and broader conceptual queries with equal effectiveness.
Mem0g 的记忆检索功能实现了双路策略(dual-approach)以获得最优的信息访问。实体中心(entity-centric)方法首先识别查询中的关键实体,然后利用语义相似度在知识图中定位对应节点;它系统地探索这些锚节点的入边与出边关系,构建覆盖相关上下文信息的完整子图。与之互补,语义三元组(semantic triplet)方法采取更整体的视角,把整个查询编码为稠密嵌入向量;该查询表示再与知识图中每条关系三元组的文本编码进行匹配。系统计算查询与所有可用三元组之间的细粒度相似度得分,只返回超过可配置相关性阈值的结果,并按相似度降序排列。这一双重检索机制使 Mem0g 能够同等有效地处理聚焦特定实体的问题与更宽泛的概念型查询。
From an implementation perspective, the system utilizes Neo4j as the underlying graph database. LLM-based extractors and update module leverage GPT-4o-mini with function calling capabilities, allowing for structured extraction of information from unstructured text. By combining graph-based representations with semantic embeddings and LLM-based information extraction, Mem0g achieves both the structural richness needed for complex reasoning and the semantic flexibility required for natural language understanding.
从实现角度看,系统采用 Neo4j 作为底层图数据库。基于 LLM 的抽取器与更新模块利用 GPT-4o-mini 的函数调用能力,从非结构化文本中进行结构化信息抽取。通过将基于图的表示、语义嵌入与基于 LLM 的信息抽取相结合,Mem0g 同时具备复杂推理所需的结构丰富性与自然语言理解所需的语义灵活性。
3 实验设置
3.1 数据集
The LOCOMO (Maharana et al., 2024) dataset is designed to evaluate long-term conversational memory in dialogue systems. It comprises 10 extended conversations, each containing approximately 600 dialogues and 26000 tokens on average, distributed across multiple sessions. Each conversation captures two individuals discussing daily experiences or past events. Following these multi-session dialogues, each conversation is accompanied by 200 questions on an average with corresponding ground truth answers. These questions are categorized into multiple types: single-hop, multi-hop, temporal, and open-domain. The dataset originally included an adversarial question category, which was designed to test systems' ability to recognize unanswerable questions. However, this category was excluded from our evaluation because ground truth answers were unavailable, and the expected behavior for this question type is that the agent should recognize them as unanswerable.
LOCOMO(Maharana et al., 2024)数据集旨在评估对话系统的长期对话记忆。它包含 10 段扩展对话,每段平均包含约 600 轮对话和 26,000 token,分布在多个会话中。每段对话记录两个人讨论日常经历或过去的事件。在这些多会话对话之后,每段对话平均配有 200 道带标准答案(ground truth)的问题。这些问题分为多种类型:单跳、多跳、时序与开放域。数据集原本还包括一类"对抗(adversarial)"问题,用于测试系统识别不可回答问题的能力。但该类别被排除在我们的评估之外,因为其缺少标准答案,且这一题型的预期行为是 Agent 应将其识别为不可回答。
3.2 评估指标
Our evaluation framework implements a comprehensive approach to assess long-term memory capabilities in dialogue systems, considering both response quality and operational efficiency. We categorize our metrics into two distinct groups that together provide a holistic understanding of system performance.
我们的评估框架采用综合方法来评估对话系统的长期记忆能力,同时考虑回复质量与运行效率。我们将指标分为两组,二者共同提供对系统性能的整体刻画。
(1) Performance Metrics Previous research in conversational AI (Goswami, 2025, Soni et al., 2024, Singh et al., 2020) has predominantly relied on lexical similarity metrics such as F1 Score (F1) and BLEU-1 (B1). However, these metrics exhibit significant limitations when evaluating factual accuracy in conversational contexts. Consider a scenario where the ground truth answer is 'Alice was born in March' and a system generates 'Alice is born in July.' Despite containing a critical factual error regarding the birth month, traditional metrics would assign relatively high scores due to lexical overlap in the remaining tokens ('Alice,' 'born,' etc.). This fundamental limitation can lead to misleading evaluations that fail to capture semantic correctness.
(1) 性能指标。对话式 AI 的既往研究(Goswami, 2025, Soni et al., 2024, Singh et al., 2020)主要依赖 F1 分数(F1)与 BLEU-1(B1)等词法相似度指标。然而,这些指标在评估对话场景下的事实准确性时存在显著局限。设想标准答案为"Alice was born in March"(Alice 生于三月)而系统生成"Alice is born in July"(Alice 生于七月):尽管出生月份存在关键性事实错误,传统指标仍会因其余词元('Alice'、'born' 等)的词法重叠而给出较高的分数。这一根本局限可能导致误导性的评估,无法刻画语义正确性。
To address these shortcomings, we use LLM-as-a-Judge (J) as a complementary evaluation metric. This approach leverages a separate, more capable LLM to assess response quality across multiple dimensions, including factual accuracy, relevance, completeness, and contextual appropriateness. The judge model analyzes the question, ground truth answer and the generated answer, providing a more nuanced evaluation that aligns better with human judgment. Due to the stochastic nature of J evaluations, we conducted 10 independent runs for each method on the entire dataset and report the mean scores along with ±1 standard deviation. More details about the J is present in Appendix A.
为弥补这些缺陷,我们采用 LLM-as-a-Judge(J)作为补充评估指标。该方法利用一个独立、更强的 LLM 从多个维度评估回复质量,包括事实准确性、相关性、完整性与语境恰当性。裁判模型分析问题、标准答案与生成的答案,给出更细致、与人类判断更契合的评估。考虑到 J 评估的随机性,我们对每种方法在整个数据集上进行 10 次独立运行,报告均值分数及 ±1 标准差。关于 J 的更多细节见附录 A。
(2) Deployment Metrics Beyond response quality, practical deployment considerations are crucial for real-world applications of long-term memory in AI agents. We systematically track Token Consumption, using 'cl100k_base' encoding from tiktoken, measuring the number of tokens extracted during retrieval that serve as context for answering queries. For our memory-based models, these tokens represent the memories retrieved from the knowledge base, while for RAG-based models, they correspond to the total number of tokens in the retrieved text chunks. This distinction is important as it directly affects operational costs and system efficiency—whether processing concise memory facts or larger raw text segments. We further monitor Latency, (i) search latency: which captures the total time required to search the memory (in memory-based solutions) or chunk (in RAG-based solutions) and (ii) total latency: time to generate appropriate responses, consisting of both retrieval time (accessing memories or chunks) and answer generation time using the LLM.
(2) 部署指标。除回复质量外,实际部署考量对 AI Agent 长期记忆的真实应用至关重要。我们系统追踪 Token 消耗(Token Consumption):用 tiktoken 的 'cl100k_base' 编码,统计检索时抽取的、用于为查询提供上下文的 token 数。对我们的记忆型模型,这些 token 表示从知识库检索到的记忆;对 RAG 型模型,则对应检索到的文本块中的 token 总数。这一区分很重要,因为它直接影响运营成本与系统效率——处理的是简洁的记忆事实还是更大的原始文本段。我们还监测延迟(Latency):(i) 检索延迟(search latency),捕捉搜索记忆(记忆型方案)或文本块(RAG 型方案)所需的总时间;(ii) 总延迟(total latency),即生成恰当回复的时间,由检索时间(访问记忆或文本块)与用 LLM 生成回答的时间共同构成。
The relationship between these metrics reveals important trade-offs in system design. For instance, more sophisticated memory architectures might achieve higher factual accuracy but at the cost of increased token consumption and latency. Our multi-dimensional evaluation methodology enables researchers and practitioners to make informed decisions based on their specific requirements, whether prioritizing response quality for critical applications or computational efficiency for real-time deployment scenarios.
这些指标之间的关系揭示了系统设计中的重要权衡。例如,更精细的记忆架构可能获得更高的事实准确性,但代价是更高的 token 消耗与延迟。我们的多维评估方法使研究者与从业者能基于自身具体需求做出知情决策——无论是对关键应用优先回复质量,还是对实时部署场景优先计算效率。
3.3 基线
To comprehensively evaluate our approach, we compare against six distinct categories of baselines that represent the current state of conversational memory systems. These diverse baselines collectively provide a robust framework for evaluating the effectiveness of different memory architectures across various dimensions, including factual accuracy, computational efficiency, and scalability to extended conversations. Where applicable, unless otherwise specified, we set the temperature to 0 to ensure the runs are as reproducible as possible.
为全面评估我们的方法,我们与六类不同的基线进行比较,它们代表了当前对话记忆系统的状况。这些多样的基线共同提供了一个稳健的框架,用于从多个维度评估不同记忆架构的有效性,包括事实准确性、计算效率与对长对话的可扩展性。在适用之处,除非特别说明,我们将温度设为 0,以尽可能保证运行的可复现性。
Established LOCOMO Benchmarks We first establish a comparative foundation by evaluating previously benchmarked methods on the LOCOMO dataset. These include five established approaches: LoCoMo (Maharana et al., 2024), ReadAgent (Lee et al., 2024), MemoryBank (Zhong et al., 2024), MemGPT (Packer et al., 2023), and A-Mem (Xu et al., 2025). These established benchmarks not only provide direct comparison points with published results but also represent the evolution of conversational memory architectures across different algorithmic paradigms. For our evaluation, we select the metrics where gpt-4o-mini was used for the evaluation. More details about these benchmarks are mentioned in Appendix C.
既有 LOCOMO 基准。我们首先评估 LOCOMO 数据集上已有基准结果的方法,以建立比较基础。这包括五种既有方法:LoCoMo(Maharana et al., 2024)、ReadAgent(Lee et al., 2024)、MemoryBank(Zhong et al., 2024)、MemGPT(Packer et al., 2023)与 A-Mem(Xu et al., 2025)。这些既有基准不仅提供了与已发表结果的直接比较点,也代表了不同算法范式下对话记忆架构的演进。在我们的评估中,我们选取以 gpt-4o-mini 进行评估的指标。关于这些基准的更多细节见附录 C。
Open-Source Memory Solutions Our second category consists of promising open-source memory architectures such as LangMem (Hot Path) that have demonstrated effectiveness in related conversational tasks but have not yet been evaluated on the LOCOMO dataset. By adapting these systems to our evaluation framework, we broaden the comparative landscape and identify potential alternative approaches that may offer competitive performance. We initialized the LLM with gpt-4o-mini and used text-embedding-small-3 as the embedding model.
开源记忆方案。第二类由有前景的开源记忆架构组成,如 LangMem(Hot Path),它们在相关对话任务中已展现有效性,但尚未在 LOCOMO 数据集上被评估过。通过将这些系统适配到我们的评估框架,我们拓宽了比较视野,并识别出可能提供有竞争力性能的备选方案。我们用 gpt-4o-mini 初始化 LLM,并使用 text-embedding-small-3 作为嵌入模型。
Retrieval-Augmented Generation (RAG) As a baseline, we treat the entire conversation history as a document collection and apply a standard RAG pipeline. We first segment each conversation into fixed-length chunks (128, 256, 512, 1024, 2048, 4096, and 8192 tokens), where 8192 is the maximum chunk size supported by our embedding model. All chunks are embedded using OpenAI's text-embedding-small-3 to ensure consistent vector quality across configurations. At query time, we retrieve the top k chunks by semantic similarity and concatenate them as context for answer generation. Throughout our experiments we set k∈{1,2}: with k=1 only the single most relevant chunk is used, and with k=2 the two most relevant chunks (up to 16384 tokens) are concatenated. We avoid k>2 since the average conversation length (26000 tokens) would be fully covered, negating the benefits of selective retrieval. By varying chunk size and k, we systematically evaluate RAG performance on long-term conversational memory tasks.
检索增强生成(RAG)。作为基线,我们把整段对话历史当作文档集,应用标准 RAG 流水线。我们首先把每段对话切分为固定长度的文本块(128、256、512、1024、2048、4096、8192 token),其中 8192 是我们嵌入模型支持的最大分块大小。所有文本块均用 OpenAI 的 text-embedding-small-3 嵌入,以确保各配置间向量质量一致。查询时,我们按语义相似度检索 top-k 文本块并拼接作为答案生成的上下文。整个实验中我们设 k∈{1,2}:k=1 时只用最相关的一个文本块;k=2 时拼接最相关的两个文本块(最多 16,384 token)。我们避免 k>2,因为平均对话长度(26,000 token)会被完全覆盖,从而失去选择性检索的意义。通过改变分块大小与 k,我们系统地评估 RAG 在长期对话记忆任务上的表现。
Full-Context Processing We adopt a straightforward approach by passing the entire conversation history within the context window of the LLM. This method leverages the model's inherent ability to process sequential information without additional architectural components. While conceptually simple, this approach faces practical limitations as conversation length increases, eventually increasing token cost and latency. Nevertheless, it establishes an important reference point for understanding the value of more sophisticated memory mechanisms compared to direct processing of available context.
全上下文处理。我们采用一种直接的方法:把整段对话历史放进 LLM 的上下文窗口。该方法利用模型固有的顺序信息处理能力,无需额外架构组件。虽然概念上简单,但随着对话变长,该方法面临实际局限,最终导致 token 成本与延迟上升。尽管如此,它为理解"直接处理可用上下文"与"更精细记忆机制的价值"之间的对比提供了一个重要参照点。
Proprietary Models We evaluate OpenAI's memory feature available in their ChatGPT interface, specifically using gpt-4o-mini for consistency. We ingest entire LOCOMO conversations with a prompt (see Appendix A) into single chat sessions, prompting memory generation with timestamps, participant names, and conversation text. These generated memories are then used as complete context for answering questions about each conversation, intentionally granting the OpenAI approach privileged access to all memories rather than only question-relevant ones. This methodology accommodates the lack of external API access for selective memory retrieval in OpenAI's system for benchmarking.
专有模型。我们评估 OpenAI 在其 ChatGPT 界面中提供的记忆功能,具体使用 gpt-4o-mini 以保持一致。我们用一段提示(见附录 A)把整段 LOCOMO 对话摄入单一聊天会话,提示其带时间戳、参与者姓名与对话文本地生成记忆。随后,这些生成的记忆被用作回答每段对话相关问题的完整上下文——这是有意为之,让 OpenAI 方案拥有对所有记忆的特权访问,而非仅限与问题相关的记忆。这一做法是为了迁就 OpenAI 系统缺少用于选择性记忆检索的外部 API 访问这一基准评测上的限制。
Memory Providers We incorporate Zep (Rasmussen et al., 2025), a memory management platform designed for AI agents. Using their platform version, we conduct systematic evaluations across the LOCOMO dataset, maintaining temporal fidelity by preserving timestamp information alongside conversational content. This temporal anchoring ensures that time-sensitive queries can be addressed through appropriately contextualized memory retrieval, particularly important for evaluating questions that require chronological awareness. This baseline represents an important commercial implementation of memory management specifically engineered for AI agents.
记忆提供商。我们纳入 Zep(Rasmussen et al., 2025),一个为 AI Agent 设计的记忆管理平台。我们使用其平台版本,在 LOCOMO 数据集上进行系统评估,通过在对话内容旁保留时间戳信息来维持时序保真度。这种时间锚定确保时间敏感的查询能通过恰当语境化的记忆检索来回答,这对评估需要时序意识的问题尤为重要。该基线代表了专为 AI Agent 打造的记忆管理方案的一次重要商业化实现。
4 评估结果、分析与讨论
4.1 各记忆系统的性能比较
Table 1 reports F1, B1 and J scores for our two architectures—Mem0 and Mem0g—against a suite of competitive baselines, as mentioned in Section 3, on single-hop, multi-hop, open-domain, and temporal questions. Overall, both of our models set new state-of-the-art marks in all the three evaluation metrics for most question types.
表 1 报告了我们的两个架构——Mem0 与 Mem0g——对照第 3 节所述一系列有竞争力的基线,在单跳、多跳、开放域与时序问题上的 F1、B1 与 J 分数。总体而言,我们的两个模型在多数问题类型上以全部三项评估指标刷新了当时的最佳水平。
表 1:各记忆系统在 LOCOMO 数据集上不同问题类型的性能比较。评估指标为 F1 分数(F1)、BLEU-1(B1)与 LLM-as-a-Judge 分数(J),值越高越好。A-Mem* 表示我们对 A-Mem 的重跑结果(温度设为 0)以生成 LLM-as-a-Judge 分数。Mem0g 表示带图记忆增强的所提架构。粗体表示各指标在所有方法中的最佳表现。(↑) 表示分数越高越好。
| 方法 | 单跳 F1↑ | 单跳 B1↑ | 单跳 J↑ | 多跳 F1↑ | 多跳 B1↑ | 多跳 J↑ | 开放域 F1↑ | 开放域 B1↑ | 开放域 J↑ | 时序 F1↑ | 时序 B1↑ | 时序 J↑ |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| LoCoMo | 25.02 | 19.75 | – | 12.04 | 11.16 | – | 40.36 | 29.05 | – | 18.41 | 14.77 | – |
| ReadAgent | 9.15 | 6.48 | – | 5.31 | 5.12 | – | 9.67 | 7.66 | – | 12.60 | 8.87 | – |
| MemoryBank | 5.00 | 4.77 | – | 5.56 | 5.94 | – | 6.61 | 5.16 | – | 9.68 | 6.99 | – |
| MemGPT | 26.65 | 17.72 | – | 9.15 | 7.44 | – | 41.04 | 34.34 | – | 25.52 | 19.44 | – |
| A-Mem | 27.02 | 20.09 | – | 12.14 | 12.00 | – | 44.65 | 37.06 | – | 45.85 | 36.67 | – |
| A-Mem* | 20.76 | 14.90 | 39.79 ± 0.38 | 9.22 | 8.81 | 18.85 ± 0.31 | 33.34 | 27.58 | 54.05 ± 0.22 | 35.40 | 31.08 | 49.91 ± 0.31 |
| LangMem | 35.51 | 26.86 | 62.23 ± 0.75 | 26.04 | 22.32 | 47.92 ± 0.47 | 40.91 | 33.63 | 71.12 ± 0.20 | 30.75 | 25.84 | 23.43 ± 0.39 |
| Zep | 35.74 | 23.30 | 61.70 ± 0.32 | 19.37 | 14.82 | 41.35 ± 0.48 | 49.56 | 38.92 | 76.60 ± 0.13 | 42.00 | 34.53 | 49.31 ± 0.50 |
| OpenAI | 34.30 | 23.72 | 63.79 ± 0.46 | 20.09 | 15.42 | 42.92 ± 0.63 | 39.31 | 31.16 | 62.29 ± 0.12 | 14.04 | 11.25 | 21.71 ± 0.20 |
| Mem0 | 38.72 | 27.13 | 67.13 ± 0.65 | 28.64 | 21.58 | 51.15 ± 0.31 | 47.65 | 38.72 | 72.93 ± 0.11 | 48.93 | 40.51 | 55.51 ± 0.34 |
| Mem0g | 38.09 | 26.03 | 65.71 ± 0.45 | 24.32 | 18.82 | 47.19 ± 0.67 | 49.27 | 40.30 | 75.71 ± 0.21 | 51.55 | 40.28 | 58.13 ± 0.44 |
Single-Hop Question Performance Single-hop queries involve locating a single factual span contained within one dialogue turn. Leveraging its dense memories in natural language text, Mem0 secures the strongest results: F1=38.72, B1=27.13, and J=67.13. Augmenting the natural language memories with graph memory (Mem0g) yields marginal performance drop compared to Mem0, indicating that relational structure provides limited utility when the retrieval target occupies a single turn. Among the existing baselines, the full-context OpenAI run attains the next-best J score, reflecting the benefits of retaining the entire conversation in context, while LangMem and Zep both score around 8% relatively less against our models on J score. Previous LOCOMO benchmarks such as A-mem lag by more than 25 points in J, underscoring the necessity of fine-grained, structured memory indexing even for simple retrieval tasks.
单跳问题表现。单跳查询需要在单轮对话中定位单一事实片段。凭借自然语言文本形式的稠密记忆,Mem0 取得最强结果:F1=38.72、B1=27.13、J=67.13。在自然语言记忆之上叠加图记忆(Mem0g)相比 Mem0 出现轻微性能下降,说明当检索目标只占单轮时,关系结构提供的收益有限。在既有基线中,全上下文的 OpenAI 运行取得次优的 J 分,反映出把整段对话保留在上下文中的好处;而 LangMem 与 Zep 的 J 分都比我们的模型相对低约 8%。此前的 LOCOMO 基准(如 A-Mem)在 J 上落后超过 25 分,凸显出即便是简单检索任务也需要细粒度、结构化的记忆索引。
Multi-Hop Question Performance Multi-hop queries require synthesizing information dispersed across multiple conversation sessions, posing significant challenges in memory integration and retrieval. Mem0 clearly outperforms other methods with an F1 score of 28.64 and a J score of 51.15, reflecting its capability to efficiently retrieve and integrate disparate information stored across sessions. Interestingly, the addition of graph memory in Mem0g does not provide performance gains here, indicating potential inefficiencies or redundancies in structured graph representations for complex integrative tasks compared to dense natural language memory alone. Baselines like LangMem show competitive performances, but their scores substantially trail those of Mem0, emphasizing the advantage of our refined memory indexing and retrieval mechanisms for complex query processing.
多跳问题表现。多跳查询需要综合分散在多个对话会话中的信息,对记忆整合与检索构成重大挑战。Mem0 以 F1=28.64、J=51.15 明显优于其他方法,反映出其高效检索与整合跨会话分散存储信息的能力。有趣的是,在 Mem0g 中加入图记忆并未在此带来性能提升,说明相对于单纯的稠密自然语言记忆,结构化图表示在复杂整合任务中可能存在低效或冗余。LangMem 等基线表现尚可,但其分数大幅落后于 Mem0,凸显了我们精细的记忆索引与检索机制在复杂查询处理上的优势。
Open-Domain Performance In open-domain settings, the baseline Zep achieves the highest F1 (49.56) and J (76.60) scores, edging out our methods by a narrow margin. In particular, Zep's J score of 76.60 surpasses Mem0g's 75.71 by just 0.89 percentage points and outperforms Mem0's 72.93 by 3.67 points, highlighting a consistent, if slight, advantage in integrating conversational memory with external knowledge. Mem0g remains a strong runner-up, with a J of 75.71 reflecting high factual retrieval precision, while Mem0 follows with 72.93, demonstrating robust coherence. These results underscore that although structured relational memories (as in Mem0 and Mem0g) substantially improve open-domain retrieval, Zep maintains a small but meaningful lead.
开放域表现。在开放域设定下,基线 Zep 取得最高 F1(49.56)与 J(76.60),以微弱优势险胜我们的方法。具体而言,Zep 的 J 分 76.60 仅比 Mem0g 的 75.71 高 0.89 个百分点,比 Mem0 的 72.93 高 3.67 分,显示出其在整合对话记忆与外部知识方面一致(尽管幅度不大)的优势。Mem0g 仍是强劲的亚军,J 为 75.71,体现高事实检索精度;Mem0 以 72.93 紧随其后,展现稳健的连贯性。这些结果强调:尽管结构化关系记忆(Mem0 与 Mem0g 中的形式)已大幅改进开放域检索,Zep 仍保持小幅但有意义的领先。
Temporal Reasoning Performance Temporal reasoning tasks hinge on accurate modeling of event sequences, their relative ordering, and durations within conversational history. Our architectures demonstrate substantial improvements across all metrics, with Mem0g achieving the highest F1 (51.55) and J (58.13), suggesting that structured relational representations in addition to natural language memories significantly aid in temporally grounded judgments. Notably, the base variant, Mem0, also provide a decent J score (55.51), suggesting that natural language alone can aid in temporally grounded judgments. Among baselines, OpenAI notably underperforms, with scores below 15%, primarily due to missing timestamps in most generated memories despite explicit prompting in the OpenAI ChatGPT to extract memories with timestamps. Other baselines such as A-Mem achieve respectable results, yet our models clearly advance the state-of-the-art, emphasizing the critical advantage of accurately leveraging both natural language contextualization and structured graph representations for temporal reasoning.
时序推理表现。时序推理任务的关键在于对对话历史中事件序列、其相对次序与时长的准确建模。我们的架构在所有指标上均有大幅改进,其中 Mem0g 取得最高 F1(51.55)与 J(58.13),表明在自然语言记忆之外引入结构化关系表示,能显著帮助基于时间的判断。值得注意的是,基础变体 Mem0 也提供了不错的 J 分(55.51),说明单凭自然语言也能辅助基于时间的判断。在基线中,OpenAI 明显失准,分数低于 15%,主要原因是尽管在 OpenAI ChatGPT 中明确提示抽取带时间戳的记忆,其生成的多数记忆仍缺少时间戳。A-Mem 等其他基线取得了尚可的结果,但我们的模型显然推进了最佳水平,凸显了同时准确利用自然语言语境化与结构化图表示对时序推理的关键优势。
4.2 跨类别分析
The comprehensive evaluation across diverse question categories reveals that our proposed architectures, Mem0 and Mem0g, consistently achieve superior performance compared to baseline systems. For single-hop queries, Mem0 demonstrates particularly strong performance, benefiting from its efficient dense natural language memory structure. Although graph-based representations in Mem0g slightly lag behind in lexical overlap metrics for these simpler queries, they significantly enhance semantic coherence, as demonstrated by competitive J scores. This indicates that graph structures are more beneficial in scenarios involving nuanced relational context rather than straightforward retrieval. For multi-hop questions, Mem0 exhibits clear advantages by effectively synthesizing dispersed information across multiple sessions, confirming that natural language memories provide sufficient representational richness for these integrative tasks. Surprisingly, the expected relational advantages of Mem0g do not translate into better outcomes here, suggesting potential overhead or redundancy when navigating more intricate graph structures in multi-step reasoning scenarios.
跨越多样问题类别的全面评估表明,我们提出的架构 Mem0 与 Mem0g 相比基线系统持续取得更优表现。对单跳查询,Mem0 表现尤为强劲,受益于其高效的稠密自然语言记忆结构。尽管 Mem0g 的图表示在这类较简单查询的词法重叠指标上略有落后,但它们显著增强了语义连贯性(体现为有竞争力的 J 分)。这表明图结构在涉及细致关系语境的场景中更有裨益,而非直截了当的检索。对多跳问题,Mem0 通过有效综合分散在多个会话中的信息展现明显优势,证实自然语言记忆为此类整合任务提供了足够的表示丰富度。出乎意料的是,Mem0g 预期的关系优势并未在此转化为更好的结果,提示在多步推理场景中导航更复杂的图结构可能带来开销或冗余。
表 2:各基线与所提方法的性能比较。延迟测量给出检索时间(取回记忆/文本块的时间)与总时间(生成完整回复的时间)的 p50(中位数)与 p95(第 95 百分位)值,单位为秒。总体 LLM-as-a-Judge 分数(J)表示在整个 LOCOMO 数据集上生成回复的质量指标。
| 方法 | k | 分块大小/记忆 token | 检索 p50 | 检索 p95 | 总计 p50 | 总计 p95 | 总体 J |
|---|---|---|---|---|---|---|---|
| RAG | 1 | 128 | 0.281 | 0.823 | 0.774 | 1.825 | 47.77 ± 0.23% |
| 256 | 0.251 | 0.710 | 0.745 | 1.628 | 50.15 ± 0.16% | ||
| 512 | 0.240 | 0.639 | 0.772 | 1.710 | 46.05 ± 0.14% | ||
| 1024 | 0.240 | 0.723 | 0.821 | 1.957 | 40.74 ± 0.17% | ||
| 2048 | 0.255 | 0.752 | 0.996 | 2.182 | 37.93 ± 0.12% | ||
| 4096 | 0.254 | 0.719 | 1.093 | 2.711 | 36.84 ± 0.17% | ||
| 8192 | 0.279 | 0.838 | 1.396 | 4.416 | 44.53 ± 0.13% | ||
| 2 | 128 | 0.267 | 0.624 | 0.766 | 1.829 | 59.56 ± 0.19% | |
| 256 | 0.255 | 0.699 | 0.802 | 1.907 | 60.97 ± 0.20% | ||
| 512 | 0.247 | 0.746 | 0.829 | 1.729 | 58.19 ± 0.18% | ||
| 1024 | 0.238 | 0.702 | 0.860 | 1.850 | 50.68 ± 0.13% | ||
| 2048 | 0.261 | 0.829 | 1.101 | 2.791 | 48.57 ± 0.22% | ||
| 4096 | 0.266 | 0.944 | 1.451 | 4.822 | 51.79 ± 0.15% | ||
| 8192 | 0.288 | 1.124 | 2.312 | 9.942 | 60.53 ± 0.16% | ||
| Full-context | – | 26031 | – | – | 9.870 | 17.117 | 72.90 ± 0.19% |
| A-Mem | – | 2520 | 0.668 | 1.485 | 1.410 | 4.374 | 48.38 ± 0.15% |
| LangMem | – | 127 | 17.99 | 59.82 | 18.53 | 60.40 | 58.10 ± 0.21% |
| Zep | – | 3911 | 0.513 | 0.778 | 1.292 | 2.926 | 65.99 ± 0.16% |
| OpenAI | – | 4437 | – | – | 0.466 | 0.889 | 52.90 ± 0.14% |
| Mem0 | – | 1764 | 0.148 | 0.200 | 0.708 | 1.440 | 66.88 ± 0.15% |
| Mem0g | – | 3616 | 0.476 | 0.657 | 1.091 | 2.590 | 68.44 ± 0.17% |
In temporal reasoning, Mem0g substantially outperforms other methods, validating that structured relational graphs excel in capturing chronological relationships and event sequences. The presence of explicit relational context significantly enhances Mem0g's temporal coherence, outperforming Mem0's dense memory storage and highlighting the importance of precise relational representations when tracking temporally sensitive information. Open-domain performance further reinforces the value of relational modeling. Mem0g, benefiting from the relational clarity of graph-based memory, closely competes with the top-performing baseline (Zep). This competitive result underscores Mem0g's robustness in integrating external knowledge through relational clarity, suggesting an optimal synergy between structured memory and open-domain information synthesis.
在时序推理中,Mem0g 大幅超越其他方法,验证了结构化关系图在捕捉时间先后关系与事件序列方面的长处。显式关系语境的存在显著增强了 Mem0g 的时序连贯性,胜过 Mem0 的稠密记忆存储,凸显了追踪时间敏感信息时精确关系表示的重要性。开放域表现进一步印证了关系建模的价值:得益于图记忆的关系清晰度,Mem0g 与表现最佳的基线(Zep)激烈竞争。这一有竞争力的结果凸显了 Mem0g 通过关系清晰度整合外部知识的稳健性,提示结构化记忆与开放域信息综合之间存在最佳协同。
[图 4: (a) Comparison of search latency at p50 (median) and p95 (95th percentile) across different memory methods (Mem0, Mem0g, best RAG variant, Zep, LangMem, and A-Mem). The bar heights represent J scores (left axis), while the line plots show search latency in seconds (right axis scaled in log). (b) Comparison of total response latency at p50 and p95 across different memory methods (Mem0, Mem0g, best RAG variant, Zep, LangMem, OpenAI, full-context, and A-Mem). The bar heights represent J scores (left axis), and the line plots capture end-to-end latency in seconds (right axis scaled in log). — Figure 4: Latency Analysis of Different Memory Approaches. These subfigures illustrate the J scores and latency comparison of various selected methods from Table 2. Subfigure (a) highlights the search/retrieval latency prior to answer generation, while subfigure (b) shows the total latency (including LLM inference). Both plots overlay each method's J score for a holistic view of their accuracy and efficiency.]
图 4 说明:不同记忆方法的延迟分析,展示表 2 中所选方法的 J 分与延迟对比。子图 (a):答案生成之前的检索/检索延迟——比较各记忆方法(Mem0、Mem0g、最佳 RAG 变体、Zep、LangMem、A-Mem)在 p50(中位数)与 p95(第 95 百分位)的检索延迟,柱高为 J 分(左轴),折线为检索延迟秒数(右轴,对数刻度)。子图 (b):端到端总延迟(含 LLM 推理,另含 OpenAI 与全上下文)——柱高为 J 分(左轴),折线为总延迟秒数(右轴,对数刻度)。两幅图均叠加各方法的 J 分,以便整体审视其准确率与效率。
Overall, our analysis indicates complementary strengths of Mem0 and Mem0g across various task demands: dense, natural-language-based memory offers significant efficiency for simpler queries, while explicit relational modeling becomes essential for tasks demanding nuanced temporal and contextual integration. These findings reinforce the importance of adaptable memory structures tailored to specific reasoning contexts in AI agent deployments.
总体而言,我们的分析表明 Mem0 与 Mem0g 在不同任务需求下各具互补优势:稠密的自然语言记忆对较简单查询有显著的效率优势,而显式关系建模对需要细致时序与上下文整合的任务必不可少。这些发现强化了在 AI Agent 部署中采用与特定推理语境相匹配、可灵活调整的记忆结构的重要性。
4.3 Mem0 与 Mem0g 对比 RAG 方法与全上下文模型
Comparisons in Table 2, focusing on the 'Overall J' column, reveal that both Mem0 and Mem0g consistently outperform all RAG configurations, which vary chunk sizes (128–8192 tokens) and retrieve either one (k=1) or two (k=2) chunks. Even the strongest RAG approach peaks at around 61% in the J metric, whereas Mem0 reaches 67%—about a 10% relative improvement—and Mem0g reaches over 68%, achieving around a 12% relative gain. These advances underscore the advantage of capturing only the most salient facts in memory, rather than retrieving large chunk of original text. By converting the conversation history into concise, structured representations, Mem0 and Mem0g mitigate noise and surface more precise cues to the LLM, leading to better answers as evaluated by an external LLM (J).
聚焦表 2 的"Overall J"列可以看到,Mem0 与 Mem0g 一致地超越所有 RAG 配置(分块大小 128–8192 token、检索 k=1 或 k=2 个文本块)。即使最强的 RAG 方法在 J 指标上也只达到约 61%,而 Mem0 达到 67%——约 10% 的相对提升——Mem0g 超过 68%,取得约 12% 的相对增益。这些进展凸显了"只把最显著的事实存入记忆"而非"检索大段原始文本"的优势。通过把对话历史转化为简洁的结构化表示,Mem0 与 Mem0g 降低了噪声、向 LLM 呈现更精确的线索,从而在外部 LLM(J)的评估下产生更好的回答。
Despite these improvements, a full-context method that ingests a chunk of roughly 26,000 tokens still achieves the highest J score (approximately 73%). However, as shown in Figure 4b, it also incurs a very high total p95 latency—around 17 seconds—since the model must read the entire conversation on every query. By contrast, Mem0 and Mem0g significantly reduce token usage and thus achieve lower p95 latencies of around 1.44 seconds (a 92% reduction) and 2.6 seconds (a 85% reduction), respectively over full-context approach. Although the full-context approach can provide a slight accuracy edge, the memory-based systems offer a more practical trade-off, maintaining near-competitive quality while imposing only a fraction of the token and latency cost. As conversation length increases, full-context approaches suffer from exponential growth in computational overhead (evident in Table 2 where total p95 latency increases significantly with larger k values or chunk sizes). This increase in input chunks leads to longer response times and higher token consumption costs. In contrast, memory-focused approaches like Mem0 and Mem0g maintain consistent performance regardless of conversation length, making them substantially more viable for production-scale deployments where efficiency and responsiveness are critical.
尽管有这些改进,摄入约 26,000 token 上下文的全上下文方法仍取得最高 J 分(约 73%)。然而如图 4b 所示,它也带来极高的总 p95 延迟——约 17 秒——因为模型必须在每次查询时读完整段对话。相比之下,Mem0 与 Mem0g 显著降低了 token 用量,从而将 p95 总延迟相对全上下文方法分别降至约 1.44 秒(降低 92%)与 2.6 秒(降低 85%)。尽管全上下文方法可以带来少许准确率优势,记忆型系统提供了更实用的权衡:在只付出零头 token 与延迟成本的同时保持接近的竞争力。随着对话变长,全上下文方法的计算开销呈指数式增长(表 2 中可见总 p95 延迟随 k 值或分块大小增大而显著上升)。输入文本块的增加导致响应时间更长、token 消耗成本更高。相比之下,Mem0 与 Mem0g 等聚焦记忆的方法无论对话多长都保持稳定表现,使其对于效率与响应速度至关重要的生产级部署而言可行得多。
4.4 延迟分析
Table 2 provides a comprehensive performance comparison of various retrieval and memory methodologies, presenting median (p50) and tail (p95) latencies for both the search phase and total response generation across the LOCOMO dataset. Our analysis reveals distinct performance patterns governed by architectural choices. Memory-centric architectures demonstrate different performance characteristics. A-Mem, despite its larger memory store, incurs substantial search overhead (p50: 0.668s), resulting in total median latencies of 1.410s. LangMem exhibits even higher search latencies (p50: 17.99s, p95: 59.82s), rendering it impractical for interactive applications. Zep achieves moderate performance (p50 total: 1.292s). The full-context baseline, which processes the entire conversation history without retrieval, fundamentally differs from retrieval-based approaches. By passing the entire conversation context (26000 tokens) directly to the LLM, it eliminates search overhead but incurs extreme total latencies (p50: 9.870s, p95: 17.117s). Similarly, the OpenAI implementation does not perform memory search, as it processes manually extracted memories from their playground. While this approach achieves impressive response generation times (p50: 0.466s, p95: 0.889s), it requires pre-extraction of relevant context, which is not reflected in the reported metrics.
表 2 对多种检索与记忆方法进行了全面的性能比较,给出 LOCOMO 数据集上检索阶段与总回复生成的中位数(p50)与尾部(p95)延迟。我们的分析揭示了由架构选择主导的多种性能模式。以记忆为中心的架构表现出各不相同的性能特征:A-Mem 尽管记忆库更大,却产生了可观的检索开销(p50:0.668s),导致总中位延迟达 1.410s;LangMem 的检索延迟更高(p50:17.99s、p95:59.82s),使其对交互式应用不切实际;Zep 取得中等表现(总 p50:1.292s)。全上下文基线不进行检索、直接处理整段对话历史,与基于检索的方法根本不同:它把整个对话上下文(26,000 token)直接传给 LLM,消除了检索开销,但总延迟极端(p50:9.870s、p95:17.117s)。类似地,OpenAI 实现不做记忆检索,因为它处理的是从其 playground 手动抽取的记忆。虽然该方法的回复生成时间令人印象深刻(p50:0.466s、p95:0.889s),但它需要预先抽取相关上下文,而这部分成本未反映在报告的指标中。
Our proposed Mem0 approach achieves the lowest search latency among all methods (p50: 0.148s, p95: 0.200s) as illustrated in Figure 4a. This efficiency stems from our selective memory retrieval mechanism and infra improvements that dynamically identifies and retrieves only the most salient information rather than fixed-size chunks. Consequently, Mem0 maintains the lowest total median latency (0.708s) with remarkably contained p95 values (1.440s), making it particularly suitable for latency-sensitive applications such as interactive AI agents. The graph-enhanced Mem0g variant introduces additional relational modeling capabilities at a moderate latency cost, with search times (0.476s) still outperforming all existing memory solutions and baselines. Despite this increase, Mem0g maintains competitive total latencies (p50: 1.091s, p95: 2.590s) while achieving the highest J score (68.44%) across all methods—trailing only the computationally prohibitive full-context approach. This performance profile demonstrates our methods' ability to balance response quality and computational efficiency, offering a compelling solution for production AI agents where both factors are critical constraints.
如图 4a 所示,我们提出的 Mem0 在所有方法中取得最低的检索延迟(p50:0.148s、p95:0.200s)。这一效率源于我们的选择性记忆检索机制与基础设施改进——动态地只识别并检索最显著的信息,而非固定大小的文本块。因此,Mem0 保持最低的总中位延迟(0.708s),且 p95 值也控制在很低的水平(1.440s),使其特别适合延迟敏感的应用,例如交互式 AI Agent。图增强的 Mem0g 变体以适中的延迟代价引入额外的关系建模能力,其检索时间(0.476s)仍优于所有既有记忆方案与基线。尽管有所上升,Mem0g 保持有竞争力的总延迟(p50:1.091s、p95:2.590s),同时取得所有方法中最高的 J 分(68.44%)——仅次于计算上令人望而却步的全上下文方法。这一性能画像展示了我们的方法平衡回复质量与计算效率的能力,为质量与效率双约束都很关键的生产级 AI Agent 提供了有说服力的方案。
4.5 记忆系统开销:Token 分析与构建时间
We measure the average token budget required to materialise each system's long-term memory store. Mem0 encodes complete dialogue turns in a natural language representation and therefore occupies only 7k tokens per conversation on an average. Where as Mem0g roughly doubles the footprint to 14k tokens, due to the introduction of graph memories which includes nodes and corresponding relationships. In stark contrast, Zep's memory graph consumes in excess of 600k tokens. The inflation arises from Zep's design choice to cache a full abstractive summary at every node while also storing facts on the connecting edges, leading to extensive redundancy across the graph. For perspective, supplying the entire raw conversation context to the language model—without any memory abstraction—amounts to roughly 26k tokens on average, 20 times less relative to Zep's graph. Beyond token inefficiency, our experiments revealed significant operational bottlenecks with Zep. After adding memories to Zep's system, we observed that immediate memory retrieval attempts often failed to answer our queries correctly. Interestingly, re-running identical searches after a delay of several hours yielded considerably better results. This latency suggests that Zep's graph construction involves multiple asynchronous LLM calls and extensive background processing, making the memory system impractical for real-time applications. In contrast, Mem0 graph construction completes in under a minute even in worst-case scenarios, allowing users to immediately leverage newly added memories for query responses.
我们测量物化各系统长期记忆库所需的平均 token 预算。Mem0 以自然语言表示编码完整的对话轮,因此平均每段对话只占约 7k token;而 Mem0g 由于引入图记忆(含节点及相应关系),占用大致翻倍至 14k token。与之形成鲜明对比的是,Zep 的记忆图消耗超过 600k token。这种膨胀源于 Zep 的设计选择:在每个节点缓存一份完整的抽象摘要,同时又在连接边上存储事实,导致图内大范围冗余。作为参照,把整段原始对话上下文(不做任何记忆抽象)直接提供给语言模型,平均也只需约 26k token——相对 Zep 的图少 20 倍。除 token 低效外,我们的实验还揭示了 Zep 的显著运营瓶颈:向 Zep 系统添加记忆后,我们观察到立即尝试记忆检索常常无法正确回答查询;有趣的是,延迟数小时后重新运行相同的搜索会好得多。这一延迟表明,Zep 的图构建涉及多次异步 LLM 调用与大量后台处理,使其记忆系统不适合实时应用。相比之下,Mem0 的图构建即使在最坏情况下也能在一分钟内完成,允许用户立即利用新添加的记忆进行查询应答。
These findings highlight that Zep not only replicates identical knowledge fragments across multiple nodes, but also introduces significant operational delays. Our architectures—Mem0 and Mem0g—preserve the same information at a fraction of the token cost and with substantially faster memory availability, offering a more memory-efficient and operationally responsive representation.
这些发现凸显出,Zep 不仅在多个节点间复制了相同的知识碎片,还引入了显著的运营延迟。我们的架构——Mem0 与 Mem0g——以零头的 token 成本与快得多的记忆可用性保存同样的信息,提供了更省记忆、运营上更敏捷的表示。
5 结论与未来工作
We have introduced Mem0 and Mem0g, two complementary memory architectures that overcome the intrinsic limitations of fixed context windows in LLMs. By dynamically extracting, consolidating, and retrieving compact memory representations, Mem0 achieves state-of-the-art performance across single-hop and multi-hop reasoning, while Mem0g's graph-based extensions unlock significant gains in temporal and open-domain tasks. On the LOCOMO benchmark, our methods deliver 5%, 11%, and 7% relative improvements in single-hop, temporal, and multi-hop reasoning question types over best performing methods in respective question type and reduce p95 latency by over 91% compared to full-context baselines—demonstrating a powerful balance between precision and responsiveness. Mem0's dense memory pipeline excels at rapid retrieval for straightforward queries, minimizing token usage and computational overhead. In contrast, Mem0g's structured graph representations provide nuanced relational clarity, enabling complex event sequencing and rich context integration without sacrificing practical efficiency. Together, they form a versatile memory toolkit that adapts to diverse conversational demands while remaining deployable at scale.
我们提出了 Mem0 与 Mem0g,两个互补的记忆架构,克服了 LLM 固定上下文窗口的内在局限。通过动态抽取、整合并检索紧凑记忆表示,Mem0 在单跳与多跳推理上取得最佳表现,而 Mem0g 的图扩展在时序与开放域任务上解锁了显著收益。在 LOCOMO 基准上,我们的方法在单跳、时序与多跳推理题型上分别相对各自题型中表现最佳的方法取得 5%、11% 与 7% 的相对提升,并将 p95 延迟相对全上下文基线降低逾 91%——展示了精确性与响应性之间的有力平衡。Mem0 的稠密记忆流水线擅长对简单查询的快速检索,最小化 token 使用与计算开销;相比之下,Mem0g 的结构化图表示提供细致的关系清晰度,支持复杂事件排序与丰富上下文整合而不牺牲实际效率。二者共同构成一个多功能的记忆工具箱,既能适应多样的对话需求,又可规模化部署。
Future research directions include optimizing graph operations to reduce the latency overhead in Mem0g, exploring hierarchical memory architectures that blend efficiency with relational representation, and developing more sophisticated memory consolidation mechanisms inspired by human cognitive processes. Additionally, extending our memory frameworks to domains beyond conversational scenarios, such as procedural reasoning and multimodal interactions, would further validate their broader applicability. By addressing the fundamental limitations of fixed context windows, our work represents a significant advancement toward conversational AI systems capable of maintaining coherent, contextually rich interactions over extended periods, much like their human counterparts.
未来的研究方向包括:优化图操作以降低 Mem0g 的延迟开销;探索兼顾效率与关系表示的分层记忆架构;以及发展受人类认知过程启发、更精细的记忆巩固机制。此外,把我们的记忆框架扩展到对话场景之外的领域,如程序性推理(procedural reasoning)与多模态交互,将进一步验证其更广泛的适用性。通过解决固定上下文窗口的根本局限,我们的工作代表了向"能够像人类一样在较长时间内保持连贯、语境丰富交互的对话式 AI 系统"迈出的重要一步。
6 致谢
We would like to express our sincere gratitude to Harsh Agarwal, Shyamal Anadkat, Prithvijit Chattopadhyay, Siddesh Choudhary, Rishabh Jain, and Vaibhav Pandey for their invaluable insights and thorough reviews of early drafts. Their constructive comments and detailed suggestions helped refine the manuscript, enhancing both its clarity and overall quality. We deeply appreciate their generosity in dedicating time and expertise to this work.
我们谨向 Harsh Agarwal、Shyamal Anadkat、Prithvijit Chattopadhyay、Siddesh Choudhary、Rishabh Jain 与 Vaibhav Pandey 致以诚挚谢意,感谢他们对早期草稿的宝贵见解与细致评审。他们建设性的意见与详尽的建议帮助打磨了手稿,提升了其清晰度与整体质量。我们深深感谢他们为这项工作慷慨投入的时间与专业知识。
附录 A:提示词
In developing our LLM-as-a-Judge prompt, we adapt elements from the prompt released by Packer et al. (2023).
在开发我们的 LLM-as-a-Judge 提示词时,我们改编了 Packer et al. (2023) 发布的提示词中的部分元素。
A.1 LLM-as-a-Judge 提示词模板(原样保留,注释为译注)
Prompt Template for LLM as a Judge

Your task is to label an answer to a question as "CORRECT" or "WRONG". You will be given
the following data: (1) a question (posed by one user to another user), (2) a 'gold'
(ground truth) answer, (3) a generated answer which you will score as CORRECT/WRONG.
The point of the question is to ask about something one user should know about the other
user based on their prior conversations. The gold answer will usually be a concise and
short answer that includes the referenced topic, for example:
Question: Do you remember what I got the last time I went to Hawaii?
Gold answer: A shell necklace
The generated answer might be much longer, but you should be generous with your grading
- as long as it touches on the same topic as the gold answer, it should be counted as
CORRECT.
For time related questions, the gold answer will be a specific date, month, year, etc. The
generated answer might be much longer or use relative time references (like 'last Tuesday'
or 'next month'), but you should be generous with your grading - as long as it refers to
the same date or time period as the gold answer, it should be counted as CORRECT. Even if
the format differs (e.g., 'May 7th' vs '7 May'), consider it CORRECT if it's the same date.
Now it's time for the real question:
Question: {question}
Gold answer: {gold_answer}
Generated answer: {generated_answer}
First, provide a short (one sentence) explanation of your reasoning, then finish with
CORRECT or WRONG. Do NOT include both CORRECT and WRONG in your response, or it will break
the evaluation script.
Just return the label CORRECT or WRONG in a json format with the key as "label".
译注:该模板要求裁判 LLM 把生成的答案标记为 CORRECT 或 WRONG,输入为问题、金标准(gold)答案与生成答案三部分。评分从宽:只要生成答案触及金标准的同一主题即算 CORRECT;时间类问题只要指向同一日期/时段即算 CORRECT('May 7th' 与 '7 May' 视为同一日期)。要求先给一句话理由,再以 JSON 格式
{"label": ...}只返回一个标签(同时含 CORRECT 与 WRONG 会破坏评测脚本)。
A.2 结果生成提示词模板(Mem0)(原样保留,注释为译注)
Prompt Template for Results Generation (Mem0)

You are an intelligent memory assistant tasked with retrieving accurate information from
conversation memories.
# CONTEXT:
You have access to memories from two speakers in a conversation. These memories contain
timestamped information that may be relevant to answering the question.
# INSTRUCTIONS:
1. Carefully analyze all provided memories from both speakers
2. Pay special attention to the timestamps to determine the answer
3. If the question asks about a specific event or fact, look for direct evidence in the
   memories
4. If the memories contain contradictory information, prioritize the most recent memory
5. If there is a question about time references (like "last year", "two months ago",
   etc.), calculate the actual date based on the memory timestamp. For example, if a memory
   from 4 May 2022 mentions "went to India last year," then the trip occurred in 2021.
6. Always convert relative time references to specific dates, months, or years. For
   example, convert "last year" to "2022" or "two months ago" to "March 2023" based on the
   memory timestamp. Ignore the reference while answering the question.
7. Focus only on the content of the memories from both speakers. Do not confuse character
   names mentioned in memories with the actual users who created those memories.
8. The answer should be less than 5-6 words.
# APPROACH (Think step by step):
1. First, examine all memories that contain information related to the question
2. Examine the timestamps and content of these memories carefully
3. Look for explicit mentions of dates, times, locations, or events that answer the
   question
4. If the answer requires calculation (e.g., converting relative time references), show
   your work
5. Formulate a precise, concise answer based solely on the evidence in the memories
6. Double-check that your answer directly addresses the question asked
7. Ensure your final answer is specific and avoids vague time references
Memories for user {speaker_1_user_id}:
{speaker_1_memories}
Memories for user {speaker_2_user_id}:
{speaker_2_memories}
Question: {question}
Answer:
译注:该模板指导"记忆助手"从两位说话者的带时间戳记忆中检索信息并作答:仔细分析全部记忆、特别关注时间戳;记忆矛盾时优先最新记忆;把相对时间表述("去年""两个月前")按记忆时间戳换算为具体日期(例:2022 年 5 月 4 日的记忆提到"去年去了印度",则旅行发生在 2021 年);不要把记忆中提到的角色名与真实用户混淆;答案须少于 5-6 词。提示末尾注入两位说话者各自的记忆与问题,要求按步骤思考后作答。
A.3 结果生成提示词模板(Mem0g)(原样保留;"(same as previous)" 表示上下文与指令部分与 A.2 相同,此处仅展示差异)
Prompt Template for Results Generation (Mem0g)

(same as previous)
# APPROACH (Think step by step):
1. First, examine all memories that contain information related to the question
2. Examine the timestamps and content of these memories carefully
3. Look for explicit mentions of dates, times, locations, or events that answer the
   question
4. If the answer requires calculation (e.g., converting relative time references), show
   your work
5. Analyze the knowledge graph relations to understand the user's knowledge context
6. Formulate a precise, concise answer based solely on the evidence in the memories
7. Double-check that your answer directly addresses the question asked
8. Ensure your final answer is specific and avoids vague time references
Memories for user {speaker_1_user_id}:
{speaker_1_memories}
Relations for user {speaker_1_user_id}:
{speaker_1_graph_memories}
Memories for user {speaker_2_user_id}:
{speaker_2_memories}
Relations for user {speaker_2_user_id}:
{speaker_2_graph_memories}
Question: {question}
Answer:
译注:与 A.2 的差异有二:思考步骤新增第 5 步"分析知识图关系(relations)以理解用户的知识上下文";提示末尾除两位说话者的记忆外,还各自注入其图记忆关系({speaker_*_graph_memories}),把图三元组与自然语言记忆一并提供给模型。
A.4 OpenAI ChatGPT 提示词模板(原样保留,对话示例为原文节选)
Prompt Template for OpenAI ChatGPT

Can you please extract relevant information from this conversation and create memory
entries for each user mentioned? Please store these memories in your knowledge base in
addition to the timestamp provided for future reference and personalized interactions.
(1:56 pm on 8 May, 2023) Caroline: Hey Mel! Good to see you! How have you been?
(1:56 pm on 8 May, 2023) Melanie: Hey Caroline! Good to see you! I'm swamped with the
kids & work. What's up with you? Anything new?
(1:56 pm on 8 May, 2023) Caroline: I went to a LGBTQ support group yesterday and it was so
powerful.
...
译注:用于把整段 LOCOMO 对话摄入 OpenAI ChatGPT 单一会话的提示:要求模型从对话中为每位被提及的用户抽取相关信息生成记忆条目,连同每条消息自带的时间戳一并存入其知识库,以供将来参考与个性化交互。其后附带的示例对话(Caroline 与 Melanie)每行均带时间戳前缀,原文以 "..." 省略其余部分。
附录 B:算法
算法 1:记忆管理系统——更新操作(伪码原样保留,# 后为中文译注)
Algorithm 1 Memory Management System: Update Operations

1:  Input: Set of retrieved memories F, Existing memory store M = {m1, m2, . . . , mn}
2:  Output: Updated memory store M′
3:  procedure UpdateMemory(F, M)
4:    for each fact f ∈ F do
5:      operation ← ClassifyOperation(f, M)   # 根据分类结果执行相应操作
6:      if operation = ADD then
7:        id ← GenerateUniqueID()
8:        M ← M ∪ {(id, f, "ADD")}           # 以唯一标识符把新事实加入记忆库
9:      else if operation = UPDATE then
10:       mi ← FindRelatedMemory(f, M)
11:       if InformationContent(f) > InformationContent(mi) then
12:         M ← (M \ {mi}) ∪ {(idi, f, "UPDATE")}  # 仅当新事实信息量更大时,替换既有记忆
13:       end if
14:     else if operation = DELETE then
15:       mi ← FindContradictedMemory(f, M)
16:       M ← M \ {mi}                        # 移除被新信息矛盾的记忆
17:     else if operation = NOOP then
18:       No operation performed              # 事实已存在或无关,不作任何操作
19:     end if
20:   end for
21:   return M
22: end procedure
23: function ClassifyOperation(f, M)
24:   if ¬SemanticallySimilar(f, M) then
25:     return ADD                            # 记忆库中不存在该新信息
26:   else if Contradicts(f, M) then
27:     return DELETE                         # 新信息与既有记忆冲突
28:   else if Augments(f, M) then
29:     return UPDATE                         # 新信息增强记忆库中的既有内容
30:   else
31:     return NOOP                           # 无需任何更改
32:   end if
33: end function
译注:算法 1 即正文 2.1 节所述更新阶段的完整流程。主过程 UpdateMemory 对检索到的每条事实 f 先经 ClassifyOperation 判定操作类型再执行:ADD 生成唯一 ID 后把 (id, f, "ADD") 并入记忆库;UPDATE 找到相关记忆 mᵢ,仅当新事实的信息量(InformationContent)大于既有记忆时才以 (idᵢ, f, "UPDATE") 替换;DELETE 找到被矛盾的记忆并移除;NOOP 不做任何操作。分类函数按"是否语义相似 → 是否矛盾 → 是否增强 → 否则"的顺序判定,与正文所述"由 LLM 通过工具调用在四种操作间决策"的实现相对应。
附录 C:所选基线
LoCoMo The LoCoMo framework implements a sophisticated memory pipeline that enables LLM agents to maintain coherent, long-term conversations. At its core, the system divides memory into short-term and long-term components. After each conversation session, agents generate summaries (stored as short-term memory) that distill key information from that interaction. Simultaneously, individual conversation turns are transformed into 'observations' - factual statements about each speaker's persona and life events that are stored in long-term memory with references to the specific dialog turns that produced them. When generating new responses, agents leverage both the most recent session summary and selectively retrieve relevant observations from their long-term memory. This dual-memory approach is further enhanced by incorporating a temporal event graph that tracks causally connected life events occurring between conversation sessions. By conditioning responses on retrieved memories, current conversation context, persona information, and intervening life events, the system enables agents to maintain consistent personalities and recall important details across conversations spanning hundreds of turns and dozens of sessions.
LoCoMo。LoCoMo 框架实现了一套精细的记忆流水线,使 LLM Agent 能维持连贯的长期对话。其核心是把记忆分为短期与长期两部分:每个对话会话结束后,Agent 生成摘要(存为短期记忆),蒸馏该次交互的关键信息;同时,各对话轮被转换为"观察(observations)"——关于每位说话者人格与生活事件的事实陈述,连同产生它们的对话轮引用一起存入长期记忆。生成新回复时,Agent 同时利用最近的会话摘要,并从长期记忆中选择性检索相关观察。这一双记忆方法还进一步引入一个时序事件图,追踪发生在对话会话之间的、有因果关系的生活事件。通过把回复条件化在检索到的记忆、当前对话上下文、人格信息与会话间的生活事件之上,该系统使 Agent 能够跨越数百轮、数十个会话的对话保持一致的人格并回忆重要细节。
ReadAgent ReadAgent addresses the fundamental limitations of LLMs by emulating how humans process lengthy texts through a sophisticated three-stage pipeline. First, in Episode Pagination, the system intelligently segments text at natural cognitive boundaries rather than arbitrary cutoffs. Next, during Memory Gisting, it distills each segment into concise summaries that preserve essential meaning while drastically reducing token count—similar to how human memory retains the substance of information without verbatim recall. Finally, when tasked with answering questions, the Interactive Lookup mechanism examines these gists and strategically retrieves only the most relevant original text segments for detailed processing. This human-inspired approach enables LLMs to effectively manage documents up to 20 times longer than their normal context windows. By balancing global understanding through gists with selective attention to details, ReadAgent achieves both computational efficiency and improved comprehension, demonstrating that mimicking human cognitive processes can significantly enhance AI text processing capabilities.
ReadAgent。ReadAgent 通过模拟人类处理长文本的方式来解决 LLM 的根本局限,采用精细的三阶段流水线。首先是情节分页(Episode Pagination):系统在自然的认知边界处智能切分文本,而非任意截断。接着是记忆要点化(Memory Gisting):把每个片段蒸馏为保留本质含义、同时大幅减少 token 数的简短摘要——类似于人类记忆保留信息实质而不逐字记住原文。最后,当需要回答问题时,交互式查找(Interactive Lookup)机制检视这些要点摘要,并策略性地只取回最相关的原文片段进行细致处理。这一仿人方法使 LLM 能有效处理比其正常上下文窗口长 20 倍的文档。通过"要点摘要提供的全局理解"与"对细节的选择性关注"相平衡,ReadAgent 同时达成计算效率与更好的理解力,证明模仿人类认知过程可显著增强 AI 的文本处理能力。
MemoryBank The MemoryBank system enhances LLMs with long-term memory through a sophisticated three-part pipeline. At its core, the Memory Storage component warehouses detailed conversation logs, hierarchical event summaries, and evolving user personality profiles. When a new interaction occurs, the Memory Retrieval mechanism employs a dual-tower dense retrieval model to extract contextually relevant past information. The Memory Updating component, provides a human-like forgetting mechanism where memories strengthen when recalled and naturally decay over time if unused. This comprehensive approach enables AI companions to recall pertinent information, maintain contextual awareness across extended interactions, and develop increasingly accurate user portraits, resulting in more personalized and natural long-term conversations.
MemoryBank。MemoryBank 系统通过精细的三部分流水线为 LLM 增强长期记忆。核心的记忆存储(Memory Storage)组件保管详细的对话日志、分层的事件摘要与不断演化的用户人格画像。当新交互发生时,记忆检索(Memory Retrieval)机制采用双塔稠密检索模型抽取与语境相关的过往信息。记忆更新(Memory Updating)组件则提供一种仿人的遗忘机制:记忆在被回忆时强化,长期不用则自然衰减。这一综合方法使 AI 伙伴能回忆相关信息、在长期交互中保持语境感知、并发展出越来越准确的用户画像,从而带来更个性化、更自然的长期对话。
MemGPT The MemGPT system introduces an operating system-inspired approach to overcome the context window limitations inherent in LLMs. At its core, MemGPT employs a sophisticated memory management pipeline consisting of three key components: a hierarchical memory system, self-directed memory operations, and an event-based control flow mechanism. The system divides available memory into 'main context' (analogous to RAM in traditional operating systems) and 'external context' (analogous to disk storage). The main context—which is bound by the LLM's context window—contains system instructions, recent conversation history, and working memory that can be modified by the model. The external context stores unlimited information outside the model's immediate context window, including complete conversation histories and archival data. When the LLM needs information not present in main context, it can initiate function calls to search, retrieve, or modify content across these memory tiers, effectively 'paging' relevant information in and out of its limited context window. This OS-inspired architecture enables MemGPT to maintain conversational coherence over extended interactions, manage documents that exceed standard context limits, and perform multi-hop information retrieval tasks—all while operating with fixed-context models. The system's ability to intelligently manage its own memory resources provides the illusion of infinite context, significantly extending what's possible with current LLM technology.
MemGPT。MemGPT 系统引入一种受操作系统启发的方法,以克服 LLM 固有的上下文窗口限制。其核心是一套精细的记忆管理流水线,由三个关键组件构成:分层记忆系统、自主导向的记忆操作与基于事件的控制流机制。该系统把可用记忆分为"主上下文(main context)"(类比传统操作系统中的内存 RAM)与"外部上下文(external context)"(类比磁盘存储)。主上下文——受 LLM 上下文窗口约束——包含系统指令、近期对话历史与可被模型修改的工作记忆。外部上下文则在模型即时上下文窗口之外存储无限信息,包括完整对话历史与归档数据。当 LLM 需要主上下文中不存在的信息时,它可以发起函数调用,跨这些记忆层级搜索、检索或修改内容,从而有效地把相关信息在自己的有限上下文窗口内外"换页"。这一仿 OS 架构使 MemGPT 能在长期交互中保持对话连贯、管理超出标准上下文上限的文档、并执行多跳信息检索任务——而这一切都在固定上下文的模型上完成。该系统智能管理自身记忆资源的能力营造出"无限上下文"的错觉,显著拓展了当前 LLM 技术的边界。
A-Mem The A-Mem model introduces an agentic memory system designed for LLM agents. This system dynamically structures and evolves memories through interconnected notes. Each note captures interactions enriched with structured attributes like keywords, contextual descriptions, and tags generated by the LLM. Upon creating a new memory, A-MEM uses semantic embeddings to retrieve relevant existing notes, then employs an LLM-driven approach to establish meaningful links based on similarities and shared attributes. Crucially, the memory evolution mechanism updates existing notes dynamically, refining their contextual information and attributes whenever new relevant memories are integrated. Thus, memory structure continually evolves, allowing richer and contextually deeper connections among memories. Retrieval from memory is conducted through semantic similarity, providing relevant historical context during agent interactions.
A-Mem。A-Mem 模型为 LLM Agent 引入了一套 Agent 式(agentic)记忆系统。该系统通过相互关联的笔记(notes)动态地组织并演化记忆。每条笔记记录的交互都带有由 LLM 生成的结构化属性,如关键词、语境描述与标签。创建新记忆时,A-Mem 用语义嵌入检索相关的既有笔记,再采用 LLM 驱动的方法,基于相似性与共享属性建立有意义的链接。至关重要的是,其记忆演化机制会动态更新既有笔记——每当新的相关记忆被整合进来,就细化其语境信息与属性。如此,记忆结构持续演化,使记忆之间形成更丰富、语境更深的连接。记忆检索通过语义相似度进行,在 Agent 交互过程中提供相关的历史上下文。
要点速览
- Mem0 把记忆管理建模为两阶段流水线:抽取阶段结合异步刷新的对话摘要 + 最近 m=10 条消息抽取显著事实;更新阶段检索 top-10 相似记忆后由 LLM 工具调用决策 ADD/UPDATE/DELETE/NOOP。
- Mem0g 将记忆表示为有向标签图 G=(V,E,L):实体为节点、关系为三元组,配备实体抽取器与关系生成器两阶段 LLM 抽取;过时关系被标记失效而非删除,以支持时序推理。
- 检索双路设计:实体中心(定位锚节点后探索出入边构建子图)+ 语义三元组(查询向量与全部三元组的相似度匹配),兼顾实体聚焦型与概念型查询。
- LOCOMO 基准:10 段长对话、平均每段约 600 轮 / 26,000 token / 200 道题,分单跳、多跳、时序、开放域四类;词法指标(F1/BLEU-1)会掩盖事实错误,故以 LLM-as-a-Judge 为主指标(10 次运行取均值±标准差)。
- 主要战绩:Mem0 单跳 J=67.13、多跳 J=51.15 均为最佳;Mem0g 时序 J=58.13 最佳;开放域由 Zep(76.60)以 0.89 分微弱领先 Mem0g(75.71)。
- 总分排序:全上下文 72.90 > Mem0g 68.44 > Mem0 66.88 > Zep 65.99 > 最佳 RAG ≈61 > OpenAI 52.90;相对 OpenAI 记忆功能,Mem0 的 J 有 26% 相对提升。
- 效率是核心卖点:相比全上下文(p95 总延迟 17.117s、约 26k token),Mem0 p95 仅 1.440s(降 91%+)、检索延迟全常最低(p50 0.148s);LangMem 检索 p50 高达 17.99s 基本不可交互。
- 记忆库开销:Mem0 平均约 7k token/对话、Mem0g 约 14k,而 Zep 的记忆图超过 600k token(每个节点缓存完整摘要导致 20 倍于原文的冗余)。
- 图记忆不是万能药:Mem0g 在单跳、多跳上不升反降,仅在时序与开放域等需要关系推理的场景体现优势——记忆结构应与推理需求匹配。
- 工程启示:好的 Agent 记忆 = 有选择地存(抽取)+ 及时地合(更新/冲突消解)+ 快速地取(稠密检索),并把部署指标(token、p50/p95 延迟)与准确率同列为一级指标。
🖼 原文图表(5 张)—— 提取自原始文献,点击展开
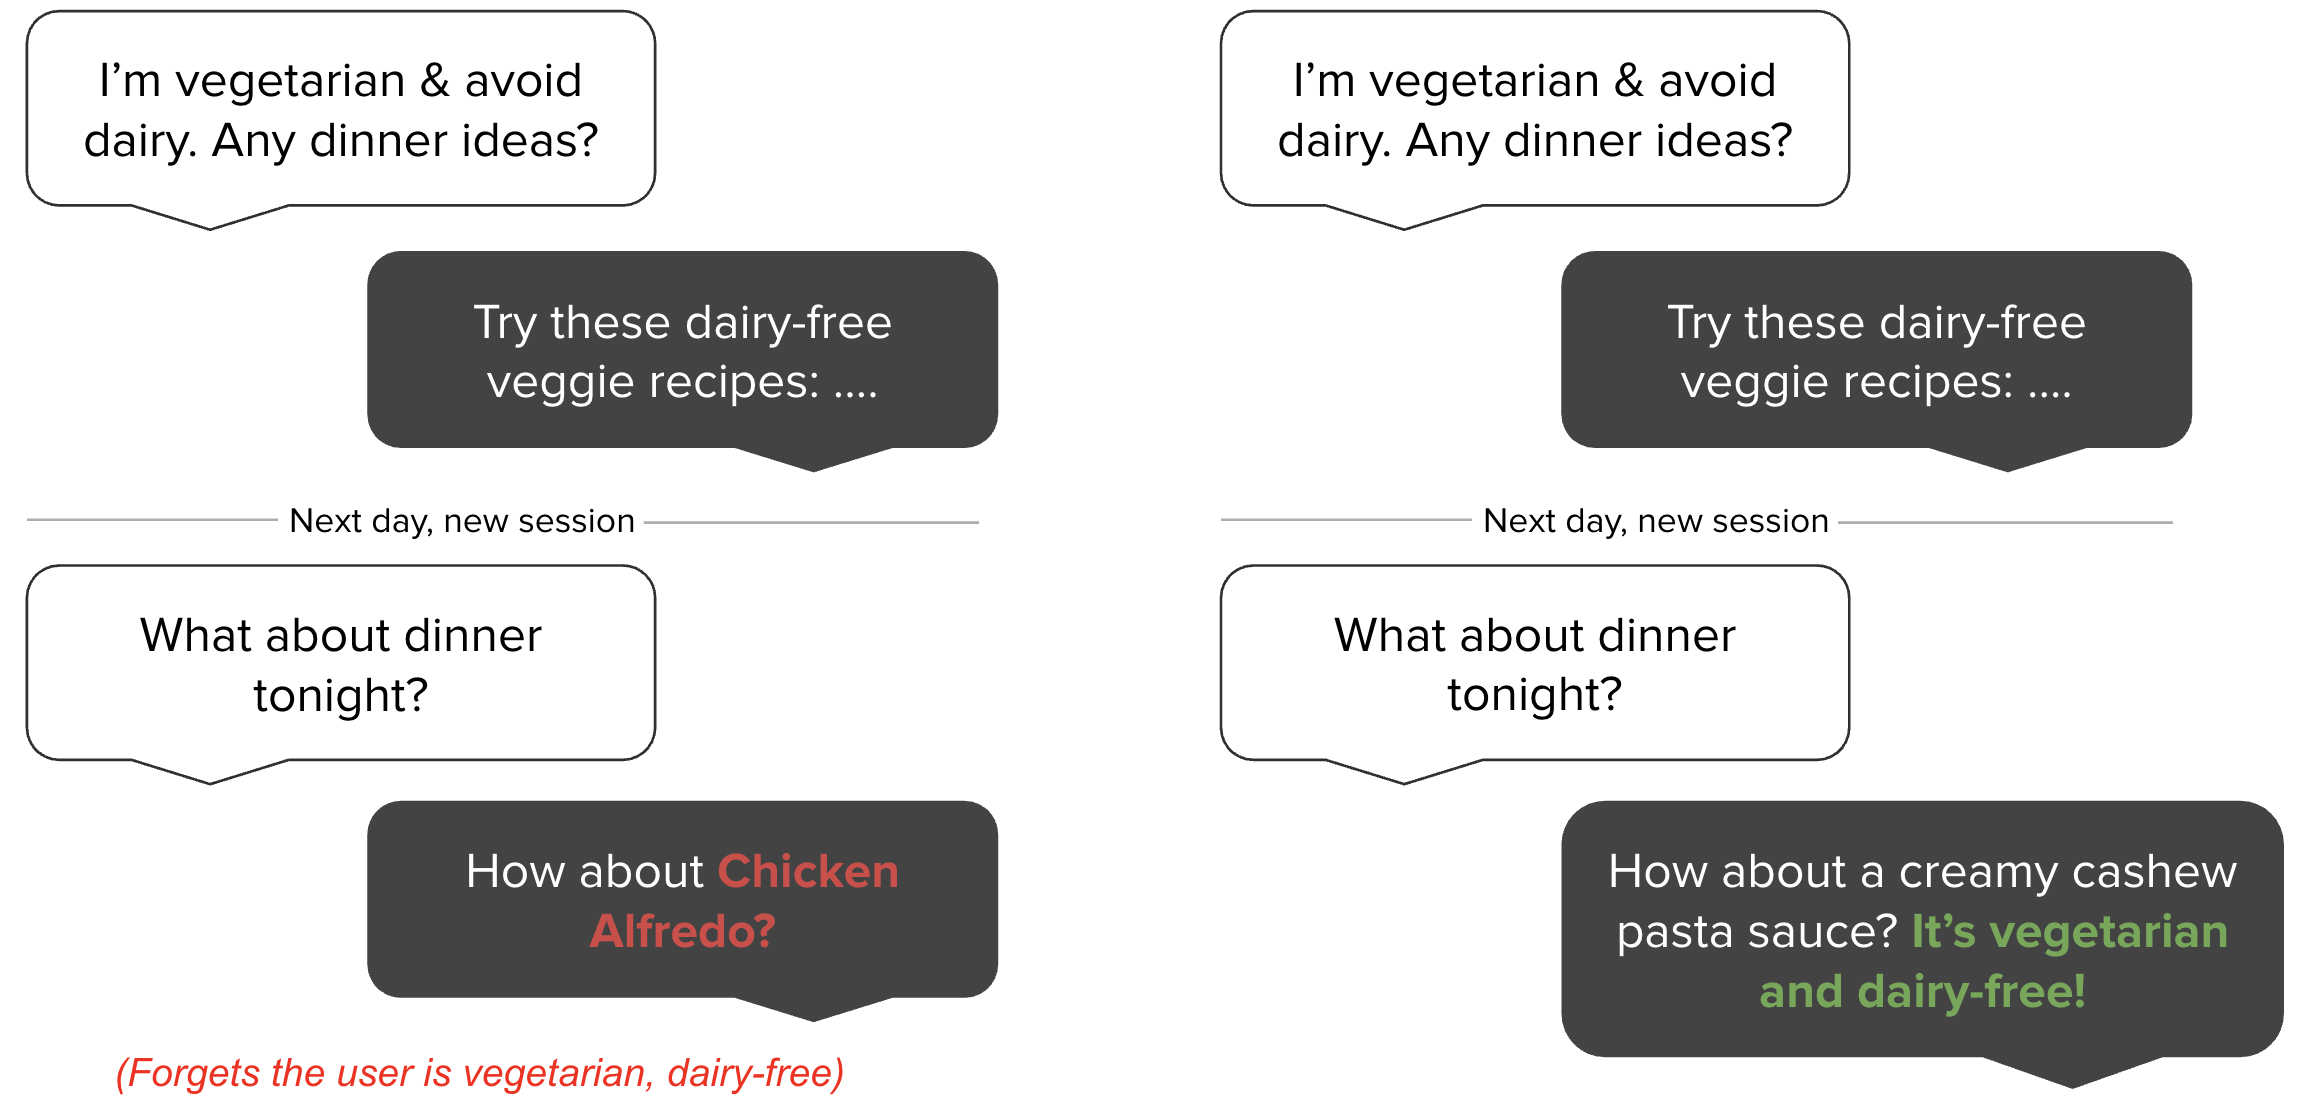
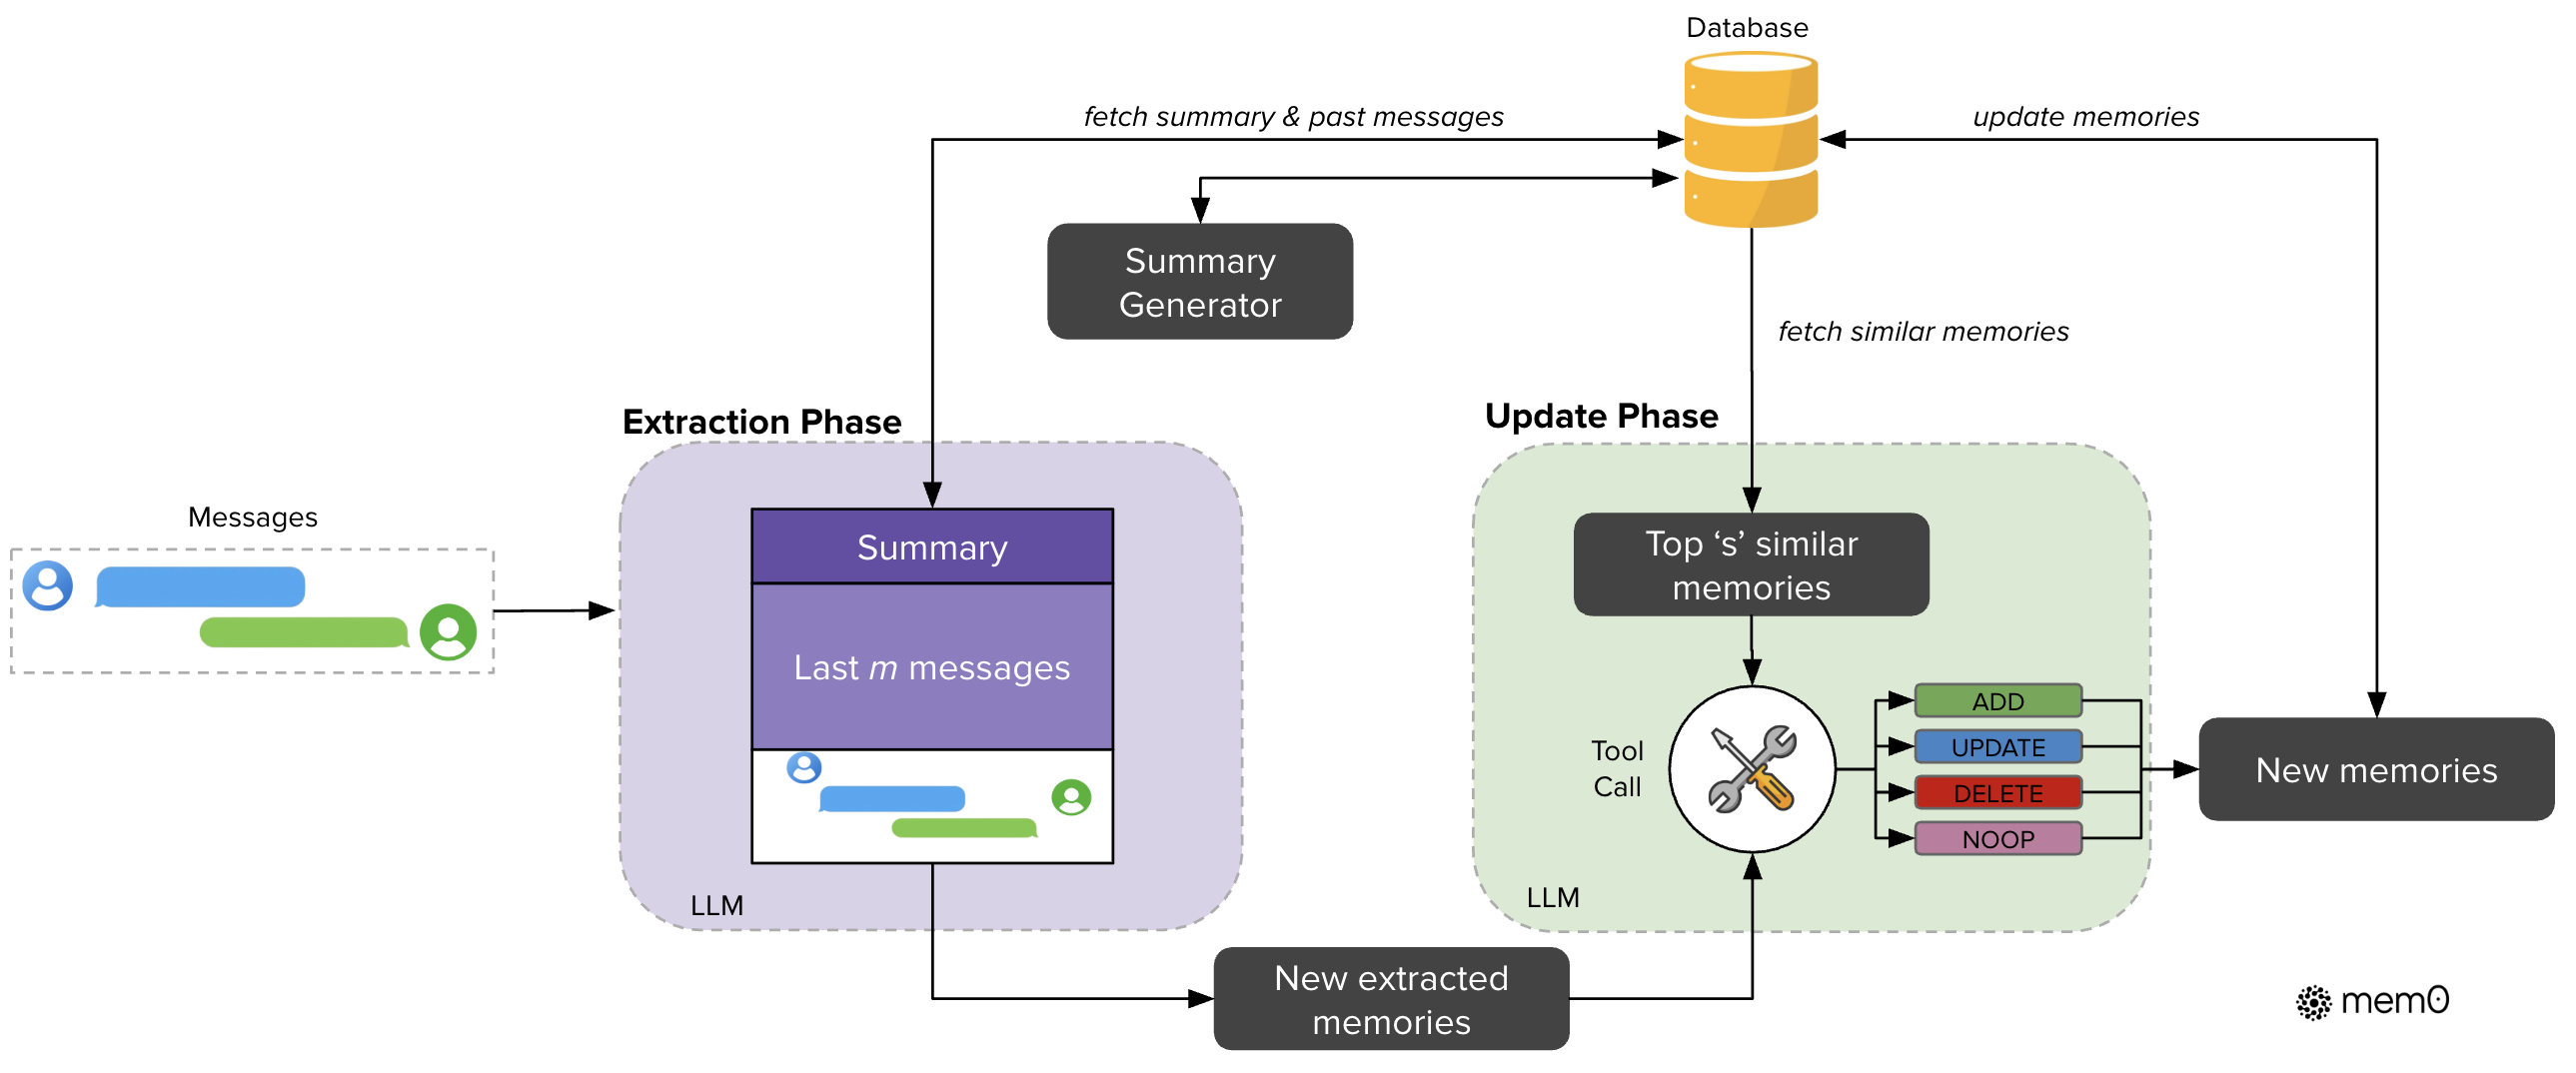
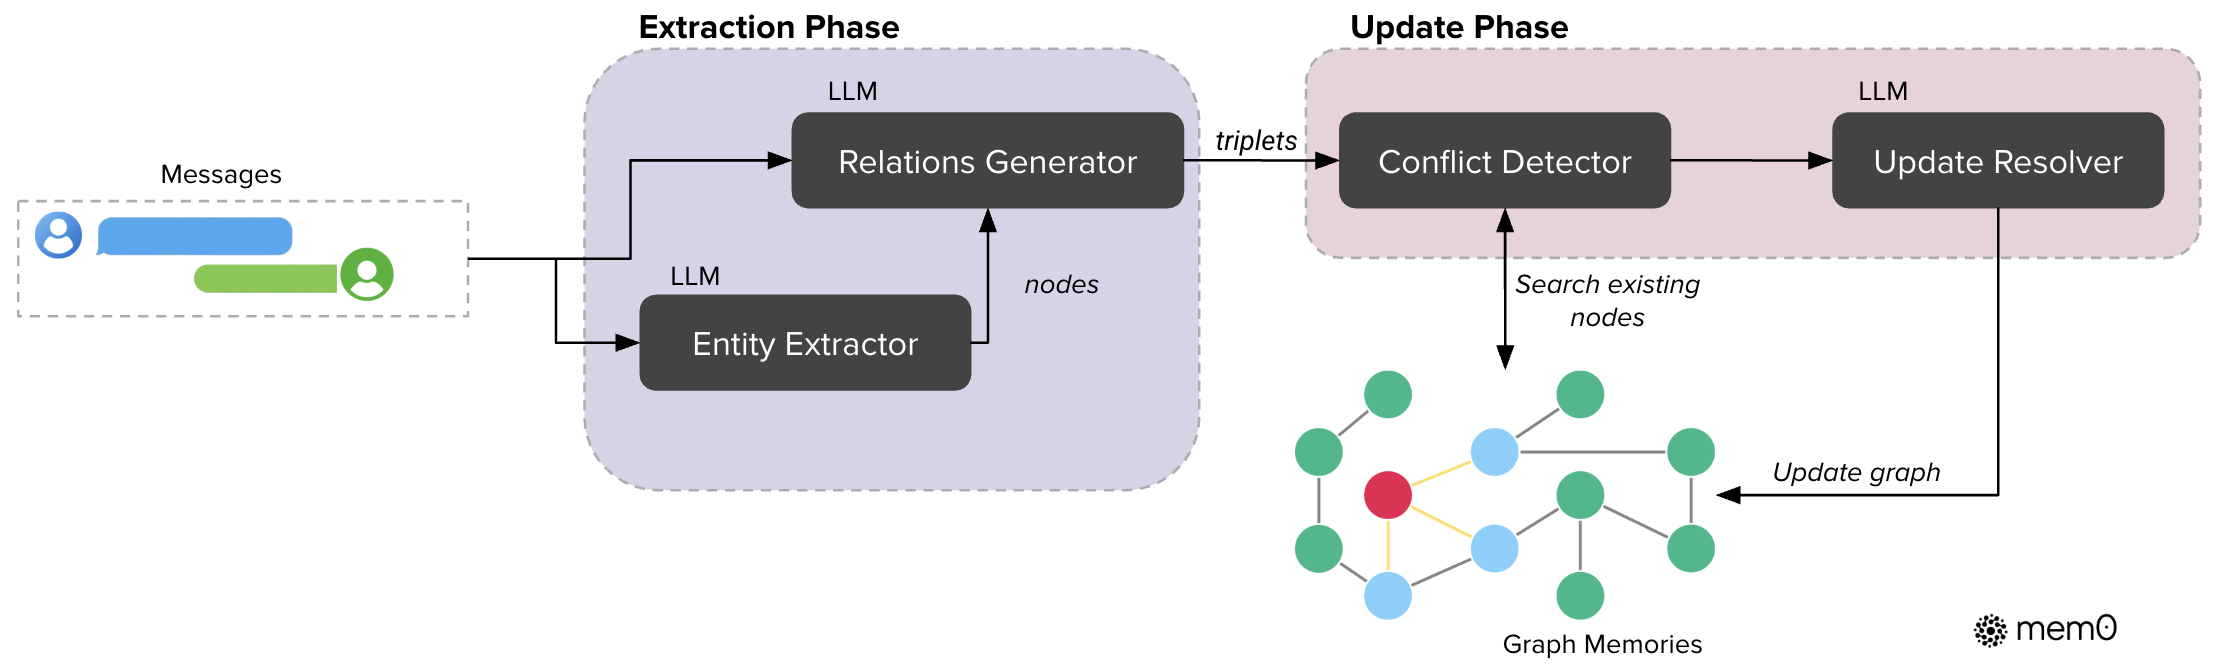
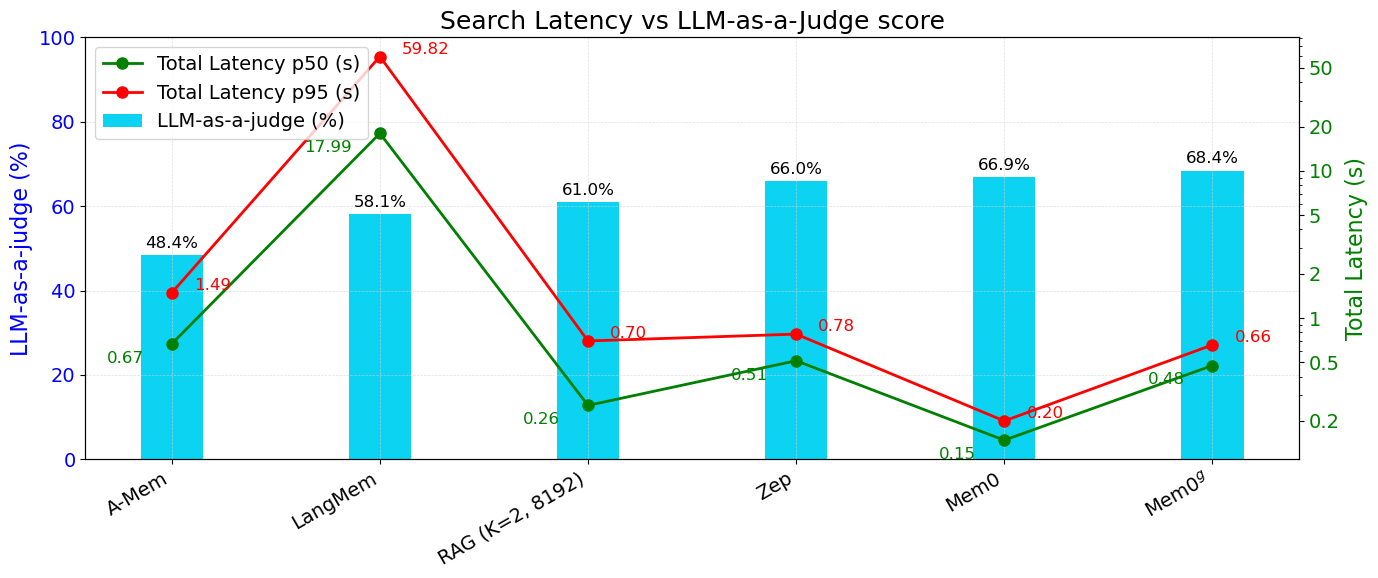
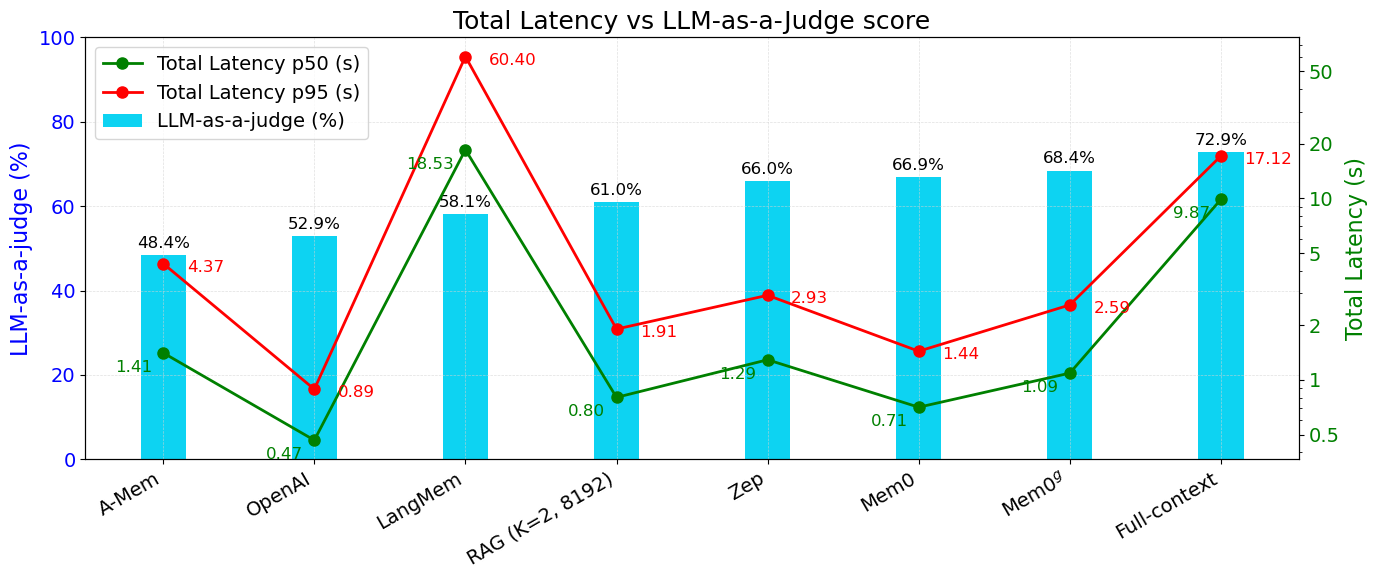
以上图片提取自原始 PDF/网页或 arXiv 官方 HTML 版(含矢量图与原始图注),已镜像至本站;与正文的对应关系请以原文为准。